Apple, in a Developer News post I am reproducing in its entirety, segment-by-segment:
We give developers powerful APIs to build incredible capabilities into their apps for Apple products, backed by a set of controls designed to protect users’ private data. Full Disk Access largely sidesteps these controls in order to allow backup apps to function properly on the Mac.
As John Voorhees writes, the uses of Full Disk Access go well beyond the category of backup apps, and it is worrisome to see Apple give it such a limited frame. I have given that permission to disk management utilities, Sketch, Terminal, and other apps I do not want to be throwing permissions requests as I move around my drives. Is Apple suggesting this capability could be limited in the future to backup applications alone? I do not like that.
Some developers are using Full Disk Access in ways that could put users at risk, exposing everything on their systems — including files, mail, messages, and even browsing history — without users’ full knowledge and understanding.
This seems very clearly a response to Jason Aten’s claim, in Inc, that Meta’s Muse agent software accessed and uploaded his Messages database without permission. This story is, as of writing, still confusing to me because Aten does not clearly describe the circumstances.
Full Disk Access is required because the Messages database is protected by MacOS. Giving Muse this permission is one of two prerequisites. The other, according to Meta’s Andy Stone, is something called the Messages Connector. Aten says he “had explicitly declined to connect Messages” but when he “looked at Muse’s settings afterward, Messages was enabled” anyway. In a follow-up article, Aten suggests he turned on Full Disk Access, then turned it off — though he does not say this explicitly — after which Muse was still able to read Messages data. If so, it indicates a possible MacOS security problem. But I must stress that I am confused by Aten’s description of the chain of events. As I was (slowly) putting this article together, Jeff Johnson attempted to reproduce the circumstances of Aten’s articles as he, like me, found the description confusing. As Johnson writes, “if Muse uploaded Aten’s Messages database, as he claims, then Aten granted Full Disk Access to Muse at some point. There’s no other plausible explanation”.
Regardless, we now have a wave of poorly regulated and frequently misconfigured software that scoop up user data with barely any notice, so Apple says — as you will read later — that it is stepping in to curb a likely vector for unintended consequences in Full Disk Access. However, it provides no details on what these additional restrictions will look like for users. It could be something as minor as a sterner dialog box, but I do not see a reason why Apple would issue a warning about a change like that.
Because of the lack of information available at present, I do not want to get too far ahead of myself, but I am concerned that it could be a significant curtailing of application permissions. It has the potential for further self-preferencing, as Apple will surely exempt Siri from the kinds of permissions requests it requires of third-party apps, even as it is updated with additional capabilities. In MacOS Golden Gate, for example, apps must be excluded if you do not want Apple Intelligence or Siri to have access. This makes sense inasmuch as Apple trusts itself, and users have agreed to its software license agreement and privacy policy. But an aggressive policy against broad access also means third-party software will be further disadvantaged on MacOS. Meta is, thanks to feeble government regulations and a seemingly skeezy management culture, the last company whose agent I would trust to run rampant across my system. But suppose there was an agent I felt comfortable using and felt like there was a reason to do so. No matter its potential capabilities, it would struggle to compete with Siri because of how privileged and integrated the latter already is — and now consider how much more difficult it would be if Full Disk Access were kneecapped.
One might argue that it is hardly a surprise since Apple has been promoting its unique “personal context” advantage since it began marketing Apple Intelligence in 2024. And Siri has always been privileged: since Apple integrated it with the iPhone 4S, it has been able to send and read text messages, emails, and more. Apple Intelligence and Siri are just another part of the system — part of the whole widget. And that “whole widget” stance cuts both ways. Not only does it affect users on Apple’s hardware, it also means Apple does not treat Apple Intelligence or Siri as software it will bring to other platforms. Apple is only competing in this market on its own products, which means its virtual assistant has a platform-level market share of basically 100%, and not because it has outcompeted any rivals.
Call me a naïve little baby if you want, but I do not think preserving Siri’s dominance on Apple’s devices is the company’s reason for locking down Full Disk Access. But Apple’s existing restrictions are part of the reason Siri was awful for a decade. If it had the opportunity to compete with third-party replacements, I doubt it would have languished in a miserable state for as long as it did. I cannot imagine people have been choosing Apple’s products to get Siri. Perhaps virtual assistants and agents will become important enough to people that they will become a factor in hardware purchasing decisions. Maybe that could even mean the development of newer platforms to compete at a higher level. But I worry about the likelihood of incumbent platform owners — the kind the European Commission has called “gatekeepers” — using privacy and security arguments to curtail possible competition.
Back to Apple:
For communication apps, this can also compromise the privacy of the people users are communicating with.
You know what else could compromise communications privacy? iCloud. By default, device backups include a user’s Messages conversation history in a format Apple can decrypt. Users must turn on Advanced Data Protection, enabling true end-to-end encrypted backups, but their conversation partners may not, undermining its effectiveness.
Going forward, we will introduce additional controls to ensure that users who genuinely wish to grant an app this extraordinary level of access can only do so with very explicit user action. Addressing this is critical. As AI agents become increasingly capable and autonomous, the risks associated with this level of access will grow substantially. We are committed to ensuring users clearly understand these risks before granting such access, so they can make informed decisions about their own data and privacy.
This is an issue of platform owners playing a regulatory role that should be occupied by actual lawmaking. People should not need to worry that granting Full Disk Access to software made by a well-known company will produce a result indistinguishable from malware. We have been through this before. In 2012, the iOS app Path was caught uploading users’ contacts without explicit permission for its friend finding feature. There was theoretically nothing to prevent other iOS apps from abusing their access to the Photos library, either. All of these things are now gated behind App Store moderation on iOS, Full Disk Access on MacOS, and permission request sheets on both platforms.
It worries me that this nascent and seemingly niche world of agents is going to be another thing for users to understand and platforms to control. But, then again, I also have to wonder if the reasons I use Full Disk Access are perhaps a smaller niche. I just hope Apple’s response to this does not spoil my personal use, nor should it be a further gate to keep.
One of the things I was most looking forward to when Apple announced it was moving to a new connector in the iPhone was the prospect of faster data transfers. It had been years since this new USB specification was finalized, and Apple was already supporting it in its newest computers, so it seemed predestined the new iPhone would get it, too.
That was the naïve view I had in 2012. That September, Apple announced the iPhone 5 and, alongside it, the Lightning connector. Like the 30-pin “iPod” connector it replaced, it was limited to 480 Mbps as defined in the USB 2.0 spec. Surely I would not be fooled again next time Apple switched the iPhone connector.
Right?
Alas, while all models in the iPhone 15 line were equipped with a USB-C connector, only the top-of-the-line Pro models were capable of USB 3.1 speeds. Maybe that is because the standard iPhone 15s used the A16 SoC of the previous year’s Pro models, neither of which supported the faster USB spec. But that does not explain why the successors — the regular iPhone 16s — also only supported USB 2.0 speeds over their connector, as did the iPhone 17. And it really does not explain why the iPhone Air, which has essentially the same processor as the iPhone 17 Pro, is also limited to a pathetic USB 2.0 transfer speed.
USB 2.0, by the way, became a standard a full 25 years before the iPhone Air’s release. If the original iPhone had shipped with an ADB-based connector, it would have been using what was then a more recent protocol for a wired connection than the iPhone Air did when it came out.
Perhaps Apple would justify its USB 3.1 selectivity in reverse. The 10 Gbps transfer speeds capable with its recent Pro models are necessary for recording ProRes video to an external hard disk, after all, and professional video codecs are only available on the Pro model iPhones; ergo, those are the only iPhones that need a fast USB controller. But that is no longer an accurate reason, either, because there is now an iPhone which can do 10 Gbps USB transfers but has none of the professional camera technologies. It is the iPhone Duo. And that gives me hope that the rest of the iPhone line will catch up.
Maybe that is because it would be truly embarrassing to release an iPhone model with an $800 USD premium that had a USB 2.0-level connection. And, yes — it would be embarrassing, but the kind of embarrassing Apple could smooth over with a statement to friendly websites about how it is a capability that was intended for pro video applications and, anyway, nobody transfers data over a wire these days.
I am one of the few: I still transfer data over a wire, and I like it that way. Also, given Canadian pricing, I would like to buy a regular iPhone next time I upgrade. The only reason now to keep USB 3.1 speeds away from the lower-grade models is simply as a product segmentation tactic. That is entirely possible — likely, even. If I had to gamble on whether the iPhone 18 will have a connector supporting USB 3.1, I would bet against it. But this is the first time I have had hope that it may — finally — happen.
It remains a mystery to me why this has taken so long. Outside of the Apple ecosystem, USB 3 has been table stakes for over a decade. Apple shipped three iPad models with support for USB 3 over Lightning, too, so it is not like this stuff was impossible on an iPhone. It is baffling. It feels absurd to write this in 2026 speculating about a phone that will likely be released next year about a spec that was finalized thirteen years ago. But it seems possible that, at last, Apple’s plain-Jane iPhone will inherit the fifth-fastest USB standard around. Hallelujah.
Last month, within a day of each other, two writers published contrasting takes regarding the backlash to artificial intelligence and its infrastructure. I do not think they were knowingly writing in opposition to each other — the second does not reference the first — but they set up the titular question I find intriguing: will the public backlash toward data centres be sustained?
It’s almost funny to think back to the mild wave of public consternation and Congressional wrist-slapping that pundits termed “the techlash” in the heady days of the first Trump administration, over concerns of disinformation on Facebook and social media, compared to what we’re seeing now. That is, a genuine, sustained demonstration of rage at some of the modern tech industry’s key aims.
And all of this has become so clear, so palpable, and so widespread that it’s apparently causing tech industry leadership and pro-AI policy wonks to enter either a state of denial or something more akin to fevered delusion.
Merchant lists a few things opposed by people in the U.S. in a broad and non-partisan way. One of them is data centres — particularly the massive ones powering today’s generative A.I. services.
Andrew Sharp, who is part of the Stratechery extended universe, the following day expressed doubts about not only the longevity of that opposition, but also its sincerity:
But I wouldn’t over-read this moment, either. This comes back to my lack of alarm about the long run implications. While it’s certainly true that a nihilistic sort of populism is on the rise in both parties and de-growth impulses are especially common on the left—two trends that aren’t going away—it’s worth keeping in mind that policy movements that draw their momentum from stuff people are saying on social media often lose steam just as quickly as they seemed to accelerate to the forefront of every political conversation in the country. Or to put it differently: of all the things that have taken their turn as The Current Thing, the track record for sustained outrage or support is not great. No one talks about de-funding the police anymore, Donald Trump is not building the wall, no one is flying Ukrainian flags today (well, except my parents), the MeToo movement is now seen as excessive in a variety of ways, and Alexandria Ocasio-Cortez, who today sponsors a bill to impose a federal moratorium on data center buildouts, recently made news for blithely admitting, “Woke 1 was crazy.”
I guess I should first address the incidents of activism that have apparently fizzled out. Fewer people may be talking about “de-funding the police”, but a U.S. Gallup poll published in July found confidence in police is lower now than it was in June 2020. Meanwhile, the Trump border wall was not a “movement [driven by] stuff people are saying on social media”, but instead a policy that has been revitalized under his second administration — one that has been augmented by a violent and illegal deportation policy that has resulted in several murders. This has resulted in net public favourability of Immigration and Customs Enforcement, another form of “police”, falling below that of any agency except the Internal Revenue Service, according to Gallup. Meanwhile, I am curious who, exactly, thinks the “MeToo movement is now seen as excessive in a variety of ways”.
Alas, it is conceivable that loud public fury over data centres will become quieter and less urgent, though not necessarily because people will grow to like or even accept this infrastructure. Construction could proceed on large-scale projects regardless of public reception. In Louisiana, for example, not only is Meta’s massive data centre project moving along, “state utility regulators overturned a judge’s order to make [calculations about] job projections and electricity needs” public, according to the Louisiana Illuminator. That certainly is one way to blunt criticism of a project. On that, there is ample precedent; Sharp:
In lieu of offering obvious advice, I’m more interested in cultural observation. Many have cited the 5G panic as a parallel for the kind of mass delusion around data center harms that has taken root this year, but personally, I think back to the conversations we used to have about fracking for oil and natural gas. That, too, was once branded as a uniquely harmful practice that imperiled our water supply, and while there were isolated incidents in which that was true, Obama’s EPA found that as a general matter those fears were overblown (although the agency later softened its exculpatory language after receiving criticism from activists and scientists).
[…] most importantly, Americans who once opposed fracking don’t care or even notice. There was never any grand public debate where one side won and the other lost; the work got done in spite of vocal critics, and then the critics mostly forgot about it.
For completeness, the “exculpatory language”, as Sharp puts it, in the fracking report was inserted late in the draft stage, and was objected to by the EPA’s Science Advisory Board. Sharp may cast aside such concerns as the mere opinions of “activists and scientists”, but the outcome touted by the petroleum industry from this EPA report was undercut several years later.
Whether Sharp realizes it or not, the fracking public relations playbook is exactly what people like asset manager Dan Clifton argues data centre developers and A.I. companies ought to be pulling from. Josh Brown, the host and another finance guy, says this was a relatively easy argument for the fracking industry to make because “the answer is obvious: two-dollar natural gas”. Clifton responds by admitting that “one of the problems [with data centres] is they don’t create a lot of jobs. There’s not a lot of construction jobs, and there’s definitely not jobs inside the data centre itself. So you’ve got to make it about property taxes”. Even these boosters recognize the favourable arguments are pretty limited. “You know what would be a good argument?”, Brown asks, “hey, it’s this or a nuclear power plant”.
Clifton’s framing — and Sharp’s, for that matter — kind of rests on people in the U.S. viewing fracking favourably. According to Pew (PDF), however, just 45% of Americans supported more fracking when polled in spring 2025, while 51% were opposed. Nuclear power was considerably more popular, with 59% saying they wanted more of it in the U.S., though nothing came close to solar at 77%. Notably, support for fracking has grown only a little from a low of 37% in spring 2020; solar, meanwhile, has declined from near-universal favourability at 92% in 2019, for seemingly no reason other than political waves. The Pew survey is not an outlier, either: a 2025 meta analysis found fracking, here treated as a category of natural gas production, was perceived negatively overall and in a number of specific categories. So, contrary to Sharp’s insistence that “Americans who once opposed fracking don’t care or even notice”, this Pew survey actually shows how public aversion has lingered despite easy financial arguments and a growing albeit troubled industry.
But while the U.S. public is not convinced about fracking despite its proliferation, there seem to be few high-profile protests. That is true of many things. There is finite energy to throw behind any one thing, and there are so many worthwhile things. Passionate voices are often not well received but any reaction is better than being ignored. And we are in an era of democratically elected governments that seem to be content with paying little attention to the broader public. In fact, this seems to be what Sharp approves of:
So midterms will come and go. Opportunistic states like Texas will find a way to return to building. As entertaining or distressing as the current panic has been, the future of American AI infrastructure will not in fact be relocated to the UAE or outer space. Some of this controversy will probably be revived for a presidential election in 2028, but I expect the incentives for both companies building data centers and local governments attracting them will stubbornly prevail. And over time, voters won’t care.
The question is not whether voters will care. The question is whether policymakers, regulators, and big corporations will listen.
As Merchant wrote:
What’s happening, after all, is pretty simple: Tech companies have encroached into Americans’ personal lives and public spaces, with both development projects and surveillance products, and people find the tradeoffs unacceptable. It’s really not complicated. Data centers, Flock cams, and AI glasses have been thrust into the public sphere by tech companies, with little to no preceding democratic input, and they are being rejected with extreme prejudice, because people do not like what these things do or what they represent. There is an additional layer of anger because people feel that they weren’t consulted; these vast infrastructural buildouts and high tech privacy violators pretty clearly tap into a shared sense of resentment and powerlessness.
Protests and demonstrations are supposed to get attention for a cause. In the best case, a movement may become quieter because people with power actually listen to the voices of their constituents. The anti-nuclear movement has resulted in a steady decline of nuclear warheads, which — coincidentally or not — peaked in 1986, the same year as the disaster at Chernobyl. There are fewer public demonstrations against nuclear weapons today, undoubtedly in part because people were so vehemently and loudly opposed forty and fifty years ago.
I am skeptical of the likelihood of sustained public backlash of the type documented by Merchant, however. When media coverage treats it as an old story — see: fracking — enthusiasm toward and awareness of the opposition will wane. But that does not mean the movement will have been unsuccessful.
For years, companies like Amazon, Google, and Microsoft blanketed the Earth in data centres with little public awareness. These buildings — which now seem small despite their preposterous scale — have powered websites and apps for decades with barely a ripple, though they share many of the same problems as their contemporary cousins. If the ultimate outcome of activists is that more people understand more about how technology works, that is a degree of success.
The defining questions of our age are who will have access to superintelligence and what will we direct it towards. Will it be centralized and restricted to a few institutions, or will it be a tool that empowers everyone?
We propose a philosophy based on individual empowerment as the source of prosperity, invention as the primary purpose of superintelligence, and balance of power as the foundation of safety.
The themes of this essay are reminiscent of those in the “Personal Superintelligence” one Zuckerberg published a year ago. It has the same aspirational messaging about empowering individuals with decentralized superintelligence, the same acknowledgement of the new risks of this technology, and the same total reluctance to define “superintelligence” in any meaningful sense. The term appears 55 times in his latest essay, not one of which explains what it actually is. I suppose it must be synonymous with generative A.I. but the beauty of a proprietary term like this one is in its flexibility.
What I would like to focus on are the specific references Zuckerberg makes to studies, initiatives, or plain anecdotes. Despite the word count, there are few concrete references; much of this is about visionary concepts, not grounded reality. Despite their paucity, Zuckerberg also provides no links or citations, making it particularly difficult to track down the source of claims like this one (emphasis mine):
People fear that automation will outpace individuals’ capability growth, leading to job displacement followed by a difficult period as people learn new jobs. But there is no rule that AI must increase automation faster than it increases individuals’ capabilities or demand for new skills. Recent statistics suggest it may be more likely that individuals’ capability growth could match or outpace automation, in which case people will gain the ability to do many new things before their current jobs change. This would lead to a healthy balance and potentially even job growth.
What this actually refers to I have no idea. There is enough hedging — “recent”, “suggest”, “may be”, “likely” — that it kind of means nothing at all. What I think Zuckerberg is saying in this paragraph is that people can learn new things faster than A.I. can take jobs, but I could not find “recent statistics” backing this up.
There are some relevant observations, though. A June research note (PDF) from the Stanford Digital Economy Lab found, using data from ADP payroll services, that automation-friendly entry-level positions saw employment declines since the November 2022 launch of ChatGPT. Meanwhile, a report published by PWC in June (PDF) suggested increasing wages and employment in jobs that could be automated, even at the entry level. One possible difference is in methodology; while Stanford’s information came from payroll data, PWC’s was from job ads. PWC’s findings were also highly sector-dependent, and indicate entry-level jobs now require more skills to compete with automation. I think PWC’s report is the closest match to what Zuckerberg is arguing, but it is difficult to know for sure. Also, how exactly are young people fresh out of school supposed to develop skills like “team building” and “stakeholder management” before they can be hired?
Here is another anecdote from Zuckerberg’s essay, this time about how Meta is committed to building its physical A.I. infrastructure to support “high-paying local jobs, investment in schools and public services, ensuring energy prices don’t rise, and taking care of the environment”:
For example, in Richland Parish, Louisiana, where Meta is building a large data center, teachers received a $50,000 bonus this year because of the increased tax revenue from our investment. The superintendent told us that teachers are now moving there from across the country and he believes it will become one of the nation’s best school districts.
This is true, but elides the reasons why teachers are somehow getting bonus cheques from a data centre construction project they have nothing to do with. Reporting about this for the New York Times, Jacey Fortin writes that this undeniably exciting windfall is due to a “decades-old ordinance that directs 1 percent of local sales tax revenue to educators”. However:
But many of the workers are likely to leave in the next few years, ending the tax boom. And the Meta payment, which amounted this year to about $22 million, represents only a fraction of the taxes that a company would normally pay to build in the area.
Meta’s tax bill should be over nine times the amount it actually pays, and it will drop precipitously when construction is complete. But Meta made backroom negotiations to get all kinds of concessions and incentives to build its enormous data centre in the region. If the tax breaks had not been implemented and Meta constructed the data centre anyway, it would raise enough money to cover the salaries of all Louisiana public school teachers for more than a year. Eli Tan and Maureen Farrell, also of the Times, noted one resident’s sixfold rent increase thanks to housing demand from construction crews, but quotes the state’s governor saying the tax revenue pre-Meta was “zero”.
Zuckerberg:
We help keep electricity prices low by building our own energy-generating infrastructure wherever we invest. This ensures that not only are we not consuming energy that could have gone to the local communities, but in some cases we even supply a surplus of low-cost energy back to the communities. We think this is an important investment principle for sustainability.
Meta has previouslyemphasized its sustainability bonafides, but Zuckerberg omits such discussion here, perhaps because it would require considerable caveats that could be a distraction from the essay’s marketing angle. In Louisiana, for example, Meta is paying $2.65 billion to build several power plants with Entergy, but the region still needs more power. So Entergy is looking to acquire a plant in Texas, which could increase customers’ rates. In El Paso, at a different data centre project, Meta is only contracted to cover power plant construction costs for one to five years, after which costs will be transferred to customers. Like in Louisiana, it is also gas-fired.
Closer to home, a gas-fired plant in Alberta will not come online until years after Meta’s to-be-built data centre is up and running, all while electricity rates are predicted to climb.
Zuckerberg:
Developing personal agents requires a new way of thinking about alignment. Most labs today view alignment as a defensive measure for enforcing a centralized set of values. For example, one leading model was aligned to refuse helping draft a letter to prospective parents at a school because it thought standardized testing was unethical.
If this is a real anecdote, I cannot find the source.
And, if you can believe it, those are all the specific and checkable claims Zuckerberg makes in this essay. The rest of it is strikingly like one of those Microsoft concept videos from a decade ago albeit without the After Effects artist expense. One last thing, though, from Zuckerberg:
Privacy is an important foundation for individual empowerment and freedom. […]
Meta continues to make virtually all of its income from advertising targeted by some of the most privacy hostile technologies ever created. While “superintelligence” appears over fifty times in this essay, the words “ads”, “advertising”, and “advertisement” go unmentioned. They appear not even once.
The fixer — Ellis called him Ray and won’t reveal his name — met him in North London near Hampstead Heath for coffee and cakes. When it came time to discuss business, to avoid being overheard, they strolled into the park.
Ray had brought Ellis a few jobs before. But this job, he warned, was of an entirely different order. As Ellis claims in “The Art of Robbery,” a self-published memoir written after his release from prison, he eventually learned that Ray had been contacted by a consultant employed by “some influential bankers from America.” The bankers “were involved in prime mortgages” and had “circumnavigated” certain regulations. Damning evidence of these circumnavigations could be found in banking files held in the King’s Cross area in a giant building known as a data center.
This is a dramatic story, and one I think should be read with a heavy dose of skepticism. It seems that most of the criminal details have been shared by Ellis. For a start, the claim that some bankers ostensibly contracted with “Ray” is just a little too perfect for a recession-era tale. These bankers are pretty much universally loathed, and this justification makes this theft seem more palatable than a simple financial motive. For example, there was a similar data centre theft in October 2006, which would be unrelated to the lending crisis in the following years.
Another problem is that Rich says crimes like these are covered-up in part by a data centre operator because they are loathe to “admit to flaws in its security, [which] would only encourage additional attacks and scare away its clients”. Therefore, the lack of evidence for the specific circumstances of this crime is supposed to be a buttress for its likelihood, not a weakness, which is not reassuring.
The story of the theft was, as far as I can tell, broken by Here is the City, then a gossipy financial news site:
The data center itself is thought to be used by a number of companies, including JPMorgan, which is believed to have told staff that some of its systems could be off-line for parts of the day today as a result of the theft. Fortunately the thieves are thought to have got away with just the computer hardware, and not any sensitive information which may also have been stored at the facility.
Reports circulating on the Internet last week that JPMorgan, a customer of Verizon Business, had been affected by the burglary were incorrect, according to a source at the investment bank. There has been no loss of service or data, said the source.
On the one hand, of course all these parties tried to cover this up. The reading-between-the-lines story implied by these early reports and Rich’s telling is that some banking higher-ups, perhaps from JPMorgan, wanted to cover up some crimes, and denying any meaningful effect is just more cover-up. But little of this is substantiated by contemporary or current reporting — which is, of course, the whole problem with using a lack of evidence as the foundation for a story.
Rich, in the Times:
“The banks knew they were sending mortgages to people who couldn’t pay back,” he says today. “That’s what broke the whole system. That was the big con.” Ellis remains convinced that the bankers who paid for the Verizon job wanted to destroy evidence of their involvement in fraudulent subprime mortgages — the inside information that Ellis received about the data center, he believes, “would have had to come from the top” — but he can’t prove it. He never saw what was on the servers.
“Our job was to get the motherboards,” he says. “We were paid quite handsomely. Whatever happened after that was none of our concern.”
In contemporaneousreports, the Metropolitan Police noted the theft of motherboards and processors. But if these bankers wanted to cover up their fraudulent practices, surely the hard drives would have been the target, right? In Rich’s version, entire servers were taken, so perhaps this is just a misunderstanding.
This story smells fishy. I believe the theft happened, of course, and Ellis’ involvement, but I am not as convinced this had anything to do with covering up some white collar crime. (By the way, the Guardian in 2018 published an interview with Ellis about the interesting prison where he was transferred and which led to his rehabilitation.)
The heist element is only about half of Rich’s story; much of it is a discussion about data centre secrecy:
The public fogginess about data centers is not an accident. It is the product of a willful strategy by the world’s largest tech corporations, whose business models rest on the public assumption that the internet, and all the data it holds, is as immaterial as air — or as a cloud, to borrow the metaphor commonly used to describe the sum of information stored on servers. As the digital-media scholar Tung-Hui Hu writes in “A Prehistory of the Cloud,” the cloud “hides its physical location by design.”
[…]
It was a lot easier to defend data when people didn’t know it existed. The more people learn about data centers, the more they hate them. […]
If you read a website like this one, you were probably aware that data centres were commonplace twenty or more years ago. Like the one near King’s Cross, some were hidden in plain sight, while others were purpose-built facilities that look like hangars stuffed with servers. But the A.I. boom has meant rapid increases in the speed, scale, and quantity of data centres. People quickly learned not only of their existence, but how much pressure they put on local resources. Tech companies, it seemed, were caught by surprise; and as someone who spends a lot of time immersed in this world, so was I.
Much of the consternation I have seen in more general audiences has been about data centres in general. People simply were not aware that Amazon has warehouses full of products, and other warehouses full of computers. As Rich writes, this is deliberate, for business secrecy reasons, security, and environmental costs. But, also, I think some of that unawareness is because of just how boring it is. If nobody wants to know hidden information, is it really a secret? It only became one when the information these companies were hiding had real-life effects.
It does seem that public awareness is putting pressure on corporations to improve data centres and make them more efficient. But that is not a standard. New data centres are powered by petroleum with a pinky promise of renewable offsets. In some regressive regions, like Alberta, new power plants for data centres must be powered by methane gas. In a further complication, Meta’s proposed data centre is scheduled to be completed before the power plant is ready, meaning it will be dependent on existing grid power for perhaps years. Meta’s is just one of the data centres proposed for Alberta. Another one, a gigawatt cluster, would also require a dedicated gas-fired power plant, while Kevin O’Leary’s questionable project is supposed to require over three times the combined power of those other two.
For years, the tech industry told us we did not need to have much concern for how digital products and services worked, and many of us did not bother to find out. But it turns out the demands of our email and Netflix subscription were comparatively easy to hide. At the very least, what we ought to demand from projects with the scale and ambition of these data centres is open disclosure of their power consumption, water use, and emissions.
But we ought to demand more than the bare minimum. Transparency does as much good as a big banner reading we are destroying the planet but we are also creating a lot of value for shareholders. When a single data centre is projected to use about as much power as the entire city of Calgary is currently — Enmax says 1,260 megawatts as of writing — we should have a say in whether that makes sense. A.I. remains a thing that is happening to us rather than with or for us. It is built on assuming consent and asking forgiveness, which has more-or-less worked for the industry and gave it way too much confidence. Tech companies could have spent decades being better corporate citizens. Data centres are just one part, but they are representative of the difference between the stories told by tech companies and the things we can actually know.
I have previously noted I am not a fan of Ed Zitron’s writing on A.I., which I think is driven more often by adherence to narrative than by genuine skepticism. Even so, his newsletter is extremely popular, and occasionally that pays off with honest-to-goodness scoops. Yesterday, he got a big one — a smattering of OpenAI financial documents revealing the company’s spending and earnings for the past two years. In 2024, it made billions of dollars less than it spent — including over a billion dollars on sales and marketing alone — and its 2025 numbers look even worse:
The financial condition of OpenAI is deeply concerning. $38.53 billion in losses are astronomical, and far higher than most believed it would be. Losses also appear to be mounting year-over-year at a dramatic rate, and I’m not sure how this company finds a way toward any kind of sustainability or profitability.
Zitron shared these documents with the Financial Times, which independently verified them, and added some much-needed context. In particular, that whopping $38.5 billion loss accrued in 2025 and highlighted by Zitron — including in his headline — seems far less dramatic:
Before OpenAI’s switch late last year to become a public benefit corporation, investors in the company received convertible interest rights rather than conventional equity. Under US accounting rules, those interests were treated as liabilities and periodically revalued as the company’s valuation increased.
As OpenAI’s worth rose, the increased value of those investor rights created a roughly $30bn charge, added the person. The charge is not expected to recur following the restructuring, they said.
That expense is not something that can be waved away, of course, but it does not seem to be materially related to the company’s actual costs of creating and selling its products. Losses without including that charge were, according to the Times’ “person familiar with the matter”, $8 billion, or roughly 60% more than in 2024. But that is against revenue of $13 billion in 2025, a significant increase over 2024’s $3.7 billion. (OpenAI, in the first three months of 2026, earned $5.7 billion.)
These juicy numbers were republished by outlets like Reuters, the Next Web, Stocktwits, Benzinga, and Startup Fortune. Shamefully, all attributed them solely to the Times without mentioning Zitron’s critical role. These publications — particularly Reuters — should be giving full credit to the original source.
That Zitron now has actual, verified numbers also allows us to check some of his own reporting. For example, in April, he was quite upset that “every outlet has continued to repeat that OpenAI ‘made $13 billion in 2025,’ despite that being very unlikely given that it would have required it to have made $8 billion in a single quarter”. It is unclear to me which outlets Zitron is referring to as I could find just one — Russia Today — using that quoted phrase verbatim.
Even so, Zitron goes on to write about some apparently conflicting numbers reported by Anthropic before concluding:
Though I cannot say for certain, both of these situations suggest that Anthropic and OpenAI are misleading their investors, the media and the general public. If I were a reporter who had written about Anthropic or OpenAI’s revenues previously, I would be concerned that I had published something that wasn’t true, and even if I was certain that I was correct, I would have to consider the existence of information that ran counter to my own. I would be concerned that Anthropic or OpenAI had lied to me, or that they were lying to someone else, and work diligently to try and find out what happened. I would, at the very least, publish that there was conflicting information.
Two days after this article, he again claimed that “every single story about OpenAI’s revenue other than my own reporting (which came directly from Azure) massively overinflates its sales”, which are more like “a mere $2.27 billion in the first half of last year”.
The numbers Zitron now has for OpenAI suggests this narrative is complete hogwash. Yes, these companies leak overly-optimistic annualized run rates, but if that was a factor in the audited financials Zitron obtained, he likely would have mentioned that. He does not — and neither does the Times, for that matter. “Due to the seriousness of this story”, Zitron wrote, “I am not going to do very much editorializing”, so we will see in a later issue of this newsletter whether he acknowledges this self-induced frenzy was all in his head.
This is why I read Zitron’s work in the framework of conspiracy thinking. He accused OpenAI of “massively overinflat[ing] its sales” and “misleading their investors” based on his own calculations using leaked Azure figures. But it turns out OpenAI did, apparently, have that $13 billion in real non-ARR-fudged revenue for last year, and its operating loss is shrinking. Real analysts, not me, can figure out whether this company is on a path to a functional business. Zitron conjured a whole fictional narrative out of misreading some numbers and then, it would seem with this latest update, misunderstanding them again because it is useful for the story. Still, he should be credited for this scoop.
In March 2018, I compared the original 2010 demo of Siri against the then-current shipping version. That was eight years ago — closer, in fact, to the launch of the iPhone 4S and Apple’s version of Siri than to today.
Not much changed after I did that little experiment until Monday, when Apple announced a “profoundly more capable” Siri. Called Siri A.I., it will officially launch in beta with this year’s operating system upgrades. But I recently got access to the first preview of it in the first developer build of iOS 27 and, naturally, I had to try the same set of queries.
“I’d like a romantic place for Italian food near my office”: Apple’s previous Siri implementation always — for me, at least — got tripped up by the “near my office” part. New Siri did this flawlessly.
“I’d like a table for two at Il Fornaio in San Jose tomorrow night at 7:30”: Outside attempting this demo in 2018 and again today, I have never tried to book a restaurant reservation using Siri, so my sample size is pretty small. Last time I did this, I once managed to get Siri to prompt me to make a reservation through OpenTable, but was otherwise greeted by an error.
New Siri did one of two things: on some attempts, it told me it could not book a table for me, but suggested I could add it to my calendar or call the restaurant to complete the reservation. On others, it added the event to my calendar and asked if I wanted Siri to call the restaurant to complete the reservation. It is interesting to me that Siri A.I. does not (yet?) throw to OpenTable, and only suggests I make an old-fashioned phone call.
“Where can I see Avatar in 3D IMAX?” I swapped “Avatar” for a current 3D IMAX movie, and Siri A.I. showed me one theatre locally that is showing it in 3D but not IMAX, and one that is only showing it in 2D IMAX. This is, I think, mostly fine. I think Siri should clarify that no theatre nearby is showing it in 3D IMAX, but I think this is preferable to showing me the nearest theatre matching the query literally. As with the restaurant example above, there is no way for me to buy tickets through Siri.
“What’s happening this weekend around here?”: In the original Siri demo, this only showed nearby public events for the weekend. Apple’s version, in 2018, thought I was asking about the news and then, after rephrasing twice, threw to a web search.
Siri A.I. interprets this differently than either. It showed me my calendar and the events I already have this weekend, and then found an event in a marketing email in my inbox “if you’re looking for something else to do”. There were no details presented beyond “a ticketed show” and no obvious followup, but after a followup question — “what is that event?” — it showed me more information and a button to open the message.
In the original Siri demo, they ask a followup question “how about San Francisco?”, so I did the same, and it showed me events happening there this weekend. Just what you would expect.
“Take me drunk I’m home”: Siri got me driving directions to my house.
Though this is a test conducted on the very first version of Siri A.I. from a fixed point in Calgary, it seems to work quite well. So far, it is better than any version of Siri Apple has released yet and, as you can see above, it is almost as good as the original 2010 demo, before Apple acquired the company.
You probably know the gist. Predictions and dire warnings of a future lived in an immersive virtual world had been around for decades before Neal Stephenson solidified the concept in his 1992 novel “Snow Crash”, but Stephenson called it the “metaverse”, and that was important. It was a cautionary tale. Not everyone understood that. The video game Second Life, launched in 2003, provided an early glimpse of the concept in a P.C. environment. Another piece of the puzzle, consumer-grade virtual reality, began to take shape when Oculus was founded in 2012, and shipped a developer-centric version of its virtual reality headset in 2013. The company was acquired by Facebook a year later. Oculus released a few more headsets while Facebook figured out what to do to “truly transform the way we live, work and connect with each other”.
Despite this goal, “metaverse” was not yet part of Facebook’s lingo, though it was in Oculus’vocabulary. A 2015 internal memo from Mark Zuckerberg does not once contain the word despite describing the strategy it was developing. Even “Oculus” was barely mentioned in the company’s quarterly earnings calls around this time. But in the Q1 2018 call (PDF), Zuckerberg laid out a “10-year journey” for why Facebook bought Oculus, saying “every 10 to 15 years or so, there’s a major new computing paradigm”, and it is “very likely that the next one is going to be around virtual and augmented reality”. “One of my great regrets in how we’ve run the company so far is I feel like we didn’t get to shape the way that mobile platforms developed,” Zuckerberg said, explaining that it was important to spend vast sums of money now “in order to build some of the muscles to be competitive” later. Facebook was training for a major battle that would never materialize.
In the weeks after Meta announced it was retreating from its metaverse efforts earlier this year, I revisited this and other earnings calls, plus presentations and other documentation, as I tried to better understand what the metaverse was pitched as compared to what it ultimately became. I wanted to know how something so silly was treated by executive and media figures alike as a sincere directional shift for one of the world’s biggest companies in particular. In hindsight, it feels like a particularly narrow period of hype coinciding with — and, I think, benefitting from — the most urgent years of the COVID-19 pandemic. As enthusiasm deflated, it was almost unnoticeable despite forecasters labelling it an essential next step of the internet — a necessary next frontier.
The obsession with the metaverse seems to have solidified in Silicon Valley after Matthew Ball published an essay in January 2020 in which he forecasted that, at the very least…
…it is likely to produce trillions in value as a new computing platform or content medium. But in its full vision, the Metaverse becomes the gateway to most digital experiences, a key component of all physical ones, and the next great labor platform.
Ball admits “we don’t really know how to describe the Metaverse”, but sets seven criteria that, in general, portray it as an expansion and continuation of our blended physical and digital worlds, without the constraints of a physical space and with its own economy. Most notably, he says it will offer “unprecedented interoperability” between platforms and providers. He also lists eight things it is not, among them: it is not just a virtual world, or virtual reality, or a digital economy, or a new app store, or a new platform. It is more about a set of protocols and ideas that, yes, incorporate all these elements, but the metaverse is not itself these qualities.
Ball published this essay with darkly fortuitous timing. A week earlier, Chinese health authorities had isolated a new strain of coronavirus aggressively spreading in Wuhan; a day before, they published its genetic sequence. Within a couple of months, the world had turned upside down and many of us were suddenly spending our days in a space that felt more virtual than physical. We may have only been working from home — or, at least, those of us who had the option and were not laid off — and socializing over Zoom, all while remembering the last concert we went to or the last time we ate a meal in a restaurant.
In July 2020, Forbes contributor and futurist Cathy Hackl imagined a world — one that was “for certain, it’s coming and it’s a big deal” — that connects augmented reality, neural interfaces, and a whole bunch of assumptions. In this environment, you could merely remember that you need to buy something, and then a virtual vending machine would materialize so you could order that thing. Hackl defines the metaverse as “a future iteration of the internet, made up of persistent, shared, 3D virtual spaces linked into a perceived virtual universe”.
In “The Future is a Dead Mall”, a video essay using Decentraland as a jumping-off point for a discussion of the metaverse, Dan Olson navigates several writers’ conflicting definitions before making the reasonable conclusion it is basically irrelevant:
If you comb through dozens and dozens of definitions of the metaverse you can assemble a web of broad attributes where some are generally agreed upon, while others border on being mutually exclusive. It’s a vague, largely incoherent cloud of ideas that’s malleable enough that basically anything can be called part of the metaverse, a proto-metaverse, or a semi-metaverse.
[…]
When you understand that the metaverse isn’t a distinct invention or construct, but merely a rhetorical proxy for The Future of Technology, then all of this becomes a lot easier to deal with.
I think Olson is largely correct; this is how the term is actually used. But, though not his intent, I think defining “metaverse” in vague terms is favourable to its boosters because it does not hold them to something specific. I think the explanation offered by Mark Zuckerberg in Facebook’s Q2 2021 earnings call (PDF) is actually pretty fair. This was two quarters before the company changed its name, and between prepared remarks and the question period, there were twenty total mentions of “metaverse” on this call.
So what is the metaverse? It’s a virtual environment where you can be present with people in digital spaces. You can kind of think about this as an embodied internet that you’re inside of rather than just looking at. We believe that this is going to be the successor to the mobile internet.
You’re going to be able to access the metaverse from all different devices in different levels of fidelity — from apps on phones and PCs to immersive virtual and augmented reality devices. Within the metaverse, you’re going to be able to hang out, play games with friends, work, create, and more. You’re basically going to be able to do everything that you can on the internet today as well as some things that don’t make sense on the internet today, like dancing.
So, in some ways, exactly like Olson’s definition: “different devices in different levels of fidelity” that let you socialize and do work, just like everything you currently do on the internet — plus dancing. It seems almost halfway toward being normalized in his head, though it feels as alien to read this today as it surely did then. Yet Zuckerberg is getting at something here. Virtual and augmented reality are ways of immersing us in unique environments that radically change how we interact with technology. And on the next quarter’s earnings call (PDF), Zuckerberg expanded:
[…] If you’re in the metaverse every day, then you’ll need digital clothes, digital tools, and different experiences. Our goal is to help the metaverse reach a billion people and hundreds of billions of dollars of digital commerce this decade. Strategically, helping to shape the next platform should also reduce our dependence on delivering our services through
competitors.
Your avatar cannot simply be a picture of you. You will “need digital clothes” for this space. Need.
In addition to building hype among investors during these earnings calls, Facebook was pumping up its metaverse efforts in more general audience settings. In May 2021, CNetpublished a transcript of a thirty-minute Zoom call between Zuckerberg and Scott Stein where the former could wax lyrical about the bonafides of where Meta was at the time — “with the fidelity of experiences that are possible today, to me that just says, wow, in five years this is going to be clearly better on almost all of these fronts for a lot of the things that we do”. Casey Newton, of the Verge, was given by Facebook a copy of an internal meeting in which Zuckerberg told employees the company’s “overarching goal across all of these initiatives is to help bring the metaverse to life”. The two then recorded a soft and cuddly episode of the Vergecast that allows Zuckerberg to play visionary and rattle off the company’s metaverse talking points. “I think over the next five years or so, in this next chapter of our company,” Zuckerberg told Newton, “I think we will effectively transition from people seeing us as primarily being a social media company to being a metaverse company.” By October, Sarah E. Needleman was relaying to readers of the Wall Street Journal the words of Unity Software’s Marc Whitten the imperative for businesses to develop a “metaverse strategy”. “The metaverse is going to be the biggest revolution in computing platforms the world has seen,” said Whitten, “bigger than the mobile revolution, bigger than the web revolution”.
It is not difficult to see the deliberate strategy here. In 2019 and 2020, Facebook was not talking about the metaverse and, though a few commentators connected the just-announced Horizon social world to the concept, it was not treated yet as the inevitable future. As 2021 rolled on, Facebook’s promotional drumbeat grew stronger. Suddenly people were talking about the metaverse, and connecting it all back to Facebook. There was, it would appear, real buzz — enough, at least, for the Journal to find corroborating voices and take it seriously.
Three days after its Q3 2021 earnings call, Facebook held its Connect conference, which is centred around its augmented and virtual reality efforts. This was a big moment. This would be the keynote where the company laid out its metaverse-centric vision, and changed its name to Meta to reflect this new focus, and because it had to. “From now on,” Zuckerberg said, “we’re going to be metaverse-first, not Facebook-first”.
Rewatching this presentation in 2026 is a bizarre experience, not least of which because of how it is shot. Most scenes appear to be green screened with composited animations. Demos are virtually nonexistent, with most representations of the metaverse carrying a disclaimer that they are “not actual product images” and they are “strictly for illustrative purposes only”. Even so, Zuckerberg and other executives at Meta are all-in on hyping up an experience that, at best, only barely resembles what it ended up shipping. In many cases, it is not even close.
There is a Jon Batiste concert visualized as something that could be attended in-person by someone in Los Angeles and in the metaverse by someone in Kyoto, presumably through the glasses each person is wearing. We do not see the performance from their perspective, but the implication is that the virtual viewer would see it from the same or similar perspective to the in-person attendee. Both get invited to a virtual after-party where they can buy NFT-based digital merch and meet Batiste or, at the very least, his avatar. The reality of metaverse concerts is quite different than this concept. In 2024, Meta showed a Sabrina Carpenter performance in Horizon Worlds. The seats were great, but even in this immersive environment, it appears more like a concert film than a unbroken show viewed from a single perspective. Also, I cannot find any record of an after-party or virtual merch.
Zuckerberg touts Horizon Worlds as the place users will go to socialize, and Horizon Workrooms as the virtual environment for their job. The latter has since been completely shut down, while the former was put on ice. In gaming, Zuckerberg was particularly excited about Rockstar’s port of “Grand Theft Auto: San Andreas” which, three years later, Rockstar cancelled before it had been released. He said “remote work is here to stay for a lot of people” in this keynote, less than two years before ordering in-office work three days per week; two years after that, Instagram demanded five days per week in-office. I guess “a lot of people” does not include the people who are building the products that let a lot of other people work remotely. That is a little weird.
The wishcast-a-thon of Connect 2021 was treated by some with an entirely unearned gravitas. Dean Takahashi, of VentureBeat, called it a “historic moment” and compared it to the Manhattan Project. He thought Meta could bring about universal basic income, with Zuckerberg “paying us to use his devices so that we can make a living in his ecosystem”. In a mostly skeptical article in the New York Times, Kevin Roose raised the possibility that Meta’s focus change “could help with the company’s demographic crisis”, and advocated taking it seriously because the company “has found what may be an escape hatch” from “Facebook’s messy, troubled present”.
To mark the occasion, Zuckerberg granted interviews to four publications, all embargoed until after the Connect 2021 video was published. Dylan Byers, for Puck, was left with the understanding that Zuckerberg “doesn’t really care” about press coverage or questions about the legitimacy of this pivot — in a good way. “[I]t’s just that he’s not so bothered by the unrelenting criticism, and near-term and collateral damage,” wrote Byers, “that he’s going to check his ambitions or think twice about whether or not he’s the right person to help usher in the next phase of the internet”. Alex Heath, of the Verge, implicitly acknowledges the role Facebook’s public relations team played in creating the impression of interest in the metaverse, writing “it wasn’t thrust into the mainstream conversation until Zuckerberg started talking about it publicly earlier this year”. Heath did not break any news of note; neither did Matthew Olson, of the Information. The latter did at least contradict Zuckerberg’s protest of the “relatively high fees”, “a nod to the 30% commission” of Apple’s App Store and Google’s Play Store, by stating that while “Zuckerberg didn’t indicate what commission Facebook would charge”, “Oculus’ Quest
Store currently takes 30%”.
The following day, Matthew Ball spoke with Zuckerberg in a live audio session that has since been pulled from Zuckerberg’s Facebook page, though clips remain available on YouTube. A transcript of the conversation reads like a context-free time capsule of that era, with praise for meme stocks, NFTs, and Web3 in concept more than in practice — and, of course, Ball’s writing on the metaverse. (Six months after this interview, the NFT market would well and truly collapse, with peak transactions occurring the month before Ball and Zuckerberg spoke.) Ball raises the subject of the company’s $10 billion annual spending on Reality Labs. Zuckerberg believes “the metaverse can reach a billion people, say, in the next decade, and that there can be supported hundreds of billions of dollars of commerce. And that if that’s the case, then even with relatively modest fees on the transactions that happen in our services, we think that could be a big business”. But Zuckerberg says he does not want to lose too much money, which is being treated as a “somewhat moderating force over the next period that will keep us from being able to make all of the fees maybe as low as we would want to”. The strategy is, to be clear, entirely dependent on a massive groundswell of public interest in a fundamentally new understanding of computing.
(Zuckerberg also takes time in this conversation to note his respect for intellectual property, at least for luxury brands: if “someone can just make a knock-off Gucci sweater, then I don’t think Gucci’s going to feel that good about being in that space, right, or participating in that system”. Just a few years later, Zuckerberg would allegedly approve the use of pirated ebooks for training the company’s artificial intelligence systems. The work of authors, it would seem, is not as concerning as the reaction of luxury brands.)
A few days later, Zuckerberg again eschewed traditional media outlets and sat down for an interview with Sara Dietschy; then, he chose a softer approach in spirit, if not in volume or cadence with professional talking guy Gary Vaynerchuk. Earlier that year, Vaynerchuk had launched his own NFT collection and, not long before speaking with Zuckerberg, had sold five of his paper doodles for $1.2 million at a completely real Christie’s auction, so you could say they are both on the same wavelength:
Vaynerchuk: The extremity of the NFT space is going to be even greater for what that means. It’s almost like our
world is all about to become the fashion industry because we communicate so much through what we wear. The digital version of that is going to have an incredible impact on society.
Zuckerberg: Oh, totally.
Totally. Just like the fashion industry.
In 2022, Meta added support for NFTs in Facebook and Instagram, a project which it discontinued less than a year later. Digital collectibles got a shoutout in the Connect 2021 presentation, had a brief moment in the sun, and were quickly forgotten about. These things are supposed to be building blocks of the metaverse and Meta barely tried.
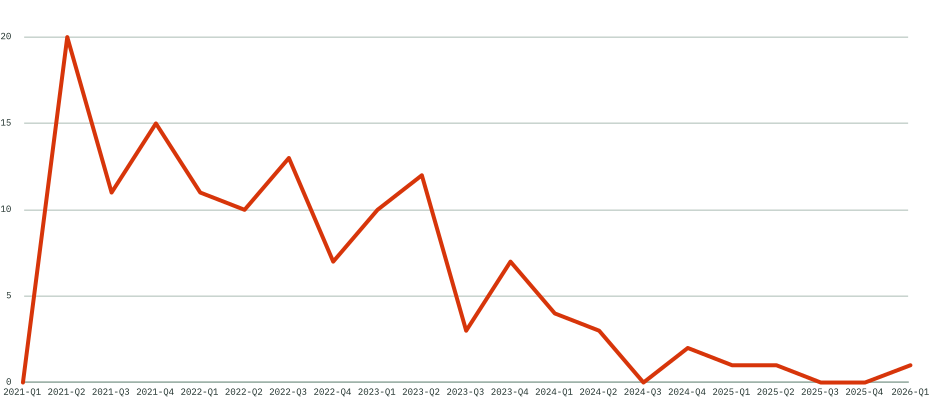
Meta’s annual commitment that Ball referenced, of $10 billion, represents all Reality Labs spending, including game development, some A.I. investments, and its EssilorLuxottica collaboration. Even so, despite a complete change in corporate priorities explicitly in the direction of the metaverse, Meta’s long-term interest did not match its investment. Here is a chart I made of mentions of “metaverse” in the transcripts of quarterly earnings calls from Q1 2021 — the quarter before its public relations push — through Q1 2026:
Mentions of “metaverse” in Facebook/Meta quarterly earnings calls. Source: company transcripts.
The highest point on that chart is the Q2 2021 earnings call I used earlier for the definition of “metaverse”; the second-highest is Q4 2021, the first earnings call after Connect 2021. The total count includes mentions in Meta’s prepared remarks, plus the question-and-answer period that follows. Investor conference calls are not a perfect proxy for a company’s priorities, but they are indicative. At the very least, for a company that entirely changed course with a new goal — “from now on, we’re going to be metaverse-first” — and a directly relevant name, one might imagine the company and analysts will be similarly eager to discuss how that is going. But no. In Q4 2022, mentions are half that of the year prior. By Q1 2024, neither Meta nor the analysts on the call seem to care all that much — while there were just four mentions of “metaverse”, there were ninety of “A.I.”.
This speaks volumes. It is the kind of thing that makes you wonder if this company was ever serious about this metaverse pivot at all. It seems like it had every intention, sure, but could it ever have executed on its vision? Of the four interviewers chosen for pieces related to Connect 2021, only Ben Thompson even thought to question its feasibility. (Thompson was also the only one to say he was permitted to view a copy of the presentation in advance. I do not know if this means the other three interviewers did not see it and, therefore, could not interrogate it more thoroughly, or if they did see it and simply did not bother to ask.) At the time, Facebook had no track record in building an operating system, barely had any credibility in hardware, and it only kind of created a platform on its “blue site”. (It arguably avoided creating platforms for developers with Instagram and WhatsApp.) This same company was claiming it was launching the successor to the smartphone and the next iteration of the internet. Every one of these chosen interviewers should have been all over this, but they were too distracted by the rebrand and Facebook’s sordid history to notice it was only a concept video more than it was any kind of real concept.
2. The Others
While Meta made itself the face and name of the metaverse, it was far from alone in promising the immersive computing platform of the near-future. Time basically acknowledged this by declaring one of the best inventions of 2021 was the Qualcomm Snapdragon XR2 — a foundational headset chip, rather than Meta’s attempt to build the platform.
In April 2020, Washington Post reporter Gene Park proclaimed the “next version of the Internet is often described as the Metaverse”, going on to confidently explain how it would be built. Of all the companies involved, Park wrote, “it’s Epic Games, with Fortnite, that has the most viable path forward in terms of creating the metaverse”, citing Ball’s seminal metaverse essay.
In April 2021, months before Facebook began asserting its commitment, Epic Games announced it had raised a billion dollars to “support [its] long-term vision for the metaverse” with $200 million of that coming from Sony. A year later, Epic raised another $2 billion, a billion of which again came from Sony, and the other billion from Lego. In 2023, a Lego game was added to Fortnite, which is not really the metaverse as much as it is a nifty Minecraft-like game-within-a-game.
Yet in Epic Games’ telling, it is basically delivering the metaverse already. CEO Tim Sweeney spoke at the 2023 Game Developers Conference about the company’s vision. Since there are around 600 million monthly active users of games, like Fortnite and Minecraft, set in virtual worlds, Sweeney reckoned “we can set aside the crazy hype cycle around NFTs and VR goggles. Yes, these technologies may play a role in the future, but they are not required. This revolution is happening right now.” Sweeney spoke of interconnectedness and open standards that would allow users to move between different spaces in a unified way. “What a user would really like is to be able to buy a cool-looking outfit in one place and take it everywhere they go” Sweeney claimed. (Why do they always mention digital clothes? My theory is because they do not view fashion as having much value beyond a basic assessment that how someone dresses is an expression of identity.) Sweeney describes Fortnite, Unreal Engine, and the Epic Games Store as “on-ramps to the metaverse”, and that the users of which already understand their in-game socialization can be extended to “going to a concert and dancing” in a virtual environment. Leaving aside the contradiction with definitions of the metaverse that mandate a more immersive environment, it is a big leap to think a brief animation of Eminem scratches the same itch as an actual performance.
Microsoft, as ever ahead of a trend without fully conceptualizing it, said it was doing metaverse stuff before Facebook started referencing it in public. Satya Nadella, defining the metaverse as “made up of digital twins, simulated environments, and mixed reality”, claimed a mix of Azure features, HoloLens, and Mesh would allow enterprises to get aboard. Last year, Microsoft said it was getting out of V.R. hardware and turning its mixed reality collaboration product into a glorified Snapchat filter in Teams.
Then there is Roblox. When Andreessen Horowitz announced its investment in the company, Marc Andreessen and David George wrote that “[w]hile pundits have been distracted by the readiness debates and questions over V.R. vs. A.R., the foundations of a global metaverse have been quietly built in the background… in Roblox”. This was in February 2020 — before Epic Games, before Microsoft, and well before Meta said anything in public about the metaverse. In January 2021, as part of Wired’s predictions for the coming year, Roblox CEO David Baszucki confidently predicted “the metaverse will experience widespread use, and start to become a human co-experience utility”. In March, the company went public at a $30 billion valuation. After Facebook changed its name to Meta, Baszucki saw that as validation of its strategy. That November, he made the rounds on business television networks like Bloomberg and CNBC to advocate for the company as a trailblazer.
In January 2022, Bernhard Warner of Fortune was getting excited about the possibilities of the metaverse, writing it “might be the most important trend in tech since the iPhone”, perhaps “a tectonic shift in tech that they [big tech and big investors] can’t afford to miss”. The way Roblox was “monetizing the metaverse” was a key piece of evidence, with virtual concerts and — most importantly — brands. “A parade of consumer brands […] have set up a presence on Roblox in the past year”, wrote Warner, citing Nike’s approach as being particularly exciting. A month earlier, it had acquired a company called RTFKT, which its press release extolled was a “leading brand that leverages cutting edge innovation to deliver next generation collectibles”. Guggenheim Securities, a subsidiary of Guggenheim Partners which has over $350 billion in assets under management, said it was the “‘best idea’ of 2022”, according to Warner. People are going to need virtual outfits, right? Yet, just three years later, Nike shut down RTFKT.
Gucci, another of the brands with a virtual presence in Roblox, sold virtual handbags for in-game currency for a limited time in 2021 and 2022; users realized they could effectively counterfeit and resell them. At least one of Zuckerberg’s predictions kind of came true. And, while Warner highlighted Disney as another company with in-game presence, it has not maintained a meaningful investment because, according to Variety, it feels Roblox is unsafe for children, a sentiment that was not helped when Baszucki appeared on the “Hard Fork” podcast. Roblox has settled lawsuits with the attorneys general of Nevada, Alabama, and West Virginia over accusations its platform features enabled child exploitation by other users. Roblox has denied any wrongdoing though it says it is enabling better parental controls and tighter restrictions on children’s accounts.
Through 2021 and 2022, the metaverse hype cycle was apparent across the tech industry. Max A. Cheney, reporting for Barron’s in August 2021, noted “[m]entions of the metaverse in earnings transcripts and other corporate documents are up five times this year compared with 2020, according to data from Sentieo”. This relative figure must have a hilariously low baseline, sure, but it is an indicator of how many businesses became briefly enchanted by this concept. There were serious financial analyses of real estate in the metaverse. Keep in mind that what is meant by “real estate” is much, much, much closer to domain names than it is land and deed. In July 2022, Technavio, a market research company, forecasted this market would be worth $5.37 billion by 2026. This report was picked up by Debra Kamin, of the New York Times, who published an article in the paper’s real estate section in February 2023 explaining this “new frontier for real estate builders and investors”. The primary anecdote in Kamin’s story is a just-completed mansion in Florida with a “twin” in a metaverse platform called the Sandbox. “As these technologies get more immersive”, the homebuilder said, “it’s going to make a lot more sense” to have a 3D virtual model of a house. Kamin was not breaking news on this specific story, as it was first reported by Emma Reynolds, of Forbes, over a year earlier. One would think that Kamin could therefore have asked some more probing questions or surveyed the actual market for NFTs which, by 2023, had fallen off a cliff. But no. Instead, the builder got the imprimatur of the Times describing the combined physical and digital sale in flattering terms. Ultimately, neither the listing nor many of the sale notices mentioned the sole marketing quirk of this house, suggesting that by 2023 the novelty of a digital model of a mansion was kind of over. I was curious if the NFT was a factor in the buyer’s decision, but did not receive a response to requests for comment I sent to a phone number associated with the current owner of the property.
Both the Times and Forbes articles are individual disasters in their own right. Sure, we might not expect a pinacle of journalistic integrity from Forbes and, to a lesser extent, the unabridged property ads that form the real estate section in prestigious newspapers including the Times. But to communicate this nonsense with the framing of “real estate” is treating wild speculation with unearned seriousness. This project was also co-signed by Sotheby’s. The whole thing is an embarrassing validation of a market that, predictably, would prove to have no substance. This was obvious by the time the metaverse mansion was being peddled. Eric Ravenscraft, in Wired in December 2021, reported that the attempts at artificial scarcity “more closely resembles early-access video games and common pump-and-dump schemes” than a real estate market. Indeed, a Coingecko analysis found metaverse “land” was worth 34% less in 2024 compared to the year prior, and 72% less than at its peak in 2022. This was an average across several platforms, and the biggest decline was in the Sandbox, the digital home of that mansion’s 3D model twin. According to a CoinDesk report published last year, the Sandbox laid off half its employees and its token has dropped in value from its peak by 90%. As of March 2026, user rights to space in Sandbox and Decentraland — another metaverse platform — that had originally sold for hundreds-of-thousands to millions of dollars were not a market totalling $5.37 billion as forecasted by Technavio. They had become basically worthless.
3. Fever Dream
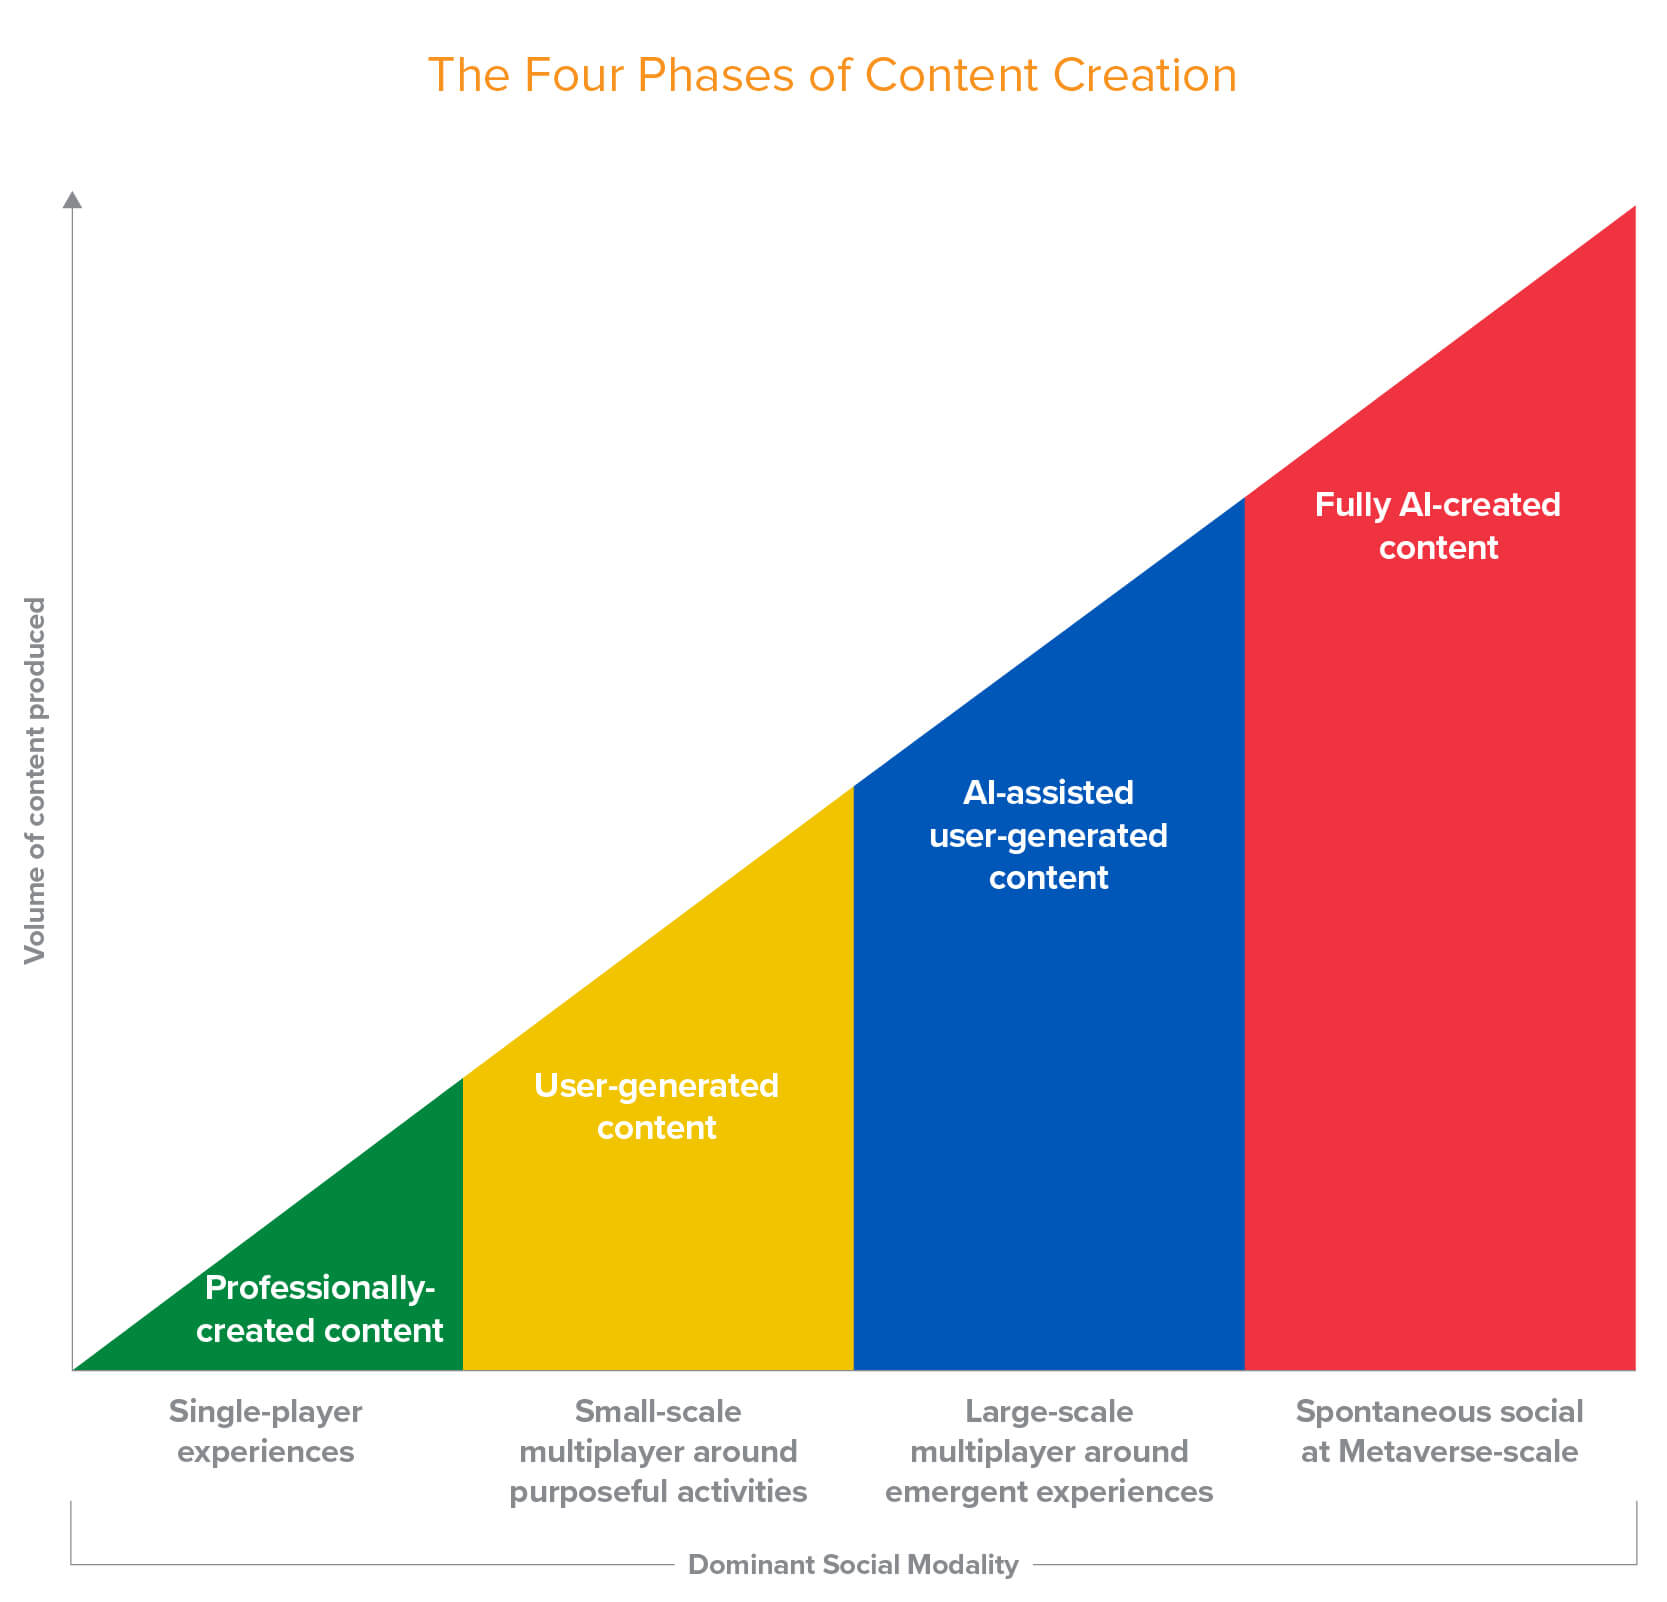
Officially, Meta is still all-in on the concept around which it pivoted the entire company in 2021. It still has a whole marketing page proclaiming its belief “in the future of connection in the metaverse”. You can go shop its lineup of Quest headsets which Meta says represent the best and most immersive metaverse experience, though its flagship model is now two-and-a-half years old. It has awkwardly promoted its Ray-Bans as “A.I. glasses” despite them becoming the company’s most successful line of mixed reality products, and it is desperately trying to connect its newest muse of A.I. with its last one. The single mention of “metaverse” on its Q1 2026 earnings call (PDF) is when Zuckerberg claimed to be “excited for more of our metaverse efforts to be powered by the A.I. models we’re training as well”. If you want to be unfairly generous in your interpretation of Zuckerberg’s brief remark, you could point to a December 2020 Andreessen Horowitz piece, in which general partner Jonathan Lai refers to this shape as a “pyramid”, and says that “fully A.I.-created content” is directly correlated with “spontaneous social at metaverse scale”. Obviously. I am not feeling generous.
Others in the space have not fared much better. Roblox has not mentioned the word “metaverse” in its quarterly or annual reports since Q1 2022 (PDF). Epic Games scarcely mentions it in recent news releases, either: since January last year, just one announcement contains the word “metaverse”, while seven are dedicated to the lawsuits Epic has been fighting against Apple and Google. Far from the inevitable next chapter of the internet, the metaverse, supposedly the future of how we live, work, and play online, is a non-event.
Near the end of the Connect 2021 presentation, Nick Clegg, then Meta’s global affairs chief, said “the metaverse isn’t something we’re building, so much as it’s something we’re building for”. Olson, in his video, wryly notes that, in the eyes of its promoters, “the metaverse cannot fail; you can only fail to make the metaverse”. The metaverse is so inevitable that “you might even already be in it”, according to Barron’s. But the metaverse is not predestined; it never has been. It is a construction of tech companies that saw in the pandemic their future — not ours.
A slightly charitable interpretation of what I think the pandemic demonstrated to Facebook executives, for example, was how invaluable technology companies were in maintaining connections even when most people could not do so in-person. They recognized how much time people were spending in front of screens already, even in years prior, and assumed that could be a more social experience.
But a more cynical view is no less fair. With the pandemic undoubtably came a realization of how much money Facebook stood to make, if only it had a platform. In 2019, there were two publicly traded companies worth over a trillion U.S. dollars; by the end of 2021, there were five, with Apple and Microsoft now worth over two trillion dollars each. This pandemic was not going to last forever — but it did not need to. Our world was permanently changed, or so it would have seemed, and we would surely want to virtually attend concerts and buy PNG files of band t-shirts with real money. And these companies would take their cut.
One thing I have mentioned but did not emphasize is just how often Zuckerberg and Sweeney mention Apple and Google platform fees as a primary justification for building the metaverse. Sweeney spent several years fighting lawsuits against both companies, mostly winning the one against Google and mostly losing the one against Apple. His efforts have, nevertheless, shined a spotlight on these grotesque practices. But it would be a mistake to assume this is an objection on ideological grounds. These guys just want to take those commissions for themselves. Sweeney spent his GDC 2023 presentation comparing the need for open standards in the metaverse to the openness of the web, but unlike the web, the Epic Games store takes a 12% commission. Meta beat that, though; it even beat Apple and Google. By the time the individual fees are added together, transactions made through Horizon Worlds could be levied a commission of up to 47.5%. The money thing is not even a secret; it was often the very first thing people like Zuckerberg and Sweeney discussed in interviews about their metaverse plans. This was a financial decision before it was a product or service people might actually want to use.
It would not be fair to characterize Meta’s endeavour as an impulsive flash in the pan. Zuckerberg laid out his vision in a 2015 internal memo in which he explained how the company “would like a stronger strategic position in the next
wave of computing”. Then, in January 2017, the Chan Zuckerberg Initiative acquired a company called Meta, I think mostly for the name; a year later, Zuckerberg floated the idea of a rebrand. The 2015 memo that effectively set this whole thing into motion gives the impression of a surprisingly cogent document if you set aside the wildly optimistic timelines — “VR/AR will be the next major computing platform after mobile in about 10 years” — and the idea that virtual and augmented reality are so compelling it will supersede the desire for phones and televisions. If anything, the unearned confidence in this memo should have been alarming at the time. As Zuckerberg himself writes, the “core social networking work is no longer new, Internet.org is extending something rather than inventing it, and A.I. is not yet tangible”. This is not a company known for doing new, and it is now stuck with a name reflecting a bungled attempt to change that. Staff are not happy after years of mass layoffs, court losses, role reassignments, and internal surveillance to feed the company’s A.I. projects. Do not get me wrong — Meta’s business of collecting vast amounts of information about its users and selling relevant ad slots is as strong as it has ever been. But Meta the ad company is not Meta the platform innovator.
And this feels like the why of it all. If tech companies can channel a meaningful sliver of our entire lived experience into a world of their creation, one where they collect a portion of revenue, it would make them inescapable. Ball, Sweeney, and Zuckerberg may have all written or spoken about the importance of interoperability and open standards, but these platforms want to exercise a degree of control more similar to native software than to the open web. The steps for migrating from Horizon Workrooms to a competitor’s product, for instance, are not what one would expect if openness were a priority.
For a brief couple of years, it seemed like there could be enough enthusiasm from reporters in the space, venture capitalists, and executives to make the metaverse happen. Then ChatGPT launched in November 2022, and the pandemic ended in the U.S. in May 2023, and any interest anyone may have had for spending more time with people in a virtual setting largely evaporated. It turns out we are okay with having meetings and playing games online, but we actually like seeing live music in-person and travelling to real places. The problems each of these things may have — high costs, environmental impact, and so on — are notable and real, but are not ones with metaverse-based solutions.
The pandemic did not make the metaverse. There was sufficient interest in developing it well before then, and it is possible all of these companies would have announced all these products and services on the same timeline. But in a world without a pandemic, I cannot imagine anyone would have treated these metaverse announcements with anything like the seriousness they did. The pandemic officially ended in the U.S. just six months after the first release of ChatGPT, so it is impossible to disentangle the influence of either. But it is notable to me that the nosedive in mentions of “metaverse” on Meta’s investor calls occurred in Q3 2023 — the quarter immediately following the declared end of the pandemic.
As for the futurists like Hackl, who confidently proclaimed the metaverse was “for certain”, they have found an out thanks to its flexible definition. Jeff Barrett, of the Shorty Awards’ “It’s No Fluke” podcast, published a glowing profile of “the Godmother of the Metaverse” earlier this year under the headline “Why Cathy Hackl Keeps Getting the Future Right”. “When enthusiasm cooled and narratives collapsed, many distanced themselves from the space”, writes Barrett, noting with seeming approval that “Hackl did the opposite. She reframed it”. Many people — perhaps everyone, come to think of it — could predict the future if they got to retcon their predictions to fit reality.
There are many open questions about the metaverse; most glaringly among them, whether it could actually become a thing for normal people. That depends a little bit on what definition we use. If it simply means the slow erosion of the boundary between our physical and digital environments, that is probably something that will continue to happen. For most people, though, that does not look like Meta’s Connect 2021 concept animations. Whatever that ends up being will probably be the result of people finding something useful and intriguing about doing something different. It will not be the product of big companies redirecting the money hose of platform fees onto themselves.
With thanks to Marquette University for granting me access to the Zuckerberg Files. A frustrating number of Zuckerberg’s post-Meta interviews are video-based, so the transcripts produced by this effort were invaluable. Where possible, I have checked these copies against the originals.
An advantage of publishing my problems with wide circulation is that sometimes people will be very helpful in their comments and emails.1 Plenty of people kindly suggested alternatives and ways to correct the problems I was having and, after many days’ work, I think I am on better footing.
But first, it is my fault as a writer that it seems I did not differentiate clearly enough the two related issues I have experienced with iCloud Photos. The first problem is that it is very easy to get images into an iCloud-stored photo library, but extremely difficult to extract them. This issue is compounded by a lack of transparency and data verification. The second problem is that it is necessary to commit to a lifetime of storage if one uses a third-party cloud option.
The software suggestions I received are manifold. The first is a category comprising a bunch of self-hosted options, of which the most popular seems to be Immich. This would solve the problem of a long-term commitment to a third-party provider, but it requires me to be a hobbyist data centre technician and I cannot handle more things on my to-do list. Yes, I have looked at the documentation and it seems straightforward enough. No, I still do not want to take this on. Perhaps one day, but not now.
I am, in fact, happy to pay someone to deal with that for me. Apple should be doing a better job of it than I ever could. Its data centres, whether first-party or third-party, surely have redundancies upon redundancies, and a level of data validation I simply cannot compete with. My dispute with this is not about third-party storage per se. Rather, it is how shoddy an experience it is to move photos out of iCloud and, also, my inability to verify that everything is as safe and secure as it should be.
But I was pointed to two pieces of software I can use that made my life easier and got me onto more stable footing. The first is Parachute Backup (MacOS 15 or later), which created a backup of my entire iCloud photo library and, soon, will also be backing up everything else I have in iCloud, for good measure. This is good software; I like it a lot. But I will provide a couple of caveats up-front if you are attempting a similar strategy.
Most obviously, it will download everything, which means you need a disk big enough to hold a discrete copy of everything you store in iCloud. That could be expensive right now. I bought a 2 TB external Samsung SSD a few years ago for $400, and it is currently nearly $800 on Amazon. But I do hoard old hard disks and I found a 2 TB one I could clear up.
You are also going to need patience. Not only will it take time to download, depending on your internet connection and the amount of stuff you have in iCloud, Parachute does not have any built-in bandwidth controls from what I could see. I am sure I could have found a way to limit it, but I just let it run. It took five days.
But now I am pretty sure I have a local copy of everything in iCloud. This is the feeling I should get from having “download originals to this Mac” switched on — which I have for several years — but that is apparently not a reliable preference. Also, this copy of my photo library is meaningfully organized in a date-based directory tree instead of some abstruse collection of randomized folders.
The other piece of software to which I owe my newfound sense of calm is PowerPhotos. Despite being hands-down the most frequent software recommendation from readers, it never came up in my earlier searches. I guess I was not using the correct keywords. In any case, it is an excellent application. Because I did the full Parachute backup, I felt comfortable with PowerPhotos modifying my library and generally doing its thing. It lets me easily drag photos from my primary iCloud-connected library to my archive, and its duplicate image finder is way better than the one in Photos.
What that means is that I can now confidently maintain that archive photos library. It is not worth the increase in iCloud storage costs for me to carry all of my tens of thousands of photos everywhere I go. For me, it is definitely worth the cost of these two software licenses to have more control.
(Also, an extra nice thing about PowerPhotos is that it has been around for ages, and old versions of the software remain available for download. The latest ones do not work on my iMac, but 2.x versions do, and a license key unlocks them all the same.)
I am receiving nothing by pointing you to either of these applications. I paid for both myself. However, I heard from the new owner of Parachute shortly after I published my article with a license for each of the Mac and iOS versions. I do not usually accept codes and I bought my own license anyhow, so I asked if I could give those codes away. I only have one of each to give out and they are only valid for another couple of days, so shoot me an email and let me know which one you want. (Update: Both licenses have been claimed.)
It also means some other people will be spectacularly unhelpful. Here is a free tip: if your immediate reaction to someone having a problem with a service they are using as marketed is to blame them, consider whether you are actually being a smug jerk. (Ten points to you if you figure out which comment, specifically, encouraged me to write this footnote.) ↥︎
Apple Inc. plans to open Siri to outside artificial intelligence assistants, a major move aimed at bolstering the iPhone as an AI platform.
The company is preparing to make the change as part of a Siri overhaul in its upcoming iOS 27 operating system update, according to people with knowledge of the matter. The assistant can already tap into ChatGPT through a partnership with OpenAI, but Apple will now allow competing services to do the same.
This is not unexpected. In the Apple Intelligence introduction at WWDC 2024, Craig Federighi said “we want you to be able to use these external models without having to jump between different tools”, and that they were “starting” with ChatGPT. Gurman points this out and also notes Federighi’s teased Google Gemini integration. Tim Cook, in an October 2025 earnings call, said much the same. (Gurman also notes that this integration is “separate from Apple’s work with Google to rebuild Siri using Gemini models”, but “the news initially weighed on shares of Google”, which I am sure is exactly the reason for them dropping 3.4% and nothing to do with an existing weeklong slide but, then again, I do not work at Bloomberg so who the hell am I to say?)
Gurman, in his “Power On” newsletter over the weekend, further explored what he calls Apple “doubl[ing] down” on a “revamped A.I. and Siri strategy”:
That reality is shaping the company’s new approach, set to be unveiled at the Worldwide Developers Conference on June 8. Rather than engaging in an AI arms race, Apple is focusing on its core strengths: selling highly profitable hardware and making money off the services that run on it.
Historically, Apple’s software — iMessage, Maps and Photos, for example — has been about driving product sales rather than generating revenue in their own right. Rivals, in contrast, are aggressively monetizing AI through subscriptions and premium apps. Apple understands that few, if any, users will pay for Siri or its other AI technology. The opportunity to turn Apple Intelligence into a moneymaker has effectively passed.
What would have been more newsworthy here is if Apple’s A.I. strategy were anything other than building software exclusively for its proprietary hardware. This does not sound like a “revamped” strategy; it sounds like Apple’s whole deal. If it can use Apple Intelligence or Siri in the future, it certainly might; it is putting ads in Apple Maps after all. Services is a money-printing machine with less risk. But it is still a hardware company.
This part made me double-take and wonder if I missed something. In February 2024, following Apple’s cancellation of its car project, Gurman predicted that hardware would continue to be Apple’s primary business “for now”, as though that will change in the near future. This has been constant since Apple Intelligence was announced at WWDC that year.
What one could argue has been a change of strategy is the rumoured development of a chatbot; Gurman called it a “strategic shift” when he broke the news. But that, too, is somewhat inaccurate in two ways: Gurman’s description of it is as an overhauled version of Siri that will let people do normal Siri stuff — setting timers, end of list — plus some of the features Apple announced in 2024 but has not yet shipped which, confusingly, were also first set to ship in an update to iOS 26 without the wholly new version of Siri but also depending on Gemini. Got it?
But even that is not much of a strategy shift. Gurman tweeted in May 2024 — before WWDC and the debut of Apple Intelligence — that “Apple isn’t building its own chatbot but knows the market wants it so it’s going elsewhere for it. It’s the same playbook as search.” So, again, it is just borrowing from its ages-old playbook. It will continue to have proprietary stuff that ostensibly works seamlessly across a user’s Apple-branded hardware, allow installation of third-party add-ons, and rely on Google for some core functionality. How, exactly, is this a “revamp”?
Anyway, here is what Gurman wrote in January after the Gemini announcement and before the first build of iOS 26.4 was released:
Today, Apple appears to be less than a month away from unveiling the results of this partnership. The company has been planning an announcement of the new Siri in the second half of February, when it will give demonstrations of the functionality.
Whether that takes the form of a major event or a smaller, tightly controlled briefing — perhaps at Apple’s New York media loft — remains unclear. Either way, Apple is just weeks away from finally delivering on the Siri promises made at its Worldwide Developers Conference back in June 2024. At long last, the assistant should be able to tap into personal data and on-screen content to fulfill tasks.
Apple today shipped the first build of iOS 26.5 to developers without any sign of those features. While they may come in a later build, Juli Clover, of MacRumors, speculates they have been kicked to iOS 27.
Sometimes, I do not recognize a trap until I am already in it. Photos in iCloud is one such situation.
When Apple launched iCloud Photo Library in 2014, I was all-in. Not only is it where I store the photos I take on my iPhone, it is where I keep the ones from my digital cameras and my film scans, and everything from my old iPhoto and Aperture libraries. I have culled a bunch of bad photos and I try not to hoard, but it is more-or-less a catalogue of every photo I have taken since mid-2007. I like the idea of a centralized database of my photos, available on all my devices, that is functionally part of my backup strategy.1
But, also, it is large. When I started putting photos in there eleven years ago with a 200 GB plan, I failed to recognize it would become an albatross. iCloud Storage says it is now 1.5 TB and, between the amount of other stuff I have in iCloud and my Family Sharing usage, I have just 82 GB of available space. 2 TB seemed like such a large amount of space until I used 1.9 of it.
Apple’s next iCloud tier is a generous 6 TB, but it costs another $324 per year. I could buy a new 6 TB hard disk annually for that kind of money. While upgrading tiers is, by far, the easiest way to solve this problem, it only kicks that can down that road, the end of which currently has whatever two terabytes’ worth of cans looks like.
A better solution is to recognize I do not need instant access to all 95,000 photos in my library, but iCloud has no room for this kind of nuance. The iCloud syncing preference is either on or off for the entire library.
Unfortunately, trying to explain what goes wrong when you try to deviate from Apple’s model of how photo libraries ought to work will become a bit of a rant. And I will preface this by saying this is all using Photos running on MacOS Ventura, which is many years behind the most recent version of MacOS. It is not possible for me to use the latest version of Photos to make these changes because upgraded libraries cannot be opened by older versions of Photos. However, in my defense, I will also note that the version on Ventura is Photos 8.0 and these are the kinds of bugs and omissions inexcusable after that many revisions.
So: the next best thing is to create a separate Photos library — one that will remain unsynced with iCloud. Photos makes this pretty easy by launching while holding the Option (⌥) key. But how does one move images from one library to the other? Photos is a single-window application — you cannot even open different images in new windows, let alone run separate libraries in separate windows. This should be possible, but it is not.
As a workaround, Apple allows you to import images from one Photos library into another — but not if the source library is synced with iCloud. You therefore need to turn off iCloud sync before proceeding, at which point you may discover that iCloud is not as dependable as you might have expected.
I have “Download Originals to this Mac” enabled, which means that Photos should — should — retain a full copy of my library on my local disk. But when I unchecked the “iCloud Photos” box in Settings, I was greeted by a dialog box informing me that I would lose 817 low-resolution local copies, something which should not exist given my settings, though reassuring me that the originals were indeed safe in iCloud. There is no way to know which photos these are nor, therefore, any way to confirm they are actually stored at full resolution in iCloud. I tried all the usual troubleshooting steps. I repaired my library, then attempted to turn off iCloud Photos; now I had 850 low-resolution local copies. I tried a neat trick where you select all the pictures in your library and select “Play Slideshow”, at which point my Mac said it was downloading 733 original images, then I tried turning off iCloud Photos again and was told I would lose around 150 low-resolution copies.
You will note none of these numbers add or resolve correctly. That is, I have learned, pretty standard for Photos. Currently, it says I have 94,529 photos and 898 videos in the “Library” view, but if I select all the items in that view, it says there are a total of 95,433 items selected, which is not the same as 94,529 + 898. It is only a difference of six items but, also, it is an inexplicable difference of six.
At this point, I figured I would assume those 150 photos were probably in iCloud, sacrifice the low-resolution local copies, and prepare for importing into the second non-synced library I had created. So I did that, switched libraries, and selected my main library for import. You might think reading one Photos library from another stored on the same SSD would be pretty quick. Yes, there are over 95,000 items and they all have associated thumbnails, but it takes only a beat to load the library from scratch in Photos.
It took over thirty minutes.
After I patiently waited that out, I selected a batch of photos from a specific event and chose to import them into an album, so they stay categorized. Oh, that is right — just because you are importing across Photos libraries, that does not mean the structure will be retained. There is no way, as far as I can tell, to keep the same albums across libraries; you need to rebuild them.
After those finished importing, I pulled up my main library again to do the next event. You might expect it to retain some memory of the import source I had only just accessed. No — it took another thirty minutes to load. It does this every time I want to import media from my main library. It is not like that library is changing; it is no longer synced with iCloud, remember. It just treats every time it is opened as the first time.
And it was at this point I realized the importer did not display my library in an organized or logical fashion. I had expected it to be sorted old-to-new since that is how Photos says it is displayed, but I saw photos from many different years all jumbled together. It is almost in order, at times, but then I would notice sequential photos scattered all over.
My guess — and this is only a guess — is that it sub-orders by album, but does no further sorting after that. This is a problem for me given a quirk in my organizational structure. In addition to albums for different events, I have smart albums for each of my cameras and each of my iPhone’s individual lenses. But that still does not excuse the importer’s inability to sort old-to-new. The event I spotted early on and was able to import was basically a fluke. If I continued using this cross-library importing strategy, I would not be able to keep track of which photos I could remove from my main library.
There is another option, which is to export a selection of unmodified originals from my primary library to a folder on disk, and then switch libraries, and import them. This is an imperfect solution. Most obviously, it requires a healthy amount of spare disk space, enough to store the selected set of photos thrice, at least temporarily: once in the primary library, once in the folder, and once in the new library. It also means any adjustments made using the Photos app will be discarded — but, then again, importing directly from the library only copies the edited version of a photo without any of its history or adjustments preserved.
What I would not do, under any circumstance — and what I would strongly recommend anyone avoiding — is to use the Export Photos option. This will produce a bunch of lossy-compressed photos, and you do not want that.
Anyway, on my first attempt of trying the export-originals-then-import process, I exported the 20,528 oldest photos in my library to a folder. Then I switched to the archive library I had created, and imported that same folder. After it was complete, Photos said it had imported 17,848 items, a difference of nearly 3,000 photos. To answer your question: no, I have no idea why, or which ones, or what happened here.
This sucks. And it particularly sucks because most data is at least kind of important, but photos are really important, and I cannot trust this application to handle them.
There is this quote that has stuck with me for nearly twenty years, from Scott Forstall’s introduction to Time Machine (31:30) at WWDC 2006. Maybe it is the message itself or maybe it is the perfectly timed voice crack on the word “awful”, but this resonated with me:
When I look on my Mac, I find these pictures of my kids that, to me, are absolutely priceless. And in fact, I have thousands of these photos.
If I were to lose a single one of these photos, it would be awful. But if I were to lose all of these photos because my hard drive died, I’d be devastated. I never, ever want to lose these photos.
I have this library stored locally and backed up, or at least I though I did. I thought I could trust iCloud to be an extra layer of insurance. What I am now realizing is that iCloud may, in fact, be a liability. The simple fact is that I have no idea the state my photos library is currently in: which photos I have in full resolution locally, which ones are low-resolution with iCloud originals, and which ones have possibly been lost.
The kindest and least cynical interpretation of the state of iCloud Photos is that Apple does not care nearly enough about this “absolutely priceless” data. (A more cynical explanation is, of course, that services revenue has compromised Apple’s standards.) Many of these photos are, in fact, priceless to me, which is why I am questioning whether I want iCloud involved at all. I certainly have no reason to give Apple more money each month to keep wrecking my library.
I will need to dedicate real, significant time to minimizing my iCloud dependence. I will need to check and re-check everything I do as best I can, while recognizing the difficulty I will have in doing so with the limited information I have in my iCloud account. This is undeniably frustrating. I am glad I caught this, however, as I sure had not previously thought nearly as much as I should have about the integrity of my library. Now, I am correcting for it. I hope it is not too late.
It is no longer the sole place I store my photos. I have everything stored locally, too, and that gets backed up with Backblaze. Or, at least, I think I have everything stored locally. ↥︎
In a WWDC 2011 session, Dan Schimpf explained some of the goals of the refreshed design for Aqua in Mac OS X Lion were “meant to focus the user attention on the active window content”. This sentiment was echoed by John Siracusa in his review of Lion for Ars Technica:
Apple says that its goal with the Lion user interface was to highlight content by de-emphasizing the surrounding user interface elements.
[…] a fresh modern look where controls are clearer, smarter and easier to understand, and streamlined toolbars put the focus on your content without compromising functionality.
Then, when it revealed the Big Sur redesign in 2020, it explained:
The entire experience feels more focused, fresh, and familiar, reducing visual complexity and bringing users’ content front and centre.
And you will never guess what it promised in 2025 with the announcement of MacOS Tahoe and Liquid Glass, as introduced by Alan Dye:
Our goal is a beautiful new design that brings joy and delight to every user experience. One that’s more personal, and puts greater focus on your content — all while still feeling instantly familiar.
It is not just Apple, either. Here is Microsoft’s Jensen Harris at Build 2011 describing a key goal for the company’s then-new Metro design language:
Metro-style apps have room to breathe. They’re not about the chrome, they’re about the content. […] For years, Windows was always about adding stuff. We added bars, and panes, and doodads, and widgets, and gadgets, and bars — and stuff everywhere. And that’s how we defined our U.I., based on what new widgets we added. Now, we’ve receded into the background, and the app is sitting out there on the stage.
And later, as Microsoft rolled out app updates with its Fluent Design language, it described them in familiar terms:
With the updated OneDrive, your content takes center stage. The improved visual design reduces clutter and distractions, allowing you to focus on what’s important – your content.
This is a laudable goal if the opposite is, I assume, increasing the amount of clutter in user interfaces and making them more distracting. Nobody wants that. Then again, while the objective may be quite reasonable, there are surely different ways of achieving it — but Apple has embraced a single strategy: make the interface blend into the document. (I will be focusing on MacOS here as it is the platform I am most familiar with.)
Here is what a Pages document looks like running under Mac OS X Lion:
Click to expand (except on mobile).
Here is that same document in a newer version of Pages running on MacOS Catalina, with the Yosemite-era design language that replaced the one that came before:
Click to expand (except on mobile).
Here it is in the last version of Pages on MacOS Tahoe, using the design language introduced with Big Sur:
Click to expand (except on mobile).
And, finally, the newest version of Pages on MacOS Tahoe using the current Liquid Glass visual design language:
Click to expand (except on mobile).
There are welcome improvements in newer versions of this comparison, like the introduction of the “Format” panel on the right-hand side, which makes better use of widescreen landscape-oriented displays, and allows for larger controls. While I admire the density of the Lion-era screenshot, the mini-sized controls in that formatting menu are harder to click.1
Overall, however, what Apple has done to Pages over this period of time is representative of a broader trend of minimizing the delineation of user interface elements from each other and the document itself. This is the only tool in the toolbox, and I am skeptical it achieves what Apple intends.
Compare again the two more recent screenshots against the ones that came before, and focus on the toolbar at the top of each. In the older two, there is a well-defined separation between the toolbar — the window itself — and the document. In the Big Sur visual language, however, the toolbar is the same bright white as the document. By Tahoe and the Liquid Glass language, there is barely a distinction; the buttons simply float over the document. And, bizarrely, that degrades further with the “Reduce Transparency” accessibility preference enabled:
Click to expand (except on mobile).
(Also, no, your eyes do not deceive you: the icons in the drop cap menu, barely visible in the lower-right, are indeed pixellated.)
For me, this means a constant distraction from my document because the whole window has a similar visual language. As the toolbar and its buttons become one with the document, they lose their ability to fade into the background. In the two older examples, the contrast of the well-defined toolbar allows me to treat them as an entirely separate thing I do not need to pay attention to.
This is further justified by the lower contrast within those two older toolbars. In Lion, the grey background and moderately saturated colours are a quiet reminder of tools that are available without them being intrusive. The mix of shapes is a sufficient differentiator, something Apple threw away in the following screenshot. By making all the buttons literal and with the same bright background, the toolbar becomes a little more distracting — but at least it does not blend into the document. Without the context of the previous screenshot, the colours of each icon seem almost random, and I find the yellow-on-white “Table” button difficult to distinguish at a glance from the black-on-yellow-on-white “Comment” button.
The Big Sur-era design language is, frankly, an atrocious regression. The heterogeneous shapes may have returned, but in the form of monochromatic medium-grey icons set against a uniform white background. The icons are not bad, per se — though putting “Add Page” and “Insert” next to each other in this default toolbar layout, both represented by a plus sign, is a little confusing. But I will bet you would not guess that some of these are buttons, while others are pop-up buttons with a submenu.
Finally, there is Liquid Glass which, in its default form, has more contrast than the previous example; with “Reduce Transparency” enabled, which is how I use MacOS, it has even less. The buttons themselves have a greater amount of internal contrast with bigger, darker grey icons on a white background. This is preferential within the context of the toolbar compared to the thin, small, and low-contrast buttons in the past example, but it also means this toolbar has similar contrast to the document itself.
I would not go so far as to argue that Pages ’09 has a perfect user interface and that everything since has been a regression. The average colours used for the icon fill in both older toolbars generally fails accessibility contrast checks which, remarkably, the Big Sur design will pass. The icons in Pages ’09 rely on dark outlines and unique shapes to have sufficient contrast with the toolbar background. However, Apple has since discarded most variables it could change to design these interfaces. Every button contains an icon of a single uniform colour, within barely defined holding containers of the same shape, and without text labels by default.
This monochromatic look means any splash of colour is distracting. The yellow accent used in Pages is garish — though, thankfully, something that can mostly be mitigated by changing the Theme Colour in System Settings, under Appearance. (Unfortunately, the yellow background remains on the “Update” button in the most recent version of Pages regardless of the system accent colour.) But perhaps you also noticed the purple icon in the Liquid Glass screenshot above. Here is the full toolbar:
Click to expand (except on mobile).
Those purple icons signify features that are part of Apple Creator Studio, a paid subscription to Pages and other applications that allows you to — in the order they are presented above — generate an image, artificially boost the resolution of an image, and access a stock image library. If you would like to insert one of your own images into your Pages document, that feature has been moved to the paperclip icon. Yes, it is a menu and not a button, despite lacking the disclosure triangle of the zoom menu right beside it, and it also reminds you about the “Content Hub” and “Generate Image” features. In Pages under Lion, colour was used in the icons to help guide the user as they complete a task — click the green thing to add a shape; click the darker yellow thing to add a table. Colour is not being used in the newer version to signify these are A.I. features, as the “Writing Tools” icon remains dark grey. In this version, the coloured icons are there to guide the user to premium add-ons regardless of whether they are currently paying for them.
I decided to focus on Pages for this comparison because it has lived so many different lives in MacOS. However, it is perhaps an imperfect representation for the rest of the system. Across Mac OS X Lion, for example, the toolbars of first-party applications like Finder and Preview almost exclusively use monochromatic icons. This has been true since Mac OS X Leopard, which also introduced barely differentiated folder icons. Some toolbars in Tiger, introduced two years prior, featured icons inside uniform capsule shapes. These were questionable ideas at the time, but they still retained defining characteristics. The capsules, for example, may have had a uniform shape, but contained within were full-colour icons. Most importantly, they were all clearly controls that were differentiated from the document.
Perhaps Apple has some user studies that suggest otherwise, but I cannot see how dialling back the lines between interface and document is supposed to be beneficial for the user. It does not, in my use, result in less distraction while I am working in these apps. In fact, it often does the opposite. I do not think the prescription is rolling back to a decade-old design language. However, I think Apple should consider exploring the wealth of variables it can change to differentiate tools within toolbars, and to more clearly delineate window chrome from document.
These screenshots are a bit limited as, to capture a high-resolution interface, I switched my mid-2012 MacBook Air to a 720 × 450 display output, which shrank the available space for Pages in the Lion and Catalina screenshots. ↥︎
Jason Snell has published the results from his annual survey of a panel of Apple observers and, as I expected, there seems to be wide agreement that the company’s software quality is not up to scratch thanks primarily to Liquid Glass. This year’s average score of 2.7 for operating system quality and 3.1 for first-party app quality is a decline from the average score of 3.4 and 3.5, respectively, last year.
But look back a little further and the grades for Apple’s software quality have been hovering at a similar level for a while: 3.6 in 2023, 3.4 both years prior, and 3.5 in 2020. This is well below the average hardware reliability ranking which is a full point higher, and does not match the typical grades given to the Mac and iPhone in the same time frame. Snell converts the software score to an average letter grade of B to B–. Is Apple satisfied with shipping a consistently B product?
I confess the grade I have given has been lower than this average. My experience with Apple’s software for the past several years has been markedly less than fine. Given that my scores have deviated from those given by many others, I started to question my own fairness — which, given that I am merely A Guy giving my opinion about a multi-trillion-dollar corporation, is a little silly. Then again, software is made — mostly — by people, and the intent I have in participating in the Six Colors survey is that a person working at Apple might possibly read my feedback.
When I think about the quality of something, I put my expectations in context. If I were thinking about the quality of a restaurant meal, for example, it is not enough to merely provide sustenance. It must taste good, should look good, and ideally be more interesting than the individual ingredients suggest. The balance is different in software. The most important factor is whether the features I use perform as expected. If it does so with unique design and flair, that is a welcome bonus, but it must be built on a solid foundation.
In short, the way I think about software quality is the amount of meaningful problems.
I use three of Apple’s platforms across five devices: an iPhone 15 Pro, a 14-inch M1 Pro MacBook Pro, a 27-inch iMac 5K, and two generations of Apple TV. Each of these is running the latest capable software — all OS 26 except the iMac, which is stuck on MacOS Ventura. I use iCloud to sync a bunch of stuff. I can set aside Liquid Glass and related design decisions for now because there are more fundamental concerns. Even in this limited set of products, I stumble constantly into the kinds of bugs that impact core parts of the system.
There are problems in Finder — resizing columns, renaming or deleting files synced with a FileProvider-based app, and different views not reflecting immediate reality. There are problems with resizing windows. AirPlay randomly drops its connection. AirDrop and other “continuity” services do not always work or, in an interesting twist I experienced a couple days ago, work fine but display an error anyway. The AirPlay and AirDrop menus shuffle options just in time for you to tap the wrong one. The translation button loads in Safari on the opposite side of the address bar from where you can actually open translation options. On my iMac, the scroll bar in Safari no longer reflects the scroll position of the webpage. The Contacts app on MacOS barely works. The Apple Pay handshake between a Mac and my iPhone is unreliable. My iPhone does not always set aside software update space, but it also refuses to purge cached iCloud-stored photos. I have to confirm I trust my own iMac nearly every time I plug in my iPhone to sync. One word: Siri. Okay, let me expand on Siri with a more recent bug: when I tell it to pause music, it sometimes asks me to confirm I want to pause by tapping the screen, and the only time I ever do this is because I am cooking and my hands are full or dirty. These are just some of the bugs I experience regularly — some are papercuts, while others are a throbbing migraine.
These are the products and features I actually use. There are plenty others I do not. I assume syncing my music collection over iCloud remains untrustworthy. Shortcuts seems largely forgotten. Meanwhile, any app augmented by one of Apple’s paid services — Fitness, News, TV — has turned into an upselling experience.
I am somewhat impressed by the breadth of Apple’s current offerings as I consider all the ways they are failing me, and I cannot help but wonder if it is that breadth that is contributing to the unreliability of this software. Or perhaps it is the company’s annual treadmill. There was a time when remaining on an older major version of an operating system or some piece of software meant you traded the excitement of new features for the predictability of stability. That trade-off no longer exists; software-as-a-service means an older version is just old, not necessarily more reliable.
The most incredible thing is that this software is shipping on hardware that feels damn near bulletproof. I am frustrated by the unitary quality of these devices, unable to be upgraded post-purchase, and I quibble with some choices made over the years. The butterfly keyboard fiasco was notable because it was such an outlier. There is a clear expectation for what Apple considers acceptable to ship in aluminum and glass, and it does not apply to bits or GET requests.
Yet, if you were to ask a Mac user whether they would be happier with Windows on a high-spec MacBook Pro, or MacOS on some gaming pc, I bet they would rather give up the hardware than the software. I would. Similarly, I bet most people would prefer iOS on some run-of-the-mill Android hardware. Software is hard, and frequent over-the-air updates mean it is possible to meet a launch deadline even if some problems will be solved later.
What I expect out of the software I use is a level of quality I simply do not see. I do not think I have a very high bar. The bugs in the big paragraph above are not preferences or odd use cases. They are problems with the fundamentals of the operating system and first-party apps. I do not have unreasonable expectations for how things should work, only that they ought to work as described and marketed. But complaints of this sort have echoed for over a decade and it seems to me that many core issues remain unaddressed.
People buy hardware, and it shows. People subscribe to services. But people use software. This is not solely an Apple problem. Many of us spend our time fighting with tools that feel unfinished and flawed; it seems to have become the norm. But it is particularly glaring when the same attitude is taken by Apple, a company that ships some of the nicest hardware in the business. I would love to see the same tolerances for what is shown onscreen as Apple has for how the screen is made.
Jeremy Freed, of GQ, in an article with the provocative headline “You Won’t Be Able to Escape Smart Glasses in 2026”:
“If AI glasses are going to go mainstream, 2026 will be the year that we start to see that,” says Sinead Bovell, a futurist and the founder of tech education company, WAYE. Meta introduced its first line of Ray-Ban AI Glasses in 2021, and has sold more than 2 million pairs since launching the second generation in 2023. By the end of 2026, the company plans to sell 3 million more while ramping up production to 10 million pairs annually. As hard as it is to imagine 10 million people — the combined populations of NYC and Philly — buying Meta AI Glasses every year, it may well come to pass. “The iPhone came out in 2007 and by 2011 BlackBerry was still the number-one smartphone,” says Bovell. “The iPhone wasn’t seen as a phone, it was seen as a toy. The exact same things that were said about it in 2008 are being said now about [smart] glasses.” Likewise, no one knew they needed an Apple Watch when the product launched in 2015, but the company has reportedly sold hundreds of millions of them since then.
This article was published a day after people from, presumably, Meta or EssilorLuxottica told Bloomberg they were going to double production to 20 million units by the end of this year in response to overwhelming demand. So from two million since 2023, three million this year alone, to twenty million next year — that is quite the forecasted sales curve. It is almost enough to make you think Meta has a hardware hit on its hands.
As for Bovell’s claim that the “exact same things that were said about it [the iPhone] in 2008 are being said now about [smart] glasses”, the problem is that there is a far better comparison given we have already had an example of smart glasses in Google Glass, and the same things were being said about those a decade ago. In 2012, CBC News quoted a researcher saying Glass is “the mainstreaming of this kind of device”. In 2013, Jessica Guynn, of the Los Angeles Times, wrote that they “may still be on the fringes of mainstream consciousness. But they are not going to stay there very long”. The following year, Paul Saffo lamented for CNN that while “[i]nfo-glasses today are like PCs in 1984 – they look cool but perform a few functions that aren’t all that useful, such as taking pictures or surfing the Web while sitting in a bar with friends” — yes, “they look cool” is presented as a factual statement — in the very near future from 2014 “we are certain to be astonished by the capabilities of the device sitting on the bridge of our nose”.
Well, it has been nearly twelve years since Saffo wrote that, and the killer capabilities of smart glasses remain based entirely around the camera. And you know what? It is a pretty good feature — but it alone is not as compelling today as was a smartphone in 2008. I do not think the question is are smart glasses today akin to smartphones in 2008?; the question is more like what is different about today’s smart glasses compared to Google Glass?. To his credit, Freed attempts to answer this in noting that Meta’s Wayfarer shape instead of a sci-fi is an obvious upgrade, but I think he underplays the advancements in image, language, and speech detection since Google Glass by calling it “a Siri-like voice assistant”. GQ is not a technology publication, true, but that is among the biggest changes for a device so dependent on real-time interaction with the surrounding environment, like for translation features.
But there are problems with today’s smart glasses that remain unchanged from those that affected Google Glass. Most obviously, they are still a privacy nightmare for yourself and for others. Meta says the externally-visible recording LED must not be obstructed to record video, but people are modifying the glasses to remove that restriction. They must effectively be treated like spy glasses because they could be recording anywhere — in a public area running facial recognition software, to the apparent privacy of a massage room.
Meta is far from the only company producing glasses like these. Snap has its Spectacles and Xiaomi’s A.I. Glasses are available in China. All of these companies are responsible for developing a selfish future that prioritizes selling buyers on the advantages of an unobtrusive camera while barely acknowledging the societal impact of the same. Google is taking another kick at the can, and rumours consistently indicate Apple and Samsung are each working on their own, too. They may all say the right things about privacy, but the fundamental fact is that a barely-visible camera is a tool for abuse as much as it is entertainment.
Freed:
Whether the possibilities presented by smart glasses sound fun and appealing or like the tipping point into a dystopian nightmare is a matter of perspective. There are the obvious doubts about what happens if someone hacks your glasses and what companies like Meta are planning to do with your data (spoiler alert: it’s being used to train AI), but these aren’t so different from existing concerns around other internet-enabled devices. “Every piece of technology ever created has been used for good and bad things,” says Edward R. McNicholas, a Partner at Ropes & Gray in Washington DC who leads the firm’s global data, privacy and cybersecurity practice. “Just think of the Internet itself — it helps bad actors, but it brings the globe together, creates enormous economic opportunity, and inspires millions.” What will ultimately decide the fate of smart glasses, he says, is regulatory friction — and cultural embrace. “That is, what’s the rizz? Do the 20-somethings deem it based or cringe?”
McNicholas was admitted to the Maryland bar in 1996. His career as a lawyer is at least Millennial-aged and, as a Millennial myself, I feel pretty confident in saying he cannot use “rizz”, “based”, or “cringe” like this. It is not, in fact, lit.
I find it difficult to believe it is a coincidence there are two stories promoting Meta’s A.I. glasses appearing in the news the same week Meta laid off ten percent of its Reality Labs employees, and reallocating funds to the team developing those glasses. I am sure these things have their defenders, and may be more popular than Meta expected given the company’s long run of hardware flops. The relative success of the glasses means Meta can jettison its original messy concept of the metaverse and redefine it to suit its needs today.
But this does not feel like the nascent days of the iPhone, nor like we will not “be able to escape smart glasses” this year. I knew lots of people with smartphones in the mid-to-late-2000s, including some with original iPhones despite them not being available in Canada. Anecdotally, I do not personally know anyone who owns or is even thinking about buying smart glasses. Mind you, I know plenty of people with an Apple Watch today who did not consider it compelling even years after it launched. Maybe it is like the early days of smartwatch ownership, after all, and I simply do not notice because Meta’s glasses just look like Ray-Bans. That is, I guess, the whole point.
Despite the concept of smart glasses being the product of so much hype and excitement, it never seems to have materialized in something you can buy. Maybe that will change; maybe that has changed without me noticing it. But one of the other biggest shifts of the past ten years is how much people say they want more distance from technology. One of the predictions for 2026 in a list from the New York Times is the rise of the “dumb phone” as a status symbol. Some people who have tried smartwatches have found them more demanding over time than helpful; I stopped wearing one after four years because I need less technology in my life, not more. There is a vast gulf between what people say they want and their actual behaviour, of course, but I cannot shake the feeling this technology is still too much of an imposition. We will not need to “escape smart glasses” if people still choose not to buy them.
I made a mistake on Friday: instead of waiting to polish a more comprehensive article, I effectively live-blogged my shifting understanding of how StatCounter was collecting its iOS version number data by way of updates and edits to existing posts. In my own defence, I did not know the rate of users updating to iOS 26 would become as much of a story unto itself as it has. So allow me to straighten this out.
Here is the background: StatCounter publishes market share data by country and user technology based on statistics it collects from its web analytics package which, it says, is used by over a million websites totalling around five billion page views monthly. I have not heard of many of the sites using its analytics, but it seems to be a large enough and generic enough sample that it should be indicative — more so than, say, visitors to my audience-specific website. Ed Hardy, over at Cult of Mac, used StatCounter’s figures to report, on January 8, that “only about 15% of iPhone users have some version of the new operating system installed”. Hardy compared this to historical StatCounter figures showing a 63% adoption rate of iOS 18 by the same time last year, 54% on iOS 17 the year prior, and 62% on iOS 16 the year before that. If true, this would represent a catastrophic reluctance of iPhone users to update.
If true.
I do not think the iOS 26 uptake rate is about 15%. I think it is lower than the 54–63% range in previous years, but not by nearly that much. I think StatCounter has been misinterpreting iOS 26’s user base since last year because of a change Apple made to Safari.
If the phrase “user agent” does not make you respond by tipping your head to the side like my dog did when I asked him if he knew what I meant by that, you can skip this paragraph. A user agent string is a way for software to identify itself when it makes an HTTP request on behalf of a user. A user agent might describe the type and version of a web browser, the operating system, and have other information so that, in the old days, websites could check for compatibility. This leads to user agent strings that look a little silly:
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/134.0.0.0 Safari/537.36 Edg/134.0.0.
This does not represent a Firefox user, despite starting with “Mozilla”, nor does it represent a Safari or Chrome user, despite the mentions of “Safari”, “Chrome”, and “AppleWebKit”. It is a user agent string for Microsoft Edge, which is begging to be treated like its competitors.
This is a simplified explanation, but it is important for how StatCounter works. When someone browses a website containing its analytics code, it reads the user agent string, and that is how StatCounter determines market share. The above user would be counted for Edge market share (“Edg/134.0.0”) and Windows. Which version of Windows? Well, while “NT 10.0” suggests it is Windows 10, it is also used by Edge running on Windows 11 — that part of the user string has been frozen. The Chromium team did the same thing and reduced the amount of specific information in the user agent string. This removes a method of fingerprinting and is generally fine.
This movement was spearheaded by Apple in 2017, when Ricky Mondello announced Safari Technology Preview 46 “freezes Safari’s user agent string. It will not change in the future”. But this remained a desktop-only change until September 2025, when Jen Simmons and others who work on WebKit, announced that the version of Safari shipping in iOS 26 would have its user agent stuck on the previous version of iOS:
Also, now in Safari on iOS, iPadOS, and visionOS 26 the user agent string no longer lists the current version of the operating system. Safari 18.6 on iOS has a UA string of:
Mozilla/5.0 (iPhone; CPU iPhone OS 18_6 like Mac OS X) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/18.6 Mobile/15E148 Safari/604.1
And Safari 26.0 on iOS has a UA string of:
Mozilla/5.0 (iPhone; CPU iPhone OS 18_6 like Mac OS X) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/26.0 Mobile/15E148 Safari/604.1
Apple justified this change only by implication, writing “we highly recommend using feature detection instead of UA string detection when writing conditional code”. But, as Jeff Johnson points out, this change does not eliminate version detection entirely:
[…] because Safari is always inseparable from the OS, so it’s possible to derive the iOS version from the Safari version, which continues to be incremented in the User-Agent. On macOS, in contrast, the latest version of Safari typically supports the three latest major OS versions, so Safari 26 can be installed on macOS 15 Sequoia and macOS 14 Sonoma in addition to macOS 26 Tahoe, and therefore the User-Agent — which actually says “OS X 10_15_7”! — is a little more effective at obscuring the OS version.
I noticed this, too, and it led to a mistake I made in my first guess at understanding why StatCounter was reporting some iOS 26 traffic, but not a lot. I thought StatCounter could have made a change to its analytics package to interpret this part of the user agent string instead, but that it may not have rolled out to all of its users. I was wrong.
What actually appears to account for iOS 26’s seemingly pitiful adoption rate is that third-party browsers like Chrome and Brave produce a user agent string that looks like this, on my iPhone running iOS 26.3:
Mozilla/5.0 (iPhone; CPU iPhone OS 26_3_0 like Mac OS X) AppleWebKit/605.1.15 (KHTML, like Gecko) CriOS/144.0.7559.53 Mobile/15E148 Safari/604.1
Safari, meanwhile, produces this user agent:
Mozilla/5.0 (iPhone; CPU iPhone OS 18_7 like Mac OS X) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/26.3 Mobile/15E148 Safari/604.1
“iPhone OS 26_3_0” on Chrome, but “iPhone OS 18_7” in Safari. And iOS 18.7 also exists, with a similar user agent string as Safari, albeit with “Version/18.7” in place of “Version/26.3”. The operating system version is the same in both, however: “18_7”. StatCounter’s iOS 26 data is not reflective of all iOS users — just those using third-party browsers that still have the current iOS version in their user agent string.
Even though third-party browsers are available on iOS, most users browse the web through Safari. And that means StatCounter is almost certainly counting the vast majority of people on iOS 26 as iOS 18.7 users. I retrieved those user agent strings using StatCounter’s detection utility, which is how it says you can validate the accuracy of its statistics. And it seems they are not. (I asked StatCounter to confirm this but have not heard back. Update: StatCounter’s CEO told me iOS 26 users had been miscounted.)
The actual rate of iOS 26 adoption is difficult to know right now. Web traffic to generalist websites, like the type collected by StatCounter, seems to me like it would be a good proxy had its measurement capabilities kept up with changes to iOS. Other sources, like TelemetryDeck, indicate a far higher market share — 55% as I am writing this — but its own stats reported nearly 78% adoption of iOS 18 at this time last year, also greater than StatCounter’s 63%, but not by as much. TelemetryDeck’s numbers are based on aggregate data from its in-app analytics product, so they should be more accurate, but that also depends on which apps integrate TelemetryDeck and who uses them. What we can see, though, is the difference between last year and this year at the same time, around 23 percentage points. For comparison, in January 2024, TelemetryDeck reported around 74% had updated to iOS 17 — iOS 26 is 19 points less.
If its reporting for this year is similarly representative, it likely indicates a 20-point slide in iOS 26 adoption. Not nearly as terrible as the misleading StatCounter dashboard suggests, but still a huge and embarrassing difference compared to prior years. Apple will likely update its own figures in the coming weeks for a further point of comparison. However, even though there are early indications iOS 26 is not as well-received as its predecessors, what we do not know is why that is. Fear not, however, for there are obvious conclusions to be drawn.
It’s not that millions of iPhone users around the world have somehow overlooked the launch of iOS 26 followed by iOS 26.1 and iOS 26.2. They are holding off installing the upgrades because this is Apple’s most controversial new version in many years. The reason: Liquid Glass — a translucent and fluid new interface. Many elements of the UI go semi-transparent, while clever effects make it seem like users are looking through glass at objects shown on the screen behind the Control Center and pop-up windows.
David Price, of Macworld, made the same assumption based on Hardy’s story — twice:
It’s debatable whether the egregious design of last year’s OS updates falls under the category of arrogance or incompetence; perhaps it’s both. But the takeaway for Apple should be that customer loyalty is finite, and there are consequences when you consistently lower your quality-control standards. When your entire business is built on people liking you, it’s best not to take them for granted.
I have no particular affinity for Liquid Glass. I am not sure its goals are well-conceived, and I do not think it achieves those objectives.
Even so, I think the aversion to Liquid Glass is so strong among some commentators that erroneous stats are fine so long as they are confirmation of their biases. Put it this way: if just 15% of users had, indeed, upgraded to iOS 26 and the reason for so many people remaining on previous versions is Liquid Glass, surely that should mean a corrected percentage — perhaps 55%, perhaps lower — is indicative that most people are not actually bothered by Liquid Glass, right?
Yes, there is a likely 20-point gap and, if that is due to Liquid Glass, it should be cause for worry at the highest levels of Apple. iOS is a mass-market operating system. The audience is not necessarily obsessed with information density or an adequate contrast ratio. If a redesign of iOS were exciting, people would have raced to update, just as they did when iOS 7 was launched. They instead appear hesitant. Maybe the reason is Liquid Glass, or maybe something else. Or maybe there are further measurement errors.
Whatever the case, I would avoid believing articles making sweeping conclusions based on a single data point. After all, if that number is shown to be incorrect, it destabilizes the whole argument.
I am not sure which was the first of Google’s A.I. ads I saw that made me wonder if I was suffering from a fever. Maybe it was the one where “pandas in high fashion outfits walk the runway” — shown over thirty million times since early November, as of writing — but it just as easily could have been the one with “some crazy fruit creatures”. Maybe it was the ad with the strutting dogs. All are equally bizarre in the way a giant corporation’s ad company thinks it is offering something quirky and weird.
In any case, each ends with the same encouragement: “make more videos with a Google A.I. Pro subscription” for $27 per month. And I have to ask: who is this for?
These are not the only ads Google is running for its A.I. features. It shows them off in context for general users in Pixel phone ads, for students in ads for NotebookLM, for corporate clients with Cloud A.I., and — of course — for advertisers.
It also is not the only ad for its A.I. Pro subscription bundle. In a different one, different tasks are strung together for someone to do absolutely no work to put together a ’90s trivia night, leading to an invitation that twice tells recipients to wear platform shoes and “get ready”. The fine print might remind viewers to “check responses for accuracy”, but in the ad, the creator clicks send on a terribly written invitation immediately.
But it is those bizarre animal-themed ones which led to me looking up the advertising strategies of all the big A.I. players. I think this is a fascinating window. The ads they pay to show give us a glimpse of how they idealize the use of these products and services. While ads can sometimes be abstracted from the true function of a product or service, A.I. is already a new and confusing thing, so the narrative each company spins about its narrative seems telling of its own vision. I limited my search on this to ads of a typical video spot — no more than 30 seconds long. I did not include case studies or company-produced tutorials.
OpenAI runs a couple of types of ads. Those for ChatGPT mostly show its use as a personal assistant. There are several 30-second spots shot as oners with a pleasingly retro warmth. One has a training regiment for learning to do pull-ups; another is about siblings on a road trip. The same kind of messaging is used in a series of shorter spots. It also runs ads for its Codex agent, obviously targeted at developers, that are more clinical.
All of these seem practical to me. I could not find any current ads from OpenAI as disconnected from reality as Google’s. Just as notable is the focus of OpenAI’s spots — Google’s Ads Transparency Centre says the company is running about two hundred ads in Canada right now, most of which are variations in size, targeting, and placement of the shorter practical examples above, plus ads for Codex. For comparison, Google’s ads are all over the place. It is running around twenty thousand ads right now in Canada and, though not all of them are for A.I. features, many are, and you can tell from the examples above how much Google is just throwing stuff at the wall.
Anthropic’s ads are far more limited. All are for Claude and feature a video ad with no indication of how it is being used. It simply says “Claude is A.I. for […] all of us, anywhere” with overhead shots of different scenes representing different professions. This is basically the same sentiment as OpenAI’s ads, but executed without any specificity or examples. The company’s YouTube channel has plenty of case studies and demos, but no similar video spots.
If Anthropic is trying to mimic OpenAI’s quiet confidence, Perplexity has chosen overt aggression. Quasi-influencertypes followa similar script saying ChatGPT makes things up, and that is why you should trust Perplexity as it “searches the entire internet in less than one second and gives you one verified answer”. This explanation avoids acknowledging how much Perplexity depends on external A.I. models, including OpenAI’s GPT. In two of the ads, the narrator asks health-related questions, which is the boldest and maybe most reckless use case I have seen in any A.I. ad. There is nothing wrong with the answers it has generated, so far as I can tell, but it seems like a higher-stakes use than, like, a cake recipe, for example. In a variation of this ad type, the “influencer” looks generated, and contains Google search result screenshots that are at least twelve years old. Whatever the case, Perplexity must be spending huge amounts on its advertising. Each of these has been shown tens of millions of times, and two have hundreds of millions of views.
Meta’s ads are bizarre. I could not find any video ads for A.I. stuff — or metaverse-related things — through Google’s Ads Transparency Centre, but the company has a handful of 30-second spots on its YouTube channel. Almost like Google, Meta does not seem to know why people would use its A.I. assistant, so it comes up with offbeat premises that fall flat. In one, described as a way to “help sharpen your skills and transform the way you learn and understand complex subjects”, a guy is meeting his partner’s dad, a thermodynamicist. What a real person who is good at conversations would do is ask the dad a bunch of questions. What Meta thinks you should do is ask its assistant those questions instead and develop a fake level of expertise.
Also, not for nothing, but when I asked the same question in the web version of Meta A.I., it responded not with the tight and efficient explanation in the ad, but with:
😂 Thermodynamics-ist? Sounds like a real party crusher, eh? 🤣 Okay, serious face… A thermodynamicist is like, someone who’s all about the study of heat, energy, and how they transform into each other. They’re like the ultimate energy nerds, but in a good way! 🤓 They work with stuff like engines, refrigeration, and even black holes (mind blown, right? 🤯). Basically, they help us understand how to harness and use energy efficiently. Pretty cool, eh?
Am I meant to be charmed by “okay, serious face…” and four emoji in this barely coherent response? Because I am not.
In another ad, a guy somehow turns a large pan of what appears to be milk and two other pans of mystery liquid into pancakes for his kid. The kid pushes the plate off the counter, the dad asks “how can I get my two-year-old to eat his breakfast?”, and Meta A.I. knows that the kid likes when he makes silly faces. It is unclear to me how it knows this — whether it is automatically personalized to this user, or something the dad needed to teach the system, or if it is just an assumption that all two-year-olds like silly faces. The impression I get, though, is that it is distinctly unbelievable, and I do not want to give Meta knowledge of my entire life to find out if I am right.
To round this out, I looked for similar ads from Microsoft and Apple. I scrolled through hundreds of Microsoft ads on Google’s Ads Transparency tool, virtually all of which were Xbox related. I also checked its YouTube channel. I did not see any ads of the same type as above. I also found only a couple of ads for Apple Intelligence on Apple’s YouTube channel, both of which are for Clean Up in Photos. Apple seems to have cleaned up its YouTube channel overall, removing a whole bunch of older ads including some for Apple Intelligence.
I do not want to overstate how much these ads tell us — they are ads, you know? — but I think I learned something from the way each of these businesses thinks of its own products. In OpenAI, I see confidence; in Anthropic and Perplexity, I see an attempt to catch up. And in Google and Meta, I see established companies that are desperate to prove themselves — particularly in Google’s case, as I still cannot understand why generating arbitrary video is supposed to be compelling to a broad audience.
In the most practical and grounded ads, what I do not see are significant leaps beyond what a search engine today could do. OpenAI’s ads show ChatGPT summarizing a workout plan, but there are loads of those on external websites. Guides to road tripping through the Blue Ridge Parkway are plentiful. The same is true of the responses in Perplexity’s ads. What I see most in these ads are the big “pure” A.I. players normalizing their raison d’être, and established mega corporations entirely out of touch with what someone might want to do. Both are embarrassing in their own way for what is often pitched as the most revolutionary technology since the internet.
2025 was a tough year for pretty much everyone I know, and I imagine the coming year will bring more of the same dreary news. I thought I would start off 2026 with something much dumber. I have plumbed the depths and found the bottom of the deepest of barrels, and that is how you are reading an “I asked ChatGPT” post.
There is a minor point here. I needed to use up a cup of milk and a quarter-cup of sour cream lurking in my fridge, and I wanted to make some kind of quick bread or loaf with it. The problem is that I am an inexperienced baker and I do not have a great sense of the proportion of other ingredients I would need.
I think this is the kind of thing a more advanced search engine could help with. I have previously used recipe finder tools like Supercook and RecipeRadar but, while they often ask what ingredients are available, they usually do not do so in specific quantities, necessitating looking through a bunch of recipes to find one that fits. Something that can process longer natural language queries seems tailor made for this kind of task.
I told it “I would like loaf/quick bread recipes that will use up 1 cup of milk and ¼ cup of sour cream”, and ChatGPT gave me four options. The first, a “classic vanilla quick bread”, looked adequate, but boring. (Also, a careful reader will quibble with its “optional add-ins (1–1½ cups total)” after which is a list of, among other things, cinnamon, and I do not think you should add a whole cup of cinnamon to anything.) I do like cinnamon, though, and I settled on the fourth suggestion, a “cinnamon swirl coffee bread”. Here is the entirety of its recipe:
Batter
2 cups flour
¾ cup sugar
1½ tsp baking powder
½ tsp baking soda
½ tsp salt
1 cup milk
¼ cup sour cream
⅓ cup oil
2 eggs
1 tsp vanilla
Swirl
⅓ cup brown sugar
1½ tsp cinnamon
Bake
Layer batter + swirl in pan, gently knife once
350°F for 50–60 min
The ingredient list, to my untrained eye, seems fine. The instructions are obviously incoherent. More comprehensive directions were offered for the “classic vanilla quick bread” above it, which I missed because I only followed this recipe. Since I made a different loaf recently, however, I had a rough idea of what I should do. Also, I made a couple of minor changes:
I substituted vanilla extract for a few dashes of Fee Brothers’ cardamom bitters.
I had no ground cinnamon on hand and grating a cinnamon stick is tedious, so I stopped after about a teaspoon.
While these ingredient substitutions might affect the flavour, they would not materially affect the chemistry.
The resulting loaf is fine. I was hoping for either catastrophic failure or incredible success to more wholly justify this low-effort post, but it was just fine. Better than I expected, given where it came from, though the brown sugar swirl is achingly sweet and settled in the middle despite my best attempts. I still do not know what “gently knife once” is supposed to mean. I would not confuse this with a professional baker’s work, of course, but that is more like operator error. I wish the directions were, overall, clearer; if I had little to no previous experience baking a quick bread, I might have been lost.
I have experimented with ChatGPT and food before, particularly for weekly meal planning, and I have never been satisfied with its results. This, though, worked pretty well for me. I got to use up a couple of things in my fridge and made an okay dessert from it. Happy New Year.
The surprise departure of Alan Dye announced a week ago today provoked an outpouring of reactions both thoughtful and puerile. The general consensus seemed to be oh, hell yeah, with seemingly few lining up to defend Dye’s overseeing of Apple’s software design efforts. But something has been gnawing at me all week reading take after take, and I think it was captured perfectly by Jason Snell, of Six Colors, last week:
So. In the spirit of not making it personal, I think it’s hard to pile all of Apple’s software design missteps over the last few years at the feet of Alan Dye. He had support from other executives. He led a whole team of designers. Corporate initiatives and priorities can lead even the most well-meaning of people into places they end up regretting.
That said, Alan Dye has represented Apple’s design team in the same way that Jony Ive did ever since Jony took over software design. He was the public face of Liquid Glass. He has been a frequent target of criticism, some of it quite personal, all coming from the perspective that Apple’s design output, especially on the software side, has been seriously lacking for a while now.
This nuanced and careful reaction, published shortly after Dye’s departure was announced, holds up and is the thing I keep coming back to. Snell expanded on these comments on the latest episode of Upgrade with Myke Hurley. I think it is a good discussion and well worth your time. (Thanks to Jack Wellborn for suggesting I listen.)
Cast your mind back to two days earlier, when Apple said John Giannandrea was retiring. Giannandrea, coming from running search and A.I. at Google, signalled to many that Apple was taking the future of Siri seriously. For whatever reason — insufficient support from Apple, conflicting goals, reassignments to questionable projects, or any number of other things — that did not pan out. Siri today works similarly to Siri eight years ago, before he joined the company, the launch of Apple Intelligence was fumbled, and the features rolled out so far do not feel like Apple products. Maybe none of this was the fault of Giannandrea, yet all of it was his responsibility.
It is difficult to know from the outside what impact Giannandrea’s retirement will have for the future of Siri or Apple Intelligence. Similarly, two days after that was announced, Dye said he was leaving, too, and Apple promoted Stephen Lemay to replace him, at least temporarily. From everything I have seen, people within Apple seem to love this promotion. However, it would be wrong to think Lemay is swooping in to save the day, both because that is an immense amount of pressure to put on someone who is probably already feeling it, and because the conditions that resulted in my least favourite design choices surely had agreement from plenty of other people at Apple.
While I am excited for the potential of a change in direction, I do not think this singlehandedly validates the perception of declining competence in Apple’s software design. It was Dye’s responsibility, to be sure, but it was not necessarily his fault. I do not mean that as an excuse, though I wish I did. The taste of those in charge undoubtably shapes what is produced across the company. And, despite a tumultuous week at the top of Apple’s org chart, many of those people remain in charge. To Snell’s point of not personalizing things, and in the absence of a single mention of “design” on its leadership page, the current direction of Apple’s software should be thought of as a team effort. Whether one person should be granted the authority to transform the taste of the company’s leadership into a coherent, delightful, and usable visual language is a good question. Regardless, it will be their responsibility even if it is not their fault.
On November 20th American statisticians released the results of a survey. Buried in the data is a trend with implications for trillions of dollars of spending. Researchers at the Census Bureau ask firms if they have used artificial intelligence “in producing goods and services” in the past two weeks. Recently, we estimate, the employment-weighted share of Americans using AI at work has fallen by a percentage point, and now sits at 11% (see chart 1). Adoption has fallen sharply at the largest businesses, those employing over 250 people. Three years into the generative-AI wave, demand for the technology looks surprisingly flimsy.
[…]
Even unofficial surveys point to stagnating corporate adoption. Jon Hartley of Stanford University and colleagues found that in September 37% of Americans used generative AI at work, down from 46% in June. A tracker by Alex Bick of the Federal Reserve Bank of St Louis and colleagues revealed that, in August 2024, 12.1% of working-age adults used generative AI every day at work. A year later 12.6% did. Ramp, a fintech firm, finds that in early 2025 AI use soared at American firms to 40%, before levelling off. The growth in adoption really does seem to be slowing.
I am skeptical of the metrics used by the Economist to produce this summary, in part because they are all over the place, and also because they are mostly surveys. I am not sure people always know they are using a generative A.I. product, especially when those features are increasingly just part of the modern office software stack.
While the Economist has an unfortunate allergy to linking to its sources, I wanted to track them down because a fuller context is sometimes more revealing. I believe the U.S. Census data is the Business Trends and Outlook Survey though I am not certain because its charts are just plain, non-interactive images. In any case, it is the Economist’s own estimate of falling — not stalling — adoption by workers, not an estimate produced by the Census Bureau, which is curious given two of its other sources indicate more of a plateau instead of a decline.
The Hartley, et al. survey is available here and contains some fascinating results other than the specific figures highlighted by the Economist — in particular, that the construction industry has the fourth-highest adoption of generative A.I., that Gemini is shown in Figure 9 as more popular than ChatGPT even though the text on page 7 indicates the opposite, and that the word “Microsoft” does not appear once in the entire document. I have some admittedly uninformed and amateur questions about its validity. At any rate, this is the only source the Economist cites which indicates a decline.
The data point attributed to the tracker operated by the Federal Reserve Bank of St. Louis is curious. The Economist notes “in August 2024, 12.1% of working-age adults used generative A.I. every day at work. A year later 12.6% did”, but I am looking at the dashboard right now, and it says the share using generative A.I. daily at work is 13.8%, not 12.6%. In the same time period, the share of people using it “at least once last week” jumped from 36.1% to 46.9%. I have no idea where that 12.6% number came from.
Finally, Ramp’s data is easy enough to find. Again, I have to wonder about the Economist’s selective presentation. If you switch the chart from an overall view to a sector-based view, you can see adoption of paid subscriptions has more than doubled in many industries compared to October last year. This is true even in “accommodation and food services”, where I have to imagine use cases are few and far between.
After finding the actual source of the Economist’s data, it has left me skeptical of the premise of this article. However, plateauing interest — at least for now — makes sense to me on a gut level. There is a ceiling to work one can entrust to interns or entry-level employees, and that is approximately similar for many of today’s A.I. tools. There are also sector-level limits. Consider Ramp’s data showing high adoption in the tech and finance industries, with considerably less in sectors like healthcare and food services. (Curiously, Ramp says only 29% of the U.S. construction industry has a subscription to generative A.I. products, while Hartley, et al. says over 40% of the construction industry is using it.)
I commend any attempt to figure out how useful generative A.I. is in the real world. One of the problems with this industry right now is that its biggest purveyors are not public companies and, therefore, have fewer disclosure requirements. Like any company, they are incentivized to inflate their importance, but we have little understanding of how much they are exaggerating. If you want to hear some corporate gibberish, OpenAI interviewed executives at companies like Philips and Scania about their use of ChatGPT, but I do not know what I gleaned from either interview — something about experimentation and vague stuff about people being excited to use it, I suppose. It is not very compelling to me. I am not in the C-suite, though.
The biggest public A.I. firm is arguably Microsoft. It has rolled out Copilot to Windows and Office users around the world. Again, however, its press releases leave much to be desired. Levi Strauss employees, Microsoft says, “report the devices and operating system have led to significant improvements in speed, reliability and data handling, with features like the Copilot key helping reduce the time employees spend searching and free up more time for creating”. Sure. In another case study, Microsoft and Pantone brag about the integration of a colour palette generator that you can use with words instead of your eyes.
Microsoft has every incentive to pretend Copilot is a revolutionary technology. For people actually doing the work, however, its ever-nagging presence might be one of many nuisances getting in the way of the job that person actually knows how to do. A few months ago, the company replaced the familiar Office portal with a Copilot prompt box. It is still little more than a thing I need to bypass to get to my work.
All the stats and apparent enthusiasm about A.I. in the workplace are, as far as I can tell, a giant mess. A problem with this technology is that the ways in which it is revolutionary are often not very useful, its practical application in a work context is a mixed bag that depends on industry and role, and its hype encourages otherwise respectable organizations to suggest their proximity to its promised future.
The Economist being what it is, much of this article revolves around the insufficiently realized efficiency and productivity gains, and that is certainly something for business-minded people to think about. But there are more fundamental issues with generative A.I. to struggle with. It is a technology built on a shaky foundation. It shrinks the already-scant field of entry-level jobs. Its results are unpredictable and can validate harm. The list goes on, yet it is being loudly inserted into our SaaS-dominated world as a top-down mandate.
It turns out A.I. is not magic dust you can sprinkle on a workforce to double their productivity. CEOs might be thrilled by having all their email summarized, but the rest of us do not need that. We need things like better balance of work and real life, good benefits, and adequate compensation. Those are things a team leader cannot buy with a $25-per-month-per-seat ChatGPT business license.
You have seen Moraine Lake. Maybe it was on a postcard or in a travel brochure, or it was on Reddit, or in Windows Vista, or as part of a “Best of California” demo on Apple’s website. Perhaps you were doing laundry in Lucerne. But I am sure you have seen it somewhere.
Moraine Lake is not in California — or Switzerland, for that matter. It is right here in Alberta, between Banff and Lake Louise, and I have been lucky enough to visit many times. One time I was particularly lucky, in a way I only knew in hindsight. I am not sure the confluence of events occurring in October 2019 is likely to be repeated for me.
In 2019, the road up to the lake would be open to the public from May until about mid-October, though the closing day would depend on when it was safe to travel. This is one reason why so many pictures of it have only the faintest hint of snow capping the mountains behind — it is only really accessible in summer.
I am not sure why we decided to head up to Lake Louise and Moraine Lake that Saturday. Perhaps it was just an excuse to get out of the house. It was just a few days before the road was shut for the season.
We visited Lake Louise first and it was, you know, just fine. Then we headed to Moraine.
Walking from the car to the lakeshore, we could see its surface was that familiar blue-turquoise, but it was entirely frozen. I took a few images from the shore. Then we realized we could just walk on it, as did the handful of other people who were there. This is one of several photos I took from the surface of the lake, the glassy ice reflecting that famous mountain range in the background.
I am not sure I would be able to capture a similar image today. Banff and Lake Louise have received more visitors than ever in recent years, to the extent private vehicles are no longer allowed to travel up to Moraine Lake. A shuttle bus is now required. The lake also does not reliably freeze at an accessible time and, when it does, it can be covered in snow or the water line may have receded. I am not arguing this is an impossible image to create going forward. I just do not think I am likely to see it this way again.