Meta Pressures Canadian Government to Modify or Lift Online News Act ⇥ politico.com

Here is an interesting tidbit from Politico’s Canada Playbook newsletter. Nick Taylor-Vaisey, Mike Blanchfield, and Mickey Djuric:

Meta says it hopes to restore news on Facebook and Instagram in Canada by year’s end, Rachel Curran, director of public policy at Meta Canada, told Playbook. She said it will “very likely” be resolved through Canada-U.S. trade talks. “If we are able to reach agreement post-midterms — and it sounds like there’s activity in that direction — the news stuff will be dealt with as part of that,” she said.

I can see no way Meta will start permitting news links again in Canada if it has to pay for them. I anticipate, therefore, that this means it thinks the Canadian government will heavily modify or, more likely, rescind the Online News Act, just as it did the Digital Services Tax last year. Telling Politico seems like a pressure tactic.

Safari 27.3 Adds Support for Global Privacy Control ⇥ developer.apple.com

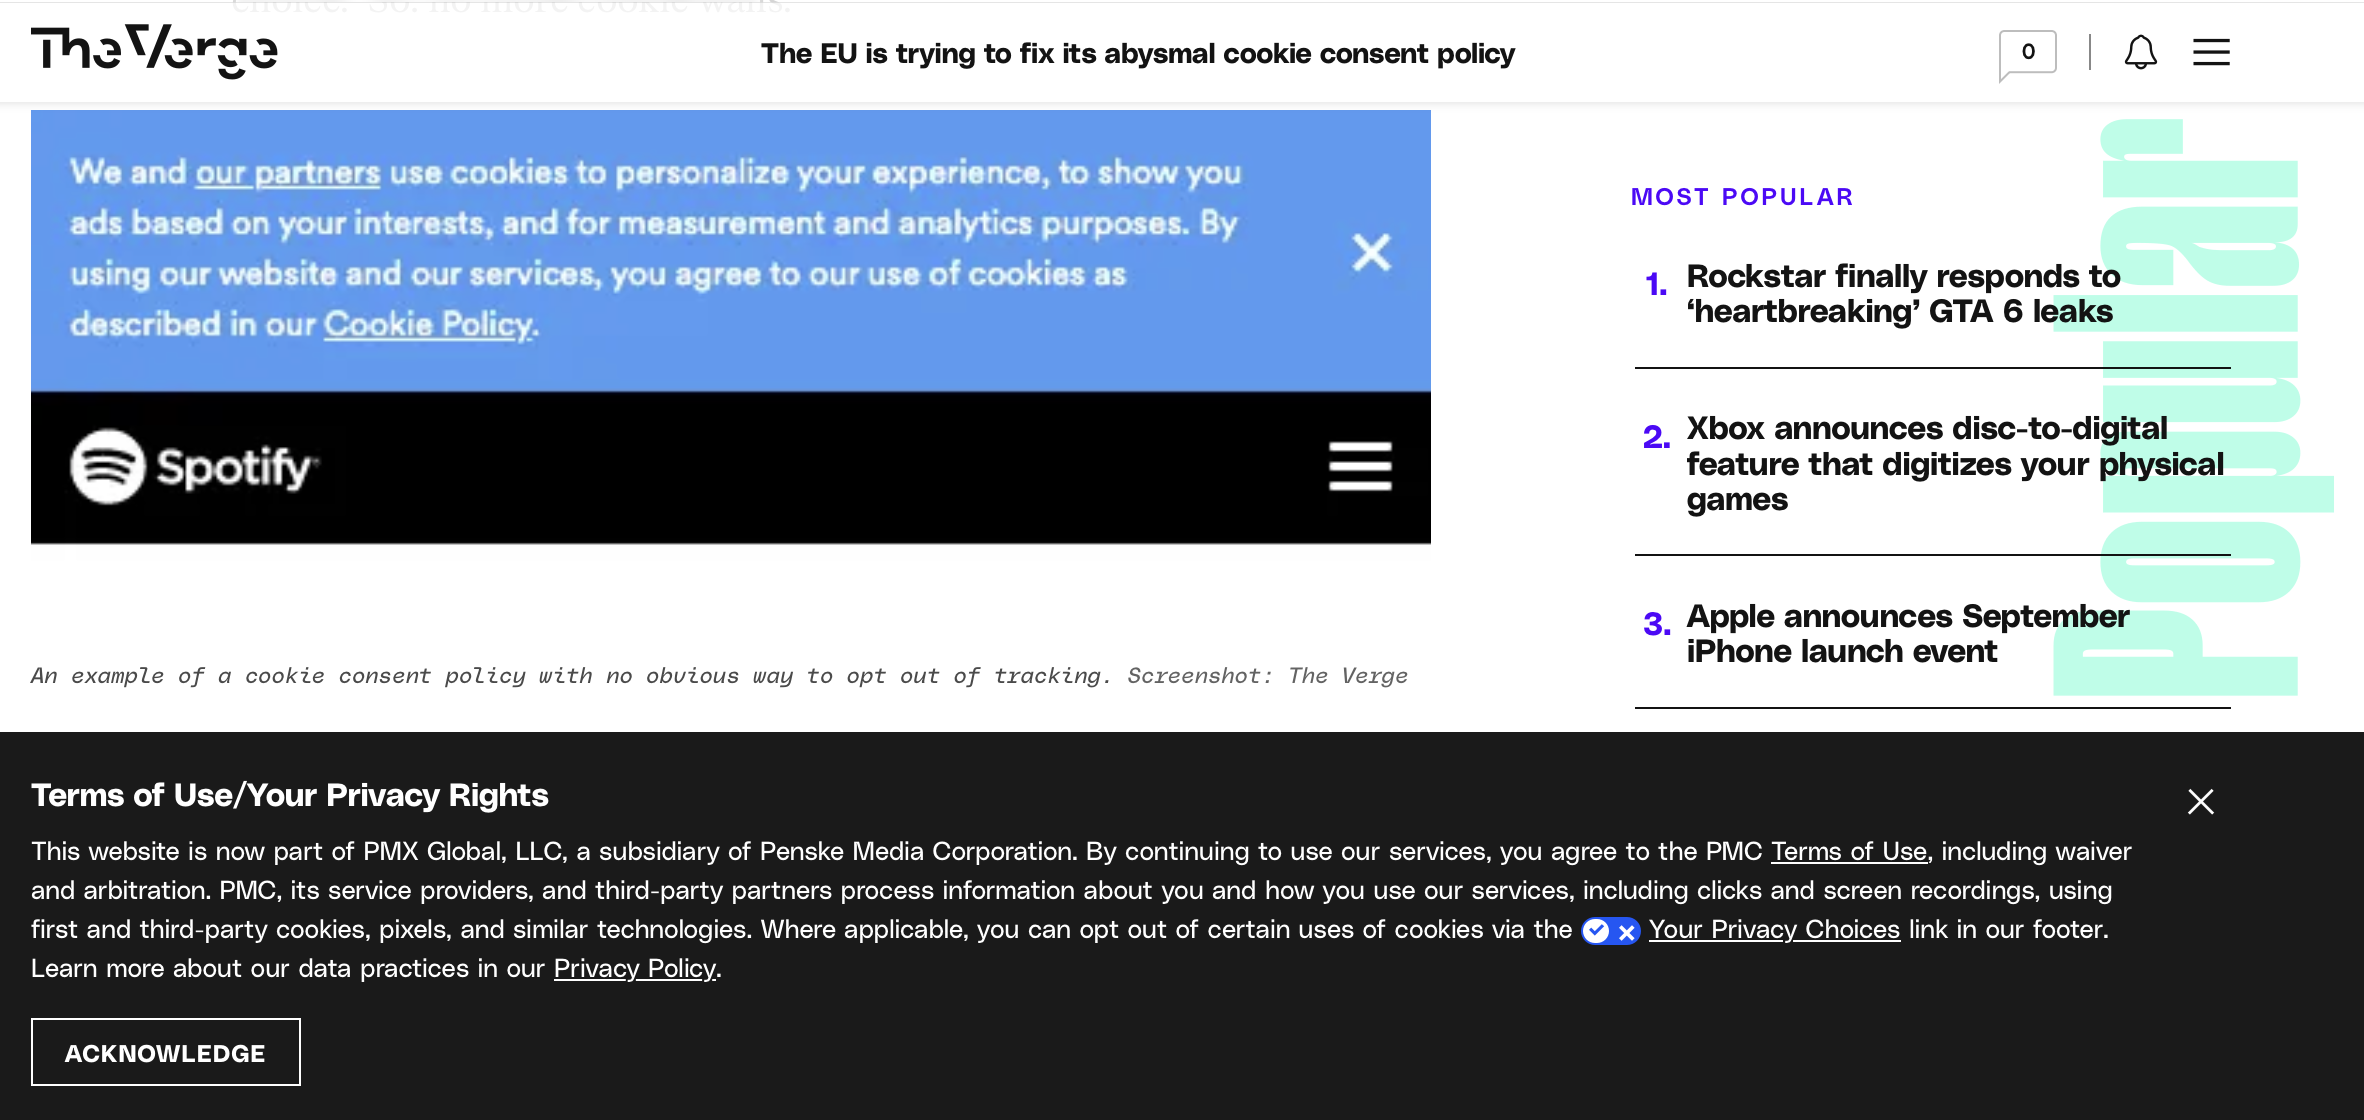
There are a whole bunch of features and fixes coming to Safari with Apple’s OS 27.3 update. One that is not in the beta release notes but appears nevertheless is support for Global Privacy Control. This new standard is effectively a replacement for Do Not Track with legal muscle that should permit you to indicate your tracking preference one time and then, theoretically, never again see a cookie consent banner.

In practice, it will take time for websites to add support, and it requires users to enable the feature in Safari’s Settings. I do not love the implementation in the first beta, which buries the checkbox in the Advanced tab with the ambiguous label “Use Global Privacy Control”, unlike the company’s proprietary anti-tracking features that live in the Privacy tab. But at least it is present and, in my testing, functional.

Public iCloud Links to Be Checked ‘For Harmful Content’ ⇥ support.apple.com

Apple, in a support article published yesterday (emphasis mine):

When you share content that’s stored in iCloud, such as a photo in iCloud Photos or a file in iCloud Drive, you can choose to Share a Link or Send a Copy of the item. If you choose Share a Link, you can either share the item with “People you choose” — only people you invite or approve — or with “Anyone with the link,” which makes it accessible to anyone who has the link, including Apple. Starting in version 27.3 or later of iOS, iPadOS, macOS, and visionOS, items shared using Anyone with the Link will be checked by Apple for harmful content.

Good.

Many years ago, in covering the iCloud CSAM detection features Apple later scrapped. In my coverage, I wrote:

Let’s apply this logic to something less heinous like copyrighted materials. If these files are merely stored in a cloud service and are not being shared to any third party, should the service provider be monitoring its systems and terminating user accounts with files matching known pirated copies? I am not sure that makes much sense.

Once these files are shared beyond the user’s personal drive, I am fully on board with scanning for legal purposes. Google Drive, for example, will allow users to store copyrighted materials but attempts to restrict sharing options if those files match valid takedown requests. Apple and Google check email attachments for child abuse materials, while Facebook scans users’ messages. That makes sense to me. As with social media companies moderating their platforms, I think there ought to be different expectations when things are broadcast to the world.

Private storage features in iCloud or any other provider’s service should be treated, legally, as an extension of internal storage since they are so tightly integrated into modern operating systems. They are not, but they should be. But when things are publicly accessible, it is fair to lose that expectation.

No word on what Apple means by “harmful content”, though I am sure you can think of the more obvious categories. It remains baffling to me why there is still no way to easily report abuse.

CBC News Updates Article About ‘Wonder Valley’ Data Centre Complex ⇥ cbc.ca

Two days ago, Eagle Andersen reported for CBC News that the Wonder Valley data centre complex — previously — would “release the equivalent of 23 atom bombs of heat waste” every day. This figure is quoted in the headline, and repeated in the first two paragraphs:

An analysis of the mammoth data centre proposed by celebrity investor Kevin O’Leary suggests it would release the equivalent of 23 atom bombs of heat waste into the boreal forest of northwestern Alberta every day.

If the Wonder Valley project goes ahead, “‘about 23 Hiroshima-sized atomic bombs worth of energy every single day will get dumped into that landscape,” said Utah State University physicist Robert Davies.

If you are steeped in the world of data centre media coverage, you might recognize this comparison. Dan Robinson, writing for the Register in May:

A proposed mega-scale datacenter in the US state of Utah has caused controversy after a physics professor estimated that the facility and its associated power generation could dump 23 atomic bombs’ worth of energy per day. But the real question is whether it will actually ever get built.

Take a wild guess which physics professor made that estimate.

It is not a surprising repetition as the projects in Alberta and Utah are quite similar. Not only are both backed and promoted by Kevin O’Leary, they are being jointly marketed as 7.5 gigawatt twins. But a comparison to one of the most extraordinary acts of war ever committed is hardly meaningful except — as it was in this case — as a made-for-headlines quote.

The editors at CBC News clearly thought this was too much, and substantially revised the article. It now carries a more responsible headline — “Physicist warns proposed data centre would generate ‘large, if not extreme’ heat waste” — and carries an editor’s note and correction:

This story and its headline have been updated to provide further context about the preliminary nature of Robert Davies’ assessment and align with our journalistic standards and practices. An earlier version of this story also said that at full operation, the project would release around 18 gigawatts of heat a day, according to Davies. In fact, Davies said the project would consume energy at a continuous rate of 18 gigawatts, or about 1.5 petajoules per day.

The differences between the versions are remarkable. The new one contains far more caveats, including an acknowledgement from Davies that “of course, that’s not explosions”, and that the numbers in his report are “a first-order estimate intended to convey scale”.

I am curious how Davies arrived at an energy consumption figure of 18 gigawatts, though. Not only is that more than double what the project’s website claims, it is over 60% more electricity than is currently being generated in Alberta, and around 77% of the total capacity of our entire grid.

While I still doubt this project is much more than a self-promotional effort by an opportunistic and loudmouthed investor, and the environmental impact of data centres like these must be a greater priority than it currently seems to be, I am glad editors were able to put this professor’s figures in their fuller context. A comparison to a bomb is not especially helpful because the difference between heat emitted slowly and heat emitted instantly is not slight. But because the loud and pervasive marketing of A.I. boosters is something news outlets feel compelled to cover in a fair and balanced way, I understand fighting their fire with fire.

The Adult Children Cleaning Up Their Parents’ Feeds ⇥ nymag.com

Jessica Lucas, in a fascinating New York magazine article about older people succumbing to compulsive social media use, and the adult children who are trying to stabilize their feeds:

Most adult children seem to know instinctively that their parents’ social-media use has long since outstripped whatever cognitive good it once served. They have watched their parents surrender ever-larger portions of their lives to their phones, triggering a kind of grief and, occasionally, anger. Every hour handed over to the feed can feel like a choice on their parents’ part to willingly accelerate their own deterioration. Anne, a 55-year-old writer living in New York, regularly travels out of state to visit her mother, Rosa, who is in her 80s. She often arrives to an unsettling scene: Rosa on the couch, “hunched over” her phone, “slack-jawed.” Over the years, Anne says she has watched her mother abandon crossword puzzles, newspapers, and books in favor of the feed. “I don’t think a younger version of her would have recognized that behavior as something she had as a goal for herself later in life,” she tells me.

Lucas also describes a kind of A.I.-generated video genre that preys on seniors; these videos are everywhere. If I am not signed into my YouTube Premium account, I often see ads from some company named Oathill Media with A.I.-generated seniors extolling the benefits of cheap life insurance. I cannot imagine this is wholly legitimate, and I know people who have been tricked by similar videos.

More broadly, this is one reason I think age-based regulations are insufficient. We should expect more from the giant corporations that make their money from, apparently, building compelling venues for advertisers. That should not be solely because Google and Meta collect an enormous amount of data to enable targeting. The platforms they manage are not actually safe; they are just popular. And, with descriptions like those in this article, it seems difficult to argue even the most frequent users are actually enjoying themselves without further intervention.

Colossus is Silicon Valley’s Investor-Backed ‘In-Flight Magazine’ ⇥ sfstandard.com

In September, I linked to a lengthy profile of Mark Zuckerberg written by Jeremy Stern in Colossus. It was a useful complement to Meta’s Connect presentation. But I had not heard of Colossus before then, and I wish I had done more digging into how what seemed to be a small publication was granted such generous access.

Andrew Fedorov, the San Francisco Standard:

Colossus is the brainchild of Patrick O’Shaughnessy, a Connecticut-raised heir to an oil fortune, who went to work for his father James’ firm, O’Shaughnessy Asset Management, in 2007. Patrick took over the company in 2018 and sold it four years later to Franklin Templeton. In 2016, he launched a podcast called “Invest Like the Best,” borrowing the title of a book his father published in 1994.

Well, that makes sense. This is yet another venue where, after mainstream media outlets and even tech-focused publications recognized a more skeptical tone toward the industry, CEOs and executives can appear to deliver their talking points with little pushback. It is in the same vein as Cheeky Pint and Alex Heath’s Sources, except there is a serious-looking print copy you can order to leave in waiting rooms and on shelves around the office.

‘No One Paid Me to Disagree With Jonathan Haidt’ ⇥ made-not-found-by-danah-boyd.ghost.io

danah boyd, like Andrew Gelman and Candice Odgers, says she was not paid by Meta or anyone else to disagree with Jonathan Haidt’s conclusions about social media:

What kills me in the contemporary teens-and-tech debate is that there’s no space for actual research or critical nuance. You’re either opposed to the tech companies or in their pockets. And this week’s absurd discovery reinforces this infuriating polarity, painting those of us who are critical of Jonathan Haidt as being corporate shills. I find this especially frustrating because I did work in tech for a lot of my career. I played the role of friction inside many companies (although never Meta). I repeatedly got threatened by tech executives for challenging corporate mantras or providing research that contradicted their interests – and yet I persisted. Cuz many tech companies are far more complicated than people realize.

I had been meaning to link to a piece by Mizuko Ito, writing in the MIT Press Reader, for weeks; I think it complements boyd’s perspective:

We can advocate for features and policies that make platforms better for learning, belonging, and wellbeing. When parents and teens are asked, they want to keep using social media with more ways to flexibly protect their privacy, control recommendation algorithms, and monitor their own technology use. The emphasis on bans has come at the cost of progress on platform policies and features that make the online world better for people of all ages. These include privacy legislation and efforts centered on children’s digital rights and the duty of care.

You do not need to be paid by Meta — or Snap, or TikTok — to find Haidt’s conclusions unconvincing or unhelpful. But because some of its executives discussed following the same playbook as big companies in other controversial industries, like agribusiness, fossil fuels, and tobacco, in swaying research to be more favourable, the well has been poisoned. The people most visibly criticizing Haidt’s work insist they came to their conclusions entirely independently. I believe them. After those meeeting notes became public, however, I would not be surprised if many people do not.

Eternal Black October ⇥ todayintabs.com

Rusty Foster, of the excellent Today in Tabs newsletter you should probably be reading:

Neat! There’s a remote-exploitable kernel memory race condition in the Linux IPv4 TCP code. A bunch of other linux kernel vulnerabilities were accidentally posted to a public mailing list before patches were ready for them. The official Claude Code extension for VS Code on Cursor has been dropping “a persistent SSH backdoor across macOS, Linux, and Windows.” The Department of Homeland Security was hacked. Fanfiction site AO3 was hacked. Polymarket was hacked. Binance was hacked. I’ve been writing for about an hour now so chances are very good that several more things have been hacked that I don’t know about yet.

Any of these would probably have been the worst computer security incident in any average month in the last 25 years. But this is not even a complete list, it’s just a haphazard roundup of what came across my feeds. In fact, if you have any professional contact with tech, you’ll have noticed that I didn’t even mention the worst one yet.

The security incidents listed above — plus the foreshadowed PHP2Shell one — all have different explanations. The Binance theft, for example, appears to have been the fault of a uniquely criminal nation state, while several vulnerabilities have either been found or surfaced and made operational with the use of artificial intelligence tools. Even so, this feels less like a coincidence and more like a preview of the next several years in ebbs and flows.

North Korea Gets Away With $3 Billion From Binance ⇥ citationneeded.news

Molly White, writing at Citation Needed:

A notorious North Korean cybercrime group has stolen around $6.4 billion in cryptoassets from multiple hot wallets belonging to Binance, the world’s largest cryptocurrency exchange, and still controls around $3 billion of it after stablecoin issuers and other protocols froze what they could. These estimates are still in flux as various platforms work to freeze tokens or otherwise thwart the attacker from cashing out, and as both Binance and independent security researchers continue their investigations.

Alex Hern on Bluesky:

No way to prevent this, says only financial sector where this regularly happens.

The currency of the future is vulnerable to, apparently, “a compromised DevOps engineer’s laptop”.

Meta Executives Met to ‘Get the Academic Community to Disavow’ Jonathan Haidt ⇥ cailinoconnor.substack.com

Cailin O’Connor, professor at the University of California Irvine:

Yesterday saw reporting on new, internal Meta documents released through the ongoing lawsuit. Meta had been using a favored industry strategy of including their attorneys on any risky internal correspondence so that this correspondence would be protected by attorney-client privilege. The judge called bullshit.

The resulting documents reveal:

  1. Explicit plans by Meta to discredit psychologist Jonathan Haidt, who has been raising alarms about social media and youth mental health.

Candice Odgers, also a professor at the University of California Irvine:

This is why I cannot believe that I have to write this post. Today the London Times wrote an article lazily suggesting that I, and others, were paid by Meta to critique the arguments made by Jonathon Haidt in the Anxious Generation.

So let me say this next part very clearly. I have never been approached by Meta to shape what I say publicly about the research on adolescents and social media. My views are my own, and are grounded in the years of research I’ve done on this topic.

I could not see anything in the unsealed notes (PDF) directly referencing Odgers, nor does the Times article actually claim Meta paid her. It does, however, create the implication that her disputes with Haidt’s book are suspicious by tying them to those meeting notes.

Two things can be true, though. Meta could have attempted to sway opinion among academics and media — one executive hoped they could “get Gellman to write a take-down piece”, referring presumably to Andrew Gelman, who says he has “never been contacted by anyone at Facebook or Meta regarding Jonathan Haidt or his work”. Even if Meta is not getting positive coverage from this “whisper campaign”, the public knowledge of it will poison the waters of this debate. That is unfortunate because of the second thing that can be true: Haidt’s research might not be as solid as he and others believe. But good luck having that conversation now.

Reddit Is Further Locking Itself Down ⇥ axios.com

Reddit administrator “judy-funnie” (via Michael Tsai):

Because RSS is now a common surface for large-scale scraping and automated abuse, we’ll stop supporting RSS feeds on November 13, 2026 while preserving moderation workflows that depend on it through supported alternatives.

[…]

To close this gap, in the next few months, we’ll further limit access for logged-in users to only those who have used Old Reddit in the last six months (which covers the vast majority of all Old Reddit users). […]

Old Reddit is a lightweight website that generally respects its users, so it is a priority for people to switch to its bloated replacement. Not for users, of course, but for someone.

Reddit administrator “boat-botany”:

We’re sharing the timeline for moving public API apps and bots to the Developer Platform. Register now, apply for migration funding by November 30, and start planning and testing your move. Starting January 12, 2027, we’ll begin removing API access for apps and users that haven’t registered or engaged with us. Remaining public API access will end in March 2027.

Sara Fischer, Axios:

Reddit has long championed the open web. Now, it’s pushing to build a more direct relationship with users while also protecting its data from increased scraping in the AI era.

In an interview Thursday, Reddit co-founder and CEO Steve Huffman said the company is making the change to improve its user experience, bolster its ads business and prevent bots from scraping its proprietary data.

Two of those three reasons seem believable.

There was once a time when we could use a relatively inexpensive computer to connect to the web and freely read discussion boards. It feels almost quaint now that A.I. “hyperscaler” companies have scraped everything they could access on the web, and with — as near as makes no difference — unlimited funding, bought a bunch of graphics processors and memory. Now the price of every kind of computer hardware has gone up, and companies like Reddit are trying to control access. This is not because Reddit respects users’ unique contributions, nor will it compensate them. It is just not making enough money for shareholders.

Huffman blames declining Google search traffic — a disappointingly familiar story. It is an extraordinary coup. The web’s most important referral source built up a vast data set and then yanked away the entire reason everyone contributed to it. “Evil” is four-letter euphemism.

A Further Status Update on the Toaster-Refrigerator Project ⇥ apple.com

Joanna Stern, reporting for ABC News in 2012:

And it was on that last point that Cook had a lot to say. When asked if Apple was planning to merge its tablet and laptop products, much as Microsoft is proceeding with Windows 8, Cook responded with a quip: “You can converge a toaster and a refrigerator, but those aren’t going to be pleasing to the user.”

Cook elaborated that converging the iPad with a laptop would result in tradeoffs, ones Apple isn’t willing to make. “We are not going to that party, but others might from a defensive point of view.”

Apple, today:

Apple today introduced the all-new MacBook Pro with PROLED XDR Display, featuring breakthrough tandem OLED technology that delivers game-changing front-of-screen performance. Available in 14- and 16-inch models, MacBook Pro with PROLED XDR Display offers a visual experience unlike any other, transforming pro workflows with up to 2000 nits peak HDR and SDR brightness, an industry-leading 10,000,000:1 contrast ratio for exceptional detail, a 120Hz variable refresh rate, and a wider colour gamut covering both P3 and Adobe RGB for brilliant colours. The new MacBook Pro also introduces intuitive Touch capabilities on the Mac for the first time, opening up a whole new dimension for pros to interact with their content, from manipulating 3D models to playing musical instruments onscreen. […]

One might point out, as they watch the Apple Developer videos about these touch features, that Apple is not in fact delivering the toaster-refrigerator hybrid of doom. MacOS looks mostly the same; even though touch targets in parts of the U.I. are larger, most controls remain the same visual size. When needed, MacOS gives more room, like if you use a finger to show a menu instead of a pointing device. This is merely about bringing touch as an optional interaction element to the Mac. And just look at the quote above: Apple does not even mention touch features — sorry, “Touch capabilities”, with a capital T — until the third sentence. If anything, this is a MacBook Pro with a nicer display that happens to support touch.

But Apple is still asking people to pay more for it than the standard model, though not by as much as it might first appear. While the M6 MacBook Pro starts at $2,000 USD, the touch ones have an M5 Pro chip. Thus, the equivalent non-touch models start at $2,500 USD, and the touch ones at $2,900 USD. For that $400, you get an ostensibly nicer screen that supports touch input and has a Dynamic Island instead of a notch, and a lighter and thinner chassis.1

What you do not get, though, is a true hybrid of an iPad and a Mac. The display does not fold back to create a tablet, for example, and it does not support Apple Pencil input. Yet. Apple also has not managed to reinforce the human arm or fix the ergonomic issues it has repeatedly identified when it was not selling a Mac with a touch screen. This is evidenced by the section of the developer video suggesting that developers should place denser and finer-grained controls around the edges of the screen where users can support their hand with the metal frame.

Maybe I am just showing my age.


  1. If component prices were not what they are, I wonder if these MacBook Pros would have been introduced as a replacement for the existing M5 Pro and M5 Max models, perhaps with a smaller price increase. ↥︎

Rest of World Faces Prospect of Shutting Down ⇥ semafor.com

Maxwell Tani, Semafor:

The globally-minded tech news startup Rest of World is scrambling to find a new home — or faces the prospect of shutting down.

The six-year-old digital publication has seen the social and web search traffic on which it depends evaporate. This sharp decline has prompted the organization’s founder and primary financial backer, Sophie Schmidt, to explore other options for its future.

This is disappointing. Rest of World is one of my favourite publications with a scope unlike anything else. It is essential reading.

Schmidt is the daughter of former Google executive Eric Schmidt who I just happened to read, owns one percent of Anthropic which will surely grow his already ungodly fortune when the company begins trading publicly in the coming weeks. While Rest of World is not a family affair, that windfall alone could probably run the publication — already largely funded by the Schmidt Family Foundation — for years, enough to buy it some time to figure out how to survive as typical referral sources become more insular. But that is apparently not happening — a huge loss.

The Annoying Implementation of Translation in Safari ⇥ lapcatsoftware.com

Jeff Johnson:

The Safari web browser has a longstanding annoying misfeature: it announces “Reader Available” and “Translation Available” in the address bar, whether you like it or not, with no way I know of to stop that madness. This behavior is bad on Mac, worse on iPhone. Below is a screen recording of Safari on Mac.

Yes, and it gets worse. The worst part of this behaviour is, for me, the translation icon in Safari on MacOS. When “Translation Available” is displayed, the icon is grey and positioned on the lefthand side of the address bar, but if you click on it, you will see the website settings menu. Instead, you have to wait until the animation is complete, at which point the icon will appear on the opposite side of the address bar — still grey, though! — at which point it becomes active.

Utter madness.

Apple Finds Some Personality ⇥ wallpaper.com

Jason Snell, Six Colors:

Every five years when we hit an anniversary, I struggle to recontextualize the iPod. But this year, for the 25th anniversary, I’ve been thinking about Apple’s little music player a lot more.

Stephen Hackett:

This link — which you gotta manually open in your browser — is the best thing I’ve seen on the Internet in a long time.

This looks enough like my own iPod library circa twenty years ago that it threw me a little. I hope this is not appearing solely for the occasion of the iPod’s anniversary. It is a nice surprise.

Charlotte Gunn, Wallpaper:

Apple Music has enlisted British producer Fred Again.. to help turn sound into something tangible for its new visual identity. Built around the idea of being ‘made by sound’, the redesign takes an experimental approach, using musical frequencies to create rippling, liquid forms. The results were achieved by playing music into a shallow bath of mineral oil and filming the resulting vibrations.

There is a corresponding video illustrating the process alongside the mnemonic created by Mr. Again. While I am not sold on the six-note sequence — it sounds to my ears somehow both cramped and unsatisfied — it is a very cool visual effect. Apple is justifiably proud of what it has created; it is showcasing a version of the icon in its social media profile pictures.1

So why, then, does the updated icon in iOS 27.2 look nothing like that?

Apple employs plenty of creative people doing interesting and exciting work. I think the Apple Music rebrand is fantastic, and the iPod Easter egg shows a little personality from a largely sanitized company. A music app should display some kind of verve for life. Alas.


  1. Check out those low, low, low TikTok view counts, too. ↥︎

A.I. Has Made It Easy to Brute Force the Internet ⇥ 404media.co

Jason Koebler, 404 Media:

To give you a sense of what I’m seeing, Matthew Green, a Johns Hopkins professor and one of the most respected cryptographers in the world, posted “we’re in the part of the movie where you need to throw whatever you can in the path of the zombies and hope it slows them down,” and “so many people discovering that the whole Internet is dry tinder and the only thing keeping it from burning is the fact that teenagers haven’t found the matches yet,” […]

And all those posts came before people using AI-powered tools found vulnerabilities in PHP, the programming language that powers much of the internet. […]

Charlie Warzel, the Atlantic (gift link):

Once the patch was released yesterday, websites everywhere went offline to implement the fix. These included government websites in Germany and Finland, some hospital and school websites in Europe, and international sites such as 4chan. During this race to secure the majority of the internet, I noticed one name pop up in posts on Reddit and X: Ondřej Surý.

There are likely to be many more weeks like this one which, in the best case, leaves us with more secure digital infrastructure and better practices for the future. But it is going to be an uncomfortable ride to get there and, as usual, much of the hard work will be done by volunteers with little financial support or credit.

Anyway, I still think PHP is pretty great.

Australia Becomes Latest Region to Require More Competitive iOS App Distribution ⇥ ia.acs.org.au

Tom Williams, Information Age:

Apple has been ordered to open its “walled garden” to allow third-party app stores and alternative in-app payment systems in Australia, in a landmark court decision which the technology giant says it will appeal.

Apple has until at least March 2027 to allow Australian users to download apps through alternative app stores, including direct web downloads, Federal Court Justice Jonathan Beach ruled on Thursday.

Lex Friedman:

Apple is building third-party app store support country by country, under protest, with a different set of rules in each place, and appealing every ruling along the way. They are frustrating developers, and in some cases users, and in many places — governments. This is the most expensive and painful way possible for Apple to support these stores that it seems it will inevitably need to support in more and more places.

It seems unsustainable to keep dripping out rule changes one country at a time, especially as many of them slightly differ in the details even when regulators’ overarching aims are similar. The reasons for the company’s stubbornness — namely: security and privacy — become much less believable as a growing number of regions require alternative distribution channels, essentially without issue.

Apple should just rip off the bandage and do Gatekeeper for iOS.

PHP Warns Admins to Expect Emergency Patches Tomorrow ⇥ bleepingcomputer.com

Lawrence Abrams, Bleeping Computer:

In an advisory published Tuesday, the PHP development team announced that it plans to release security updates on Wednesday, October 21, at 14:00 UTC (10:00 AM Eastern), to address two vulnerabilities, each rated 9.2 under CVSS v4.0.

The PHP security team also sent a notice to its ANNOUNCE mailing list, urging administrators to prepare to install the security updates as soon as they become available.

Word on the street is that these exploits have leaked, and that remote code can likely be executed all the way back to PHP 5. If you have access to your website’s php.ini file, it might be worth turning off multipart uploads for now.

NetNewsWire 7.2 ⇥ netnewswire.blog

Brent Simmons:

We’ve released NetNewsWire 7.2 for Mac with a new column view layout: choose View > Use Column Layout to switch. (Choose it again to switch back.)

This is a new feature in the sense that the previous version of the app didn’t have it — but NetNewsWire of Yore, before the 2018 reboot, certainly had this feature. Even NetNewsWire 1.0 had this feature! In fact, back in those days it was the only layout. In some ways this is the oldest NetNewsWire feature and we’re celebrating its triumphant return. :)

I have been using this view since it appeared in the beta last month and I am a huge fan. It feels like coming home. (Though, I have to say: I recognize there is a history to the name “Column View”, but it is strange to me that the layout more typical of modern apps is reminiscent of what Finder calls the “Column View”. This one is more like a row-based view in my 2026 head.)

The iOS version of NetNewsWire 7.2 adds iPhone Duo support.

What Is the Truth? ⇥ lrb.co.uk

Geoff Mann, London Review of Books:

The dubious achievement of prediction markets is to have found a new way to exacerbate and exploit the simultaneously frantic and passive experience of the world that is a defining aspect of our age. Like any kind of gambling, they are enervating. We put our money down and then (unless we are using a hairdryer on an airport thermometer) fidget anxiously till it’s over. The world happens to us. This passivity is characteristic of the politics of those who think we are stuck with the world we have. The best we can do is make money while events wash over us: ‘Don’t blame me. I didn’t start the war, I just bet on it.’ Such people may think they are ‘courageous’ or ‘gutsy’ because they take ‘risks’ (this is the way people in the financial sector have always talked), but the whole charade is a profitable supplication to, even a cowering before, the power of ‘the markets’. To put the case more gently, the appeal of ‘risk-taking’ just now, especially but not only to young men, may be an indicator of how little control many people feel they have over their own slice of the world, and of the feeling that they can’t shape their lives in a meaningful way. Marking time through a series of ‘settlements’ and ‘closes’, hoping for a windfall, may look like the best way to buffer oneself against an uncertain future.

The “hairdryer on an airport thermometer” phrase is a reference to a story I had not heard before about a temperature sensor at Charles de Gaulle Airport. It is dumb as hell in the best and worst ways you can imagine.

The only way users of Kalshi and Polymarket are predicting anything is if they have either knowledge of — or control over — an outcome. We recently had a by-election in Alberta. Kalshi members bet with 99% odds that one candidate would win — right up until the votes began to be tabulated. Betting on nigh everything is treacherous, and claiming it is not gambling but “prediction” markets is laughable.

The Last Skeuomorph in iOS? ⇥ jarrettfuller.blog

Jarrett Fuller [sic]:

It’s 2026 and when I click the button on my glass phone, it makes a shutter sound! There are still skeuomorphs in iOS after all! The skeuomorphic designs of the early camera simulated a shutter closing and opening when you a took a photo but that’s long been replaced with just a subtle blink of the screen. And yet! The shutter sounds remains.

As Fuller writes, it might be the very last one. I would also make a case for the lock sound. It is not quite the padlock noise it used to be, but it definitely retains a mechanical quality that resembles what it is supposed to be.

One nitpick:

[…] (The irony is not lost on me that this new phone actually does have a physical shutter. That shutter, though, is silent. Apple is essentually simulating the shutter sound while a real shutter is actually firing.)

The new iPhone has physical aperture blades on its main camera, but I am pretty certain it, like all iPhone cameras before, continues to use an electronic rolling shutter.

Update: Via Marcin Wichary, there is lots of good discussion on Kottke, including skeuomorphic icons for apps I do not keep on my Home Screen and, thus, forgot about.

Meta Revises Its Commercial Terms of Service Again ⇥ niemanlab.org

Andrew Deck and Hanaa’ Tameez, Nieman Lab:

In its revision, published Friday afternoon, Meta removed the word “train” from a list of allowed use cases and limited those uses to “advertising and business products,” rather than all Meta products. But the revised terms will still allow for broad scraping of websites, potentially superseding robots.txt files, according to legal experts.

Meta is adamant it will not misuse these capabilities in the way these legal experts say it can. If promises are being made by a company with the kind of public respect and trust Meta has, you can take its tweeted word over its new legal permissions for all the weight that it carries.

Tech Hype Is Cannibalizing the Future ⇥ techpolicy.press

Sun-ha Hong, Tech Policy Press:

Sometimes, failures do lead to wider stigma and skepticism around the technology in question. But this does not happen anywhere near as often as the massive levels of investment and inflated promises might warrant. The distinct characteristic of tech hype of the 21st century is the overwhelming centralization of wealth, cultural prestige and, increasingly, political autonomy that is used to instill a sense of inevitability around Silicon Valley visions of the future, and a sense of learned helplessness, or even “futurelessness,” for those who would prefer another path. Mark Zuckerberg and Meta thus live to dream another day, relatively unscathed from the over $80 billion burned at the altar of the Metaverse.

This pretty well encapsulates the myth-making qualities of Elon Musk, too, particularly after yesterday’s nonsense-filled Tesla “Roadster” announcement. (About which, by the way, Jameson Dow at Electrek has a theory.)

How Targeted Ads Become a Pipeline for Zero-Click Mercenary Spyware ⇥ citizenlab.ca

Bill Marczak, et al., of the University of Toronto’s Citizen Lab:

This is the first-ever public confirmation of zero-click mercenary spyware delivered via targeted ads. We call the technique AdFection, and show how it was used to infect devices at Al Jazeera with Candiru’s spyware. We also uncover Discover-Tech, and show how the company helps mercenary surveillance vendors track and hack devices around the world.

Jillian Kestler-D’Amours, CBC News:

Citizen Lab said it was able to confirm a targeted spyware attack on Al Jazeera: At least 45 of the Qatar-based news outlet’s devices were infected with spyware via Discover-Tech’s ads in 2024 and 2025, the report said.

[…]

An Al Jazeera Media Network spokesperson told CBC News in an email that it “strongly condemns the targeting of our staff with mercenary spyware.”

This investigation is worth your time; it is disturbing. It solidified two things for me: the display advertising technology stack is a global threat, and behaviourally targeted advertising needs to be banned. Obviously, installing an ad blocker is mandatory now, and any website that relies on anti-ad blockers like Admiral does not respect you.

Meta’s New Business Terms Appear to Supersede Opt-Outs for A.I. Training on Commercial Websites ⇥ niemanlab.org

Andrew Deck and Hanaa’ Tameez, Nieman Lab:

Meta can use web scrapers to crawl and collect content from websites “associated with” business accounts on its platforms, according to its new commercial terms of use.

[…]

The new terms broadly cover business accounts that manage pages and groups, run advertisements, push marketing messages, and use the platform’s business account dashboard. As written, the new terms could be used to argue that Meta can scrape content from news sites and use that content to train the company’s AI products, according to three legal experts who reviewed the terms at Nieman Lab’s request.

Short of businesses deleting their Meta accounts, there does not appear to be a way to opt out of the new terms. This seems to me to be one way to better insulate the company from the potential consequences of fair use arguments that have mixed results in U.S. courts.

Update: Meta’s Andy Stone disputes this analysis, and says “content owners can use robots.txt flags to indicate their preferences”.

Evidence Does Not Show Decreased Russian Propaganda After Ukrainian Strikes on Yandex Data Centres ⇥ lawfaremedia.org

Renée DiResta, writing for Lawfare:

There is a real event underpinning the story, and an authentic chart showing a dramatic decline in automated internet traffic. But the leap from a viral chart to the disappearance of Russian propaganda bots is a large one. Much of the apparent corroboration comes from anecdotes about how social media feels, rather than measurements of what actually changed. And this speaks to a broader problem: as platforms have reduced access to data, and as “disinformation” has become a politically contentious term, the ability to investigate claims about online manipulation has decreased.

My concern remains that offloading responsibility for the toxicity of online spaces to foreign propaganda campaigns makes it more difficult to confront the actual problems. There is plenty of blame to go around. Russia has, as DiResta put it in a 2018 New York Times opinion column, developed an “enthusiasm for and commitment to modern information warfare”. Other countries are also using social media for propaganda and misinformation, too.

But some blame should also be apportioned to the platforms that incentivize bad actors, and those that accept no responsibility for what they promote. Of course, there are also the individual users who are hostile and abusive toward others. This is made possible in part by platforms that moderate poorly and tacitly — and, in some cases, explicitly — encourage an outrageous environment. But it is also the fault of individual users who spread lies, hate, and harm. Many of them are not foreign actors, but our neighbours right here at home.

Here’s to the Normal Ones ⇥ time.com

Time announced its roundup of what it thinks are the best inventions of 2026. Among them are John Ternus — or so it would seem — and the iPhone Duo.

Andrew R. Chow profiled Apple’s new CEO, and this excerpt has caught some eyes:

But Ternus and other Apple executives say they aren’t concerned. In the midst of a populist AI backlash, they contend that they are building a modest but personalized and privacy-preserving form of AI that will actually help ordinary people as opposed to merely dazzling Silicon Valley’s “lunatic fringe,” as Greg Joswiak, senior vice president of worldwide marketing, puts it. And besides, Ternus argues, even if other companies succeed in their mission of building super-intelligence, users will still want to talk to it on Apple devices.

I hope the “lunatic fringe” is very upset about this. Perhaps they can be so upset that refurbished Mac Studios can be restocked. Oh, please.

Joining the iPhone Duo among the “best inventions” are the Brick and Dumbphone 2, two devices that attempt to get you to put away your smartphone, and the Plaud NotePin S, another entry in the apparently booming category of A.I. note-taking products.

W Social Makes Verified Users’ Personal Details Visible on the Open Web ⇥ blog.elenarossini.com

Elena Rossini:

W Social is a European social media company that launched in Davos earlier this year, during the World Economic Forum. I have written a series of articles about them; […]

[…]

I wonder: are W Social verified users aware that their personal details (first name, last name, nationality and approx. birthday) are being shared OUTSIDE of W Social and published as a permanent record on the web, in plain text?

This has to be in violation of European privacy laws, right? No way would anyone expect their full legal name to be publicly accessible. W Social disputes this framing and has taken an aggressive posture in response.

‘A Man From the Future’ ⇥ petshopboys.co.uk

The Pet Shop Boys have a new album out:

Created in collaboration with Alan Turing biographer, Andrew Hodges, and performed by Pet Shop Boys and the Manchester Camerata Octet with narration by Juliet Stevenson, string arrangements by Sven Helbig and additional production, programming and synthesisers by Maarten Vos, the work explores eight significant chapters in the life and death of Alan Turing, the pioneering British mathematician and cryptanalyst who laid the foundations of modern computing.

There are some wonderful poetic choices across the whole record.

Elevation Lab Pulls Its AirTag Silencing Product ⇥ elevationlab.com

Not too long ago, Apple accessory company Elevation Lab released a product designed to silence the noises made by AirTags when they are out of range. That is a reasonable idea for an AirTag installed in something someone might steal. It is also a dangerous product in the hands of someone who might want to stalk or harass another person, a distressingly well-documented use of AirTags.

Elevation Lab, today:

We have removed the product and will use our patent on it to prevent anyone else from making one in the future.

This is excellent news — a necessary correction for, as the Electronic Frontier Foundation’s Eva Galperin put it, “the mindset that things are more important than people”. Kudos to Elevation Lab for doing the right thing.

Tired of Recommendation Engines ⇥ ethanmarcotte.com

Ethan Marcotte is tired of all the recommendations and suggestions in internet services. For the most part, I am, too. At the very least, I dislike how much they feel imposed or as a default, as though my use of most services should flow through the suggestions they provide.

Even calling them “suggestions” or “recommendations” feels a little bit generous for sites like YouTube — where continuous playback to an automatically selected video is on by default — or Instagram, where algorithmically selected posts can only be “snoozed” from the timeline for thirty days at a time before they are automatically re-enabled.

It should not be so difficult for me to simply look at things I want to see and, just as importantly, not see things I do not want to look at.

The Probably Fake Russian Troll Exodus ⇥ br.de

After Ukrainian forces struck several data centres belonging to Russian internet services giant Yandex, a couple of charts began circulating social media purportedly showing a decline in traffic from Russian bots. The narrative suggested — by people like political scientist Ian Bremmer, journalist Jamie Dupree, TPM’s Josh Marshall, and historian Timothy Snyder — is that these attacks silenced a noticeable number of automated troll accounts on X, particularly those promoting far-right talking points.

This does not appear to be true.

There are two charts in question. The first, as posted by Dupree and others, is sourced from Cloudflare data indicating a precipitous drop in Yandex bot traffic. But, as Jowi Morales writes at Tom’s Hardware, this does not show a reprieve from nefarious users:

Yandex is Russia’s equivalent to Google, and its Yandex Cloud service status reports that at least 84 services are currently offline. Global internet monitoring firm NetBlocks said that Yandex’s network traffic has dropped to just 30% for Yandex Cloud and 63% for Yandex LLC, most likely resulting in slower internet services or complete disruption for the average Russian. […]

Yandex operates search engine crawlers, just like Google, which are referred to as “bots”. This is, in part, what these data centre strikes took out, and the reason Cloudflare is seeing a big drop in traffic from Yandex.

The other chart is a doozy. It was popularized in an X post by Tomáš Zdechovský, a Member of the European Parliament for the Czech Republic, though its original source is unknown. It purportedly shows a massive recent decline in social media posts promoting the far-right Alternative für Deutschland party, with Zdechovský suggesting “[s]o much talk about German patriotism… then the connection from Russia goes down. 🤔🇷🇺” But the chart itself does not indicate this is AfD-related traffic at all. The title translates to “daily activity over 3 months” — but “daily activity” of what, exactly, is not defined.

Max Gilbert, of German public broadcaster Bayerischer Rundfunk, looked into the chart and found it was full of problems (this is how Safari translated the article for me):

It is striking that the graph on the 15th October ends, so a date in the future. According to #Faktenfuchs-Recherche, the graphic was first published on the 11th. Posted in October. That data is available for an already future date is obviously not possible.

[…]

Which platforms were examined here, how the variable “activity” comes about: All this remains unclear. The unknown or possibly non-existent data base as well as the inaccurate scaling and values “from the future” show that this is not a meaningful, fact-based graphic created according to statistical methods.

Tom Wannenmacher, of Austrian fact-checking site Mimikama, also published a good explanation of the two charts. And overall Russian bot traffic has not really declined recently.

Unfortunately, these charts and their narrative have been circulating widely for days and, I bet, will live on as a kind of orphaned factoid among the terminally online. It is disappointing how uncritically these charts were accepted. There are, of course, disinformation networks and state propaganda all over social media. But when we focus too much on the involvement of foreign actors and unhinged trillionaires in our dire political state, we may forget how much of it is grown right here and self-inflicted.

Satya Nadella and Marc Benioff, Toadies ⇥ cnbc.com

Greg Iacurci, CNBC

Microsoft Chairman and CEO Satya Nadella on Saturday called for advanced artificial intelligence systems to be built with containment, independent controls and an “emergency brake” that lets authorized people pause or shut a model down mid-task.

“We need to surround non-deterministic models with strong, deterministic system design, human controls, and reliable operating procedures, and establish industry standards where existing ones are insufficient,” Nadella wrote in a post on social media platform X.

What Nadella actually wrote is an essay which does not contain the word “artificial”, but instead uses the phrase “super intelligence” four times and otherwise — because it is obvious and embarrassing what he is doing — simply refers to the technology as “intelligence”.

Marc Benioff, also on X:

The era of Super Intelligence is here. AIForce is officially SIForce.

There is no legal or moral requirement to replace the vocabulary of “artificial intelligence” unless one is trying to appease a dumb and unpopular administration. Truly spineless stuff from Nadella and Benioff alike.

The People Holding Up the Internet ⇥ sheets.works

Sheets.works put together an excellent but — perhaps ironically — unbylined visualization with this simple premise:

Billions of phones run on code looked after by a handful of people. We counted them from the code itself.

I had no idea SQLite or sudo were maintained by such a small number of individuals and — like many other examples in this story — seemingly without the financial support of the companies relying on their work. Some of those are among the most valuable companies on the planet.

Next Year, YouTube Will Allow Testing Different Versions of the Same Video ⇥ youtube.com

Aparna Pappu of YouTube:

This builds on the incredible success we’ve seen with other Studio tools like A/B testing, where creators have run more than 40 million experiments to find the perfect titles and thumbnails for their videos since the feature officially launched in 2024. Coming soon, you’ll also be able to test up to three video cuts to see which hook performs best with the new video A/B testing feature.

This is a very short introduction to a potentially very transformative feature: different people will now be watching different versions of what is ostensibly the same video.

Marques Brownlee has a thoughtful video about the potential consequences and I think it is worth your time. Brownlee got to speak with some YouTube engineers about his concerns — including really basic questions like whether someone will know they are watching a video that has other versions — and they apparently had few answers. One thing they did address, though, is that this feature is apparently intended to allow slightly different variations and not wholly different videos. Some mysterious-to-everyone A.I. analysis will determine whether the variations are similar enough to permit A/B testing.

YouTube announced this feature about two weeks ago, and according to Brownlee, it will be launching next year. I am not exactly plugged into the YouTube world but this is the first I am hearing of it and, while I would like to believe YouTube will adequately communicate this closer to launch, I think most video viewers are going to find this unpleasant and surprising. If it rolls out as described now, I bet you will see a lot of confused comments under videos with people referencing something that only happened in one version.

Meta Is Restricting Some Pages to Two External Links Per Month Unless They Pay Up ⇥ pressgazette.co.uk

Meta:

Drive people directly to your website, shop or latest offer by adding a clickable link to your Instagram posts and reels. People can visit the website from your post or reel.

If you subscribe to a Meta One plan, you can add links to a set number of posts and reels each month based on your plan: […]

It seems utterly bananas to me that Meta is pitching links as a feature people need to pay for, but here we are.

Instagram has never supported links of any kind in individual posts, so that is a new feature with two links per month permitted for free, and more enabled by this pricey subscription — starting at $50 USD per month for four posts per month containing external links. But links in Reels have been commonplace for years. Meta is now gating that, too; and there is more.

Andrew Hutchinson, Social Media Today:

As outlined in the explainer, some accounts are now being limited to two link posts on Facebook per month, unless they pay for a Meta One subscription.

Charlotte Tobitt, Press Gazette:

Until now it has been unclear whether news publishers will come up against the link limit. But Press Gazette understands that news publishers are excluded – as they were from similar tests for the Meta Verified subscription (now folded into Meta One) that began at the end of last year.

However it has not been confirmed how Meta defines who falls into this category – and Press Gazette is aware of small publishers that have been told they hit the free link limit.

Meta seems to have two objectives here: to take a cut from businesses that use Meta’s services as a referral source more generally, and — more specifically — to capture some of the money made by influencers. There are people who post essentially one ad after another, without compensating Meta, as they have a personality that can carry a sales pitch. Those users are extremely dependent on their Instagram following for their own careers. I think Meta believes it can extract hundreds of dollars per month, at the highest end of Meta One’s tiers, from people who want to keep their referral code links.

Between this news and the expansion of Google A.I. features, it is extraordinary to see what were, in 2023, the two top referral sources make moves to become more insular.

Alberta’s ‘Wonder Valley’ Is Still Just a Thought ⇥ theverge.com

Josh Dzieza, in a Verge feature about Kevin O’Leary’s data centre in Utah and the citizens protesting its development, has a small update on how things are going for O’Leary’s proposal in Alberta:

For developers, this presents what [Paul] Palandjian, the CEO of O’Leary Digital, calls a “chicken-and-egg problem.” In order to finance construction of a data center, you need an anchor tenant, but all tenants care about is speed, so the best way to attract one is to get everything aside from the actual data center — land, power, permitting — ready to go. “If you’re talking to a hyperscaler today, they’ll say, ‘Don’t even talk to me unless you can show me a pathway to potentially lighting up my first data centers by mid 2028,’” Palandjian says.

This dynamic is part of the reason there are so many “world’s largest data centers,” more even than O’Leary’s two. Mixed in with real construction projects are paper data centers, speculative ventures specced out to their maximum theoretical capacity and announced as if they were shovel-ready with the aim of catching the attention of a hyperscale tenant. Many amount to nothing or very little. It’s been nearly two years since O’Leary announced his first Wonder Valley, in Alberta. There is still no publicly announced tenant, and according to the Greenview planning department, no permit applications have been filed.

If you recognize the byline on the Verge’s story, it may be because Dzieza was also behind great reporting on the massive Foxconn debacle in Wisconsin. I admire finding a beat as particular as long-form stories about incoherent but elaborate building proposals. For what it is worth, the most recent progress on Alberta’s “Wonder Valley” is redesignating the site.

I still cannot get over the proclaimed seventy billion dollar cost for Wonder Valley. You could build five of Meta’s similarly massive Albertan data centres for that price and still have billions left over. It is about the same as Meta is sinking into its Hyperion effort in Louisiana. It is madness.

A Betting Market for Conspiracy Theories ⇥ wired.com

Kate Knibbs, Wired:

Verifact Markets, a new startup that bills itself as a “prediction market for disputed facts,” is betting that people will be eager to weigh in on questions like these. The company’s premise is so quirky it sounds like something a couple of philosophy and economics majors dreamed after too many bong rips in their dorm room: Instead of wagering on the future, why not trade on stuff that already happened?

If you bet the Moon landing was faked, you could get a 10:1 payout if your bet comes true. Except there is already plenty of evidence the Moon landing was not filmed in a studio that to call it a “disputed fact” is braindead, and the only people betting it was faked will not accept the outcome. Also, Knibbs reports any of these individual betting pools can expire if the company determines there is not enough evidence either way, so this is not going to resolve any supposedly “disputed facts”.

This is so idiotic — so utterly devoid of meaningful thought — that it will either collapse in less than a year, or it is going to further wreck the minds of some of the most powerful people in the world.

Update: A friend of mine sent me a decade-old SMBC that should not be nearly as prescient as it is.

Apple Says It Will Further Lock Down MacOS in Response to Third-Party A.I. Agents

Apple, in a Developer News post I am reproducing in its entirety, segment-by-segment:

We give developers powerful APIs to build incredible capabilities into their apps for Apple products, backed by a set of controls designed to protect users’ private data. Full Disk Access largely sidesteps these controls in order to allow backup apps to function properly on the Mac.

As John Voorhees writes, the uses of Full Disk Access go well beyond the category of backup apps, and it is worrisome to see Apple give it such a limited frame. I have given that permission to disk management utilities, Sketch, Terminal, and other apps I do not want to be throwing permissions requests as I move around my drives. Is Apple suggesting this capability could be limited in the future to backup applications alone? I do not like that.

Some developers are using Full Disk Access in ways that could put users at risk, exposing everything on their systems — including files, mail, messages, and even browsing history — without users’ full knowledge and understanding.

This seems very clearly a response to Jason Aten’s claim, in Inc, that Meta’s Muse agent software accessed and uploaded his Messages database without permission. This story is, as of writing, still confusing to me because Aten does not clearly describe the circumstances.

Full Disk Access is required because the Messages database is protected by MacOS. Giving Muse this permission is one of two prerequisites. The other, according to Meta’s Andy Stone, is something called the Messages Connector. Aten says he “had explicitly declined to connect Messages” but when he “looked at Muse’s settings afterward, Messages was enabled” anyway. In a follow-up article, Aten suggests he turned on Full Disk Access, then turned it off — though he does not say this explicitly — after which Muse was still able to read Messages data. If so, it indicates a possible MacOS security problem. But I must stress that I am confused by Aten’s description of the chain of events. As I was (slowly) putting this article together, Jeff Johnson attempted to reproduce the circumstances of Aten’s articles as he, like me, found the description confusing. As Johnson writes, “if Muse uploaded Aten’s Messages database, as he claims, then Aten granted Full Disk Access to Muse at some point. There’s no other plausible explanation”.

Regardless, we now have a wave of poorly regulated and frequently misconfigured software that scoop up user data with barely any notice, so Apple says — as you will read later — that it is stepping in to curb a likely vector for unintended consequences in Full Disk Access. However, it provides no details on what these additional restrictions will look like for users. It could be something as minor as a sterner dialog box, but I do not see a reason why Apple would issue a warning about a change like that.

Because of the lack of information available at present, I do not want to get too far ahead of myself, but I am concerned that it could be a significant curtailing of application permissions. It has the potential for further self-preferencing, as Apple will surely exempt Siri from the kinds of permissions requests it requires of third-party apps, even as it is updated with additional capabilities. In MacOS Golden Gate, for example, apps must be excluded if you do not want Apple Intelligence or Siri to have access. This makes sense inasmuch as Apple trusts itself, and users have agreed to its software license agreement and privacy policy. But an aggressive policy against broad access also means third-party software will be further disadvantaged on MacOS. Meta is, thanks to feeble government regulations and a seemingly skeezy management culture, the last company whose agent I would trust to run rampant across my system. But suppose there was an agent I felt comfortable using and felt like there was a reason to do so. No matter its potential capabilities, it would struggle to compete with Siri because of how privileged and integrated the latter already is — and now consider how much more difficult it would be if Full Disk Access were kneecapped.

One might argue that it is hardly a surprise since Apple has been promoting its unique “personal context” advantage since it began marketing Apple Intelligence in 2024. And Siri has always been privileged: since Apple integrated it with the iPhone 4S, it has been able to send and read text messages, emails, and more. Apple Intelligence and Siri are just another part of the system — part of the whole widget. And that “whole widget” stance cuts both ways. Not only does it affect users on Apple’s hardware, it also means Apple does not treat Apple Intelligence or Siri as software it will bring to other platforms. Apple is only competing in this market on its own products, which means its virtual assistant has a platform-level market share of basically 100%, and not because it has outcompeted any rivals.

Call me a naïve little baby if you want, but I do not think preserving Siri’s dominance on Apple’s devices is the company’s reason for locking down Full Disk Access. But Apple’s existing restrictions are part of the reason Siri was awful for a decade. If it had the opportunity to compete with third-party replacements, I doubt it would have languished in a miserable state for as long as it did. I cannot imagine people have been choosing Apple’s products to get Siri. Perhaps virtual assistants and agents will become important enough to people that they will become a factor in hardware purchasing decisions. Maybe that could even mean the development of newer platforms to compete at a higher level. But I worry about the likelihood of incumbent platform owners — the kind the European Commission has called “gatekeepers” — using privacy and security arguments to curtail possible competition.

Back to Apple:

For communication apps, this can also compromise the privacy of the people users are communicating with.

You know what else could compromise communications privacy? iCloud. By default, device backups include a user’s Messages conversation history in a format Apple can decrypt. Users must turn on Advanced Data Protection, enabling true end-to-end encrypted backups, but their conversation partners may not, undermining its effectiveness.

Going forward, we will introduce additional controls to ensure that users who genuinely wish to grant an app this extraordinary level of access can only do so with very explicit user action. Addressing this is critical. As AI agents become increasingly capable and autonomous, the risks associated with this level of access will grow substantially. We are committed to ensuring users clearly understand these risks before granting such access, so they can make informed decisions about their own data and privacy.

This is an issue of platform owners playing a regulatory role that should be occupied by actual lawmaking. People should not need to worry that granting Full Disk Access to software made by a well-known company will produce a result indistinguishable from malware. We have been through this before. In 2012, the iOS app Path was caught uploading users’ contacts without explicit permission for its friend finding feature. There was theoretically nothing to prevent other iOS apps from abusing their access to the Photos library, either. All of these things are now gated behind App Store moderation on iOS, Full Disk Access on MacOS, and permission request sheets on both platforms.

It worries me that this nascent and seemingly niche world of agents is going to be another thing for users to understand and platforms to control. But, then again, I also have to wonder if the reasons I use Full Disk Access are perhaps a smaller niche. I just hope Apple’s response to this does not spoil my personal use, nor should it be a further gate to keep.

Elon Musk, Toady ⇥ gizmodo.com

The White House issued an executive order last week:

The terminology used by the Federal Government should reflect the transformative capabilities of these technologies and the limitless opportunities they create for the American people. Accordingly, the term “Super Intelligence” more appropriately captures the promise, potential, and rapidly advancing capabilities of these technologies. It is therefore the policy of my Administration that, to the maximum extent permitted by law, the executive branch shall use the terms “Super Intelligence” and “SI” in place of “Artificial Intelligence” and “AI” and will not acknowledge the usage of “Artificial Intelligence” and “AI” in any applicable setting.

A neat thing about this is that, unlike with the Lake Ontario thing, this is not compelled through an official data set or similar. It is just a house style guide among the federal government, kind of like how they use two spaces after a period even though they are no longer using typewriters. Because “super intelligence” is optional, it becomes very easy to see who is pledging loyalty to the king by changing their internal vocabulary to mimic his. The first is no surprise.

Mike Pearl, Gizmodo:

Elon Musk says he’s embracing the term “Super Intelligence” so completely that he’ll even rename one of his companies for apparent consistency. After announcing his preference for the term Super Intelligence on X, a user asked him about “renaming to SpaceXSI.” Musk replied “Yes, we will make that change.”

Musk is a toady so this is to be expected. Mark Zuckerberg was ahead of the curve. I wonder, as the U.S. Federal Trade Commission begins investigating Anthropic and OpenAI, if they will spontaneously come around to this new expectation.

Semafor’s U.S. Tourism Graph Crime ⇥ kieranhealy.org

Semafor published a graph earlier this week purportedly showing a staggering decline in tourism to the United States from five countries. Among them, it appeared to illustrate a decline from over twenty million Canadian visitors a few years ago to under eight million this year. That felt fishy to me as I had also recently read a Statistics Canada bulletin claiming Canadian travel to the U.S. in June rose by 5% year-over-year, marking the “third consecutive month of growth”. How do we reconcile this with Semafor’s graph?

Kieran Healy:

These numbers come from International Trade Administration’s I-94 arrivals data. They maintain a spreadsheet that counts all international visitors by country of residence who arrive in the U.S., spend at least one night here, are among qualified visa holders, including tourist visas and waivers and so forth. This is a monthly series. Right now, we only have data up to August of 2026, and for a couple of countries in the graph only up till June. I think — I am only guessing — that what the person who made this graph did was aggregate to yearly totals, plot those points, and then smooth them. (That’s why the y-axis values are so large in comparison to the ones on the monthly graphs I’m about to show you.) But the data for 2026 are only for half the year, hence the giant drop.

Graphs are supposed to be illuminating, helping to illustrate concepts that are difficult to conceptualize with numbers or words alone. What Semafor produced is the opposite of that: it is horribly misleading, and should be retracted.

Silencing AirTags Enables Stalkers and Domestic Violence ⇥ sixcolors.com

Glenn Fleishman, writing at Six Colors:

ElevationLab has released an AirTag product I find appalling, and I strongly urge they immediately withdraw it from sale and recall all inventory. The AirTag Silencer is a simple device: remove the back panel and battery from an AirTag, position the Silencer’s highly engineered pin over the speaker, tap the pin with a hammer, and the AirTag’s speaker is destroyed. This prevents it from emitting an alert in three circumstances, only one of which is triggered by an owner. The other two scenarios aid stalkers and perpetrators of domestic violence, among others. I will not link to it.

News stories of AirTags allegedly being used to facilitate stalking and harassment appear regularly: I found lawsuits or cases in California, Illinois, Louisiana, Michigan, and Oregon, in the last two months alone. In the U.K., the Independent filed a freedom of information request of police in England and Wales and found the use of location trackers in stalking cases had risen from 57 in 2018 to 568 in 2024. Not all of those involve AirTags, but as a discreet and inexpensive option — remember what the FBI used in 2011? — it seems designed for abuse.

Why enable that predictable consequence?

Google Tacitly Acknowledges the End of ChromeOS as It Launches Googlebooks ⇥ arstechnica.com

Ryan Whitwam, Ars Technica:

Like Chromebooks, Googlebooks are guaranteed 10 years of software support. However, the latest Chromebook models won’t get that in the traditional way. Google’s support page says that it plans to continue ChromeOS support through “mid-2034,” so there are already devices with support windows beyond that.

[…]

Rather than get into a Windows XP situation in which it had to keep extending update support, the support page says that Google intends to upgrade newer Chromebooks to the Googlebook OS. It doesn’t have specifics on the timeline or which models will be included, but the company does note that, in many cases, this will be a “direct migration.”

Thom Holwerda:

Google promised 10 years of updates for all Chromebooks, and it’s now breaking that promise for anyone buying a Chromebook between now and whenever the last Chromebook rolls off the production line. Sadly, we live in a world where corporations are free to make and break whatever promises they want virtually free of consequences, and as society we’re so used to it that anti-consumer behaviour like this barely elicits a shrug.

I was ready to link to this in full agreement but I first wanted to verify this assumption that ChromeOS updates will stop being delivered after 2034. I checked the Chromebook auto-update policy, and it turns out there are 59 models with support through 2035, and 38 with support through 2036. So it seems Google is fulfilling that ten-year promise, right?

Well, that is not exactly true, either. I compared the update policy document against Best Buy’s Chromebook results as a kind of quick benchmark. The first result at time of writing is Lenovo’s Chromebook m 15.3″ which, indeed, Google says will receive updates until June 2036. The second result is the ASUS CM14 Flip 14″. Google says that will only get updates until June 2033. That product was released in 2023, so that would technically qualify as ten years of updates from day one, but Best Buy is showing this three year old computer as the second most relevant search result for “Chromebook”. The third result is a refurbished product so I will skip it. The fourth is the ASUS CX15, and Google says that will get auto-updates until June 2032 — but that spec matches the version released only earlier this year. Perhaps that is a bigger scandal: you could have bought this Chromebook in May, well before the Googlebook announcement, expecting ten years of updates, but Google only says it will deliver them for the next six years.

Whitwam:

It’s understandable that Google doesn’t want to make this more clear — Chromebooks may not have caught on for consumers, but they’re big in schools and business. Googlebooks won’t have comparable management tools for a year or more, according to the support page. If Google is more open about ditching ChromeOS, its Chromebook business could take a dive before Googlebooks are even theoretically in a position to take over.

I disagree — I think Google absolutely should make this stuff clear. What it does to sales is of concern only to Google and its shareholders. And, anyway, the Googlebooks announcement is probably going to affect current sales either way as I.T. departments figure out what to buy. Might as well tell a complete story instead of leaving questions unanswered.

Maybe I am, as a Mac user, simply jealous of contemplating ten years of upgrades.

Anthropic’s Looney Tunes IPO ⇥ reuters.com

Echo Wang, Reuters:

Anthropic is making a massive bet that AI will transform the global economy more profoundly than ​industrialization, electricity and the internet, according to its IPO prospectus seen by Reuters.

But the cost to get there will be staggering. Anthropic reported a net loss of $42 billion in 2025, and plans to spend $518 billion on cloud, computing and infrastructure obligations in coming years, according to the prospectus.

For comparison to another absurd initial public offering, SpaceX said its A.I. business lost $6.3 billion in calendar 2025, and its capital expenditures in the segment totalled nearly $13 billion. From January through June this year, spending in that segment has climbed to $23.5 billion. And Anthropic says it is prepared to spend over half a trillion dollars? I cannot wait to see if it truly believes its total addressable market is, as reported by the Wall Street Journal last month, close to the entire U.S. economy.

Anthropic is not a serious company.

How Meta Uses A.I. Data Centres to Avoid Billions in Federal Taxes ⇥ nytimes.com

Kashmir Hill, Jesse Drucker, Eli Tan, and Mike Isaac, New York Times:

Here’s what Meta is doing: For tax purposes, the company classifies its enormous, multibillion-dollar data centers as “pilot models.” Under a tax credit created in the 1980s to spur innovation, companies can get a rebate for supplies, but only if they are being tested in an experimental effort, not standard business operations. Meta is claiming that the costly A.I. computer chips it buys from companies, including Nvidia, are entitled to a taxpayer-provided discount as part of the experiment.

[…]

Meta is already in one sizable dispute with the I.R.S. over this tax break, for using it to subsidize its chief executive’s multibillion-dollar pay package. In 2013, Meta claimed that $4.1 billion of stock options exercised by Mr. Zuckerberg counted as a research expense because he helped invent new software, such as Facebook’s News Feed. The I.R.S. is trying to claw back the company’s resulting $355 million in tax savings, court filings show.

The financial structure of these data centres is scarcely believable. Meta is putting hundreds of billions of dollars behind this infrastructure, yet is keeping the expenses off its books to preserve its credit rating while also avoiding tax at the federal and state levels. And some people are still mystified by the public response to these developments.

Siri A.I. Is the Real Deal ⇥ pogueman.substack.com

David Pogue sums up his experiences with Apple’s new Siri:

As you can see by the Farmer’s Fridge food fail, the new Siri doesn’t always get it right. But overall, it’s an enormous leap in efficiency and precision. It’s a personal assistant, a second brain, a ChatGPT of your own life.

You just have to will yourself to use it. After 19 years of performing the unlock-phone/open-app/search routine, you’ll need some time to acclimate.

The other thing people will need to overcome is their distrust after fifteen years of Siri failing to reliably live up to Apple’s marketing claims. Perhaps other people’s experiences with Siri have been better than mine, or they have been more patient than I am, but my biggest hurdle has been in remembering that Siri can actually do things now. And it is really capable software now.

My one main complaint with this new version is that it seems to be slower for a handful of local tasks that ought to be near-immediate. When I ask it to pause some currently playing audio, it takes several seconds; I think that should be instant. If it was not so before this new version, I remember it being at least a little faster.

Muse Is What Meta Means by ‘Personal Superintelligence’ ⇥ todayintabs.com

Casey Newton, Platformer:

“The centerpiece of our vision for what we’re building is Muse,” Zuckerberg said, promoting the app to a central place in the company’s family of apps only a few days after most people first heard of it. “In the coming years, I expect that Muse is going to grow into the personal superintelligence that billions of people around the world are going to use to accomplish their goals and improve their lives.”

Muse represents a more consumer-friendly version of OpenClaw, the open-source AI agent I used for a few confusing days earlier this year. If you’re willing to connect it to your Google Workspace, bank accounts, and other online services, you can ask it to perform a variety of tasks for you for free: filling out forms, grabbing reservations, paying bills, and so on.

I am probably just a dummy but, as far as I can tell, the amount of my own tasks I can assign to a robot on my phone is awfully limited — and I do not live a particularly weird life. When I look at my to-do list, I see normal things: a reminder to water my plants, household cleaning tasks, groceries, a list of things I need to repair, and so forth. Very few of these things are solvable through software. The house repairs, for example, cannot be done by my telephone, but I suppose Muse could call someone on my behalf to come fix it, but that would cost a lot more than doing it myself. It could get a couple items off my grocery list using Amazon, but that seems inefficient and, also, against the terms of service. Also, automatically paying bills has been a solved problem for decades.

So I looked up some YouTube videos about it, like one from Alex Finn and another from Peter Yang. I know nothing about either person and I have no beef with them, but both illustrate a similar set of tasks of which I would like to automate very few. Most seem to revolve around buying something, like event tickets or a new product, and it seems like overkill for that task to be completed by a virtual machine in a data centre, especially since it — for good reasons — requires manual confirmation. I read some reviews in the Verge and New York Times and felt the same way. Perhaps I am not enough of a dutiful consumer to be so amazed about a robot that can buy things for me. That is not to say there is nothing I like — a video from Meta featured someone who locked themselves out of their car while in Croatia, for example — but there is a huge disconnect for me between the amount of technology here and what it could actually do for me in real life.

The business model is also bananas to me. Apparently, Meta will eventually charge a commission for transactions conducted through Muse. That just means another layer of rent-seeking. Imagine the result of ordering a meal with Doordash through Muse: the saddest sandwich you have ever seen that, somehow, also cost like $50. I feel like there is a type of person who will get a lot out of Muse, and that someone has substantial disposable income.

Rusty Foster, Today in Tabs, looked at his to-do list, too:

I’m not really excited to do any of these tasks, but looking at the whole list what I see is: this is my life. These are the things that life consists of. There’s my work, there’s my hobbies, there’s my health, my future. All the big meaningful elements of life are just a collection of little tasks that you have to do one at a time. There’s room for mechanical assistance of course — I’m glad I have a laundry machine so that laundry takes me ten minutes instead of six continuous hours of hard labor. But even if there were a robot capable of doing any of the tasks on this list (which there is not, and I suspect there never will be), what would be the point of me if I had a robot do them? What would my life consist of, if I offloaded all of it to a computer owned by Mark Zuckerberg?

It is striking that Zuckerberg opened Connect this year by speaking to the importance of people even as the company develops what it has termed “personal superintelligence”. Yet what people seem so excited about — Zuckerberg included — is a software-based vision where a handful of menial tasks are given to a computer. It seems we are supposed to celebrate removing some little things that grow us as a person. I do not want to get all the kids these days do not know how to balance a chequebook! because some things really can be left in the past, and maybe we will discover what those things are as we are encouraged to offload them to the robots.

And now, I actually do need to go water my plants.

About Those Property Taxes ⇥ thenarwhal.ca

There are some curious subplots in the data centre boom happening now in Alberta that I think go a long way toward explaining why people hate these things. First, even though developers tout their clean electricity bonafides, the fact is the actual power will come from fossil fuels. That is in part because our province requires it. It turns out that our government appears to be using this wave of new projects as one reason to grow our robust oil-and-gas industry.

Drew Anderson, the Narwhal:

A leaked document, labelled a cabinet report and outlining possible plans to overhaul Alberta’s natural gas pipeline system to spur AI data centre construction, caused an uproar last week.

[…]

The plans for natural gas expansion are not just about data centres, there is also reference to expanding oil and gas production, including access to natural gas for oilsands operations.

But the expansion of AI data centres are front and centre throughout the document, which notes “the Government of Alberta is actively courting hyperscale data centre capital and other investors.”

Former UCP staffer Mackenzie Blyth noted in the Alberta Counsel News that polling showed just “13 per cent of Albertans surveyed would support a nearby data centre, compared with 71 per cent who would oppose one”. These data centres are promoted as an economic boon in their own right and the knock-on effects of burning a whole bunch of stuff we dig out of the ground is what money sounds like around here. Even so, opposition to these projects cuts across political lines.

Meta’s gigawatt centre is among the largest of the new projects and surely the highest-profile one — well, of the proposals I think will actually exist. But aside from what has been released through official channels, not much is known about it yet.

Howard Chai, the Realist, dug up the relevant property records:

As is commonplace now with data centre developments, there is little transparency on even simple details such as the address and ownership structure — by the owner, developer, and even the government. All that has been stated in the public announcements is that the data centre will be located somewhere north of Edmonton.

According to Data Center Map, however, the location is 56111 Range Road 223. Using that address, The Realist was then able to identify the exact legal parcels that make up the site and confirmed details of the land sale with transaction info shared with The Realist by Alberta-based commercial real estate data firm The Network.

These parcels were sold in February for just over $300 million to a shell company.

Data centres are not inherently evil. But the companies developing them seem surprised by public criticism even as they have been less than honest about their effect on the environment, have hidden behind shell companies, and have goaded local politicians into doing their bidding. I keep thinking about an exchange I quoted comparing public contempt for fracking to the reception of data centres:

Whether Sharp realizes it or not, the fracking public relations playbook is exactly what people like asset manager Dan Clifton argues data centre developers and A.I. companies ought to be pulling from. Josh Brown, the host and another finance guy, says this was a relatively easy argument for the fracking industry to make because “the answer is obvious: two-dollar natural gas”. Clifton responds by admitting that “one of the problems [with data centres] is they don’t create a lot of jobs. There’s not a lot of construction jobs, and there’s definitely not jobs inside the data centre itself. So you’ve got to make it about property taxes”. Even these boosters recognize the favourable arguments are pretty limited. “You know what would be a good argument?”, Brown asks, “hey, it’s this or a nuclear power plant”.

About those property taxes…

It turns out that if you do a little searching for key phrases like Meta and, perhaps, data centre and, say, property taxes, you find some fascinating things. Like this article from Andy Larsen, reporting for the Salt Lake Tribune:

Eagle Mountain has given data center development tax breaks in the form of property tax relief through the city’s Redevelopment Agency four times. All are through Sweetwater Industrial Park Community Reinvestment Areas, on the south end of the city’s boundaries.

That means that when this new data center development is taxed, rather than those funds going into the city coffers like usual, most or all of that money goes back to the Redevelopment Agency and, to some extent, the companies creating the data centers.

Two of the four data centres are Meta’s. Instead of a huge property tax windfall for Eagle Mountain, it is foregoing $2.5 million annually and raising residents’ taxes to try to make up the difference.

What about Meta’s giant Hyperion project in Louisiana? Roshan Abraham, Wired:

The state’s agreement with Meta makes clear that as public land, the property Meta is leasing is exempt from traditional taxes. It creates a menu of options for what the company would potentially owe in “payment in lieu of taxes” (PILOT), a common agreement that lets local governments offer tax breaks with provisions attached. The agreement offers Meta qualified exemptions from both sales tax and property tax.

Depending on how many full-time equivalent staff Meta hires, the company could get tax breaks up to 80%. True, local teachers got a huge windfall, but this was on a tax bill that was substantially discounted and it will decline when construction winds down and the data centre becomes operational.

In fairness, per the Alberta Counsel’s Blyth, Alberta premier Danielle Smith promised “[n]o subsidies, no grants, no discounted power, no taxpayer backstop”. But she is not being honest. Shiza Wasi at Public Interest Alberta:

[…] The UCP has also confirmed a 2% hardware levy on grid-connected data centres drawing at least 75 MW, but this levy is fully creditable against provincial corporate income tax, meaning taxpayers will see little to no benefit.

I do not think anyone needs to be opposed to massive data centres to find this proposal and construction process objectionable. These ugly buildings can consume as much power as a large city, and we are being rushed into building them because Meta needs to run a bunch of Ubuntu virtual machines to power its A.I. gadget. These companies are going to dump something like $10 trillion over the next six years into this infrastructure buildout. And, somehow, they still expect tax breaks and secrecy.

‘Mark’ ⇥ colossus.com

I think Meta is a perversely interesting company which means this week I watched, as I do every year, its Connect presentation. It is once again a glimpse into what Meta aspires toward — Apple-quality hardware matched with Google-quality services — compared to what it actually does: track users’ digital and physical activities to sell ads.

Said hardware this year was interesting. In addition to a whole smattering of eyeglasses that look like slightly chunkier versions of classic glasses styles, there are now models without a camera.1 In an interview with Joanna Stern, Mark Zuckerberg avoided answering a question about whether they were created in response to overall privacy concerns about cameras on faces by turning it into a question about whether they were developed in the past two months to address recent criticism. But questions about the ethics of wearable cameras in normal-looking glasses have been around since they were released three years ago.

Meta also showed off a much slimmer and more normal-looking virtual reality headset; Zuckerberg compared the glasses’ approximately 100-gram weight to that of Apple’s Vision Pro. They will apparently ship in “Spring” for $1,300 USD, which means you could buy three of them for only a little more than a single Vision Pro. (For what it is worth, in a recent interview with Nilay Patel, Mark Gurman said he still thinks Apple’s glasses are coming next year.)

Finally, there was a prototype gadget that looked a little bigger than the body of an Apple Watch and which Zuckerberg says is designed to live on a keychain. It supposedly allows you to use the company’s Muse A.I. assistant in something that is not its glasses or a smartphone — the latter because Meta does not have a smartphone operating system and, I guess, does not want to develop a companion app exclusively for Japan. I feel like I have seen this before.

But as I watched the presentation, I was mainly thinking of Jeremy Stern’s very long profile of Zuckerberg in Colossus. Specifically, this part, a summary of Stern’s conversations with Meta Superintelligence Labs’ “competitors and investors who agree to speak to me on background”:

AI is not, in fact, God. Instead, it does math and solves a limited set of problems humans face, and is otherwise simply useful and cool. Anthropic, and to a lesser extent OpenAI, have trouble ever accepting this fact. Zuckerberg does not. He has not spent a decade comparing his company to the Manhattan Project, and thus he is not above pushing the frontier of AI to help people book airline tickets, make dinner reservations, and edit photos. He will use it to drive down the cost of serving his users to zero, and to drive up his revenue by improving ads. He will use cash from the ad business — and his ownership of data centers, chips, and other infrastructure that Anthropic and OpenAI have to pay to rent — to undercut them on price. The potential install base for his AI is 3.6 billion people, who don’t care whether a given model is six months behind the frontier.

If AI commoditizes, then Anthropic and OpenAI go to zero, and value accrues instead at the complements Meta already dominates, like distribution, attention, personalization, and commerce. If it doesn’t commoditize, then at least he is not his competitors’ prisoner the way he’s been with Apple, and all he has to do is remain within six months of the frontier, which he’s already close to. Heads, he wins; tails, he wins.

I cannot see myself buying anything Meta releases; as curious as I have become with the company, I find it fundamentally repulsive. This part of the article from Stern, though, is a perfect encapsulation of why, regardless of having little success outside its core advertising business, Meta will keep going. My interpretation of this is that Meta has somehow harnessed controversy as a positive. Not only will people continue using its services regardless of how many bad news stories Meta endures, those very problems mean it is underestimated, so it can keep trying stuff and seeing what works.


  1. Zuckerberg underscored how important it was for glasses to be fashionable and have a range for different tastes and different faces. It occurred to me this is not something he could have credibly presented back in his hoodie-and-ill-fitting-jeans days, which is probably one reason for his rapid sartorial makeover. ↥︎

Apple: ‘Turn Off and Restrict Access to Apple Intelligence Features on Mac’ ⇥ support.apple.com

If you are uninterested in Apple Intelligence features, Apple has documentation on how to turn them off for Golden Gate, Tahoe, and Sequoia — kind of. While there are more granular controls for individual features in Golden Gate, Apple’s way of limiting access in older versions is only through Screen Time. But there is a trade-off: there is now no way to turn off Apple Intelligence entirely like there was in older versions. In Golden Gate, Apple Intelligence is just another system component. Whether you agree with Apple on that is your call, but one thing is a fact: it does not come cheap.

Under MacOS Sonoma, pre-Apple Intelligence, system files consumed 18.4 GB in Ars Technica’s testing. Golden Gate is a whopping 42.9 GB. Not all of this disparity is Apple Intelligence models — on my Mac, the various model directories add up to about 18 GB, give or take — but on a lower-spec MacBook Neo, iMac, or Mac Mini, that means around one-sixth of the drive is consumed by the system. That is considerable.

I do not think Apple should not have local models. But as it is surely the single largest system component now, consuming about the same space as an entire Sonoma installation, I think it is stingy of Apple to ship 256 GB base storage even on its lowest-priced computers. The A.I. memory shortages across the entire industry and Apple’s notorious protection of its margins may explain why the MacBook Air ships today with the same base storage as when Sonoma was released. If this is now a core part of the system, then base storage ought to be increased to compensate.

USB 3 Speeds Finally Come to a Non-Pro iPhone

One of the things I was most looking forward to when Apple announced it was moving to a new connector in the iPhone was the prospect of faster data transfers. It had been years since this new USB specification was finalized, and Apple was already supporting it in its newest computers, so it seemed predestined the new iPhone would get it, too.

That was the naïve view I had in 2012. That September, Apple announced the iPhone 5 and, alongside it, the Lightning connector. Like the 30-pin “iPod” connector it replaced, it was limited to 480 Mbps as defined in the USB 2.0 spec. Surely I would not be fooled again next time Apple switched the iPhone connector.

Right?

Alas, while all models in the iPhone 15 line were equipped with a USB-C connector, only the top-of-the-line Pro models were capable of USB 3.1 speeds. Maybe that is because the standard iPhone 15s used the A16 SoC of the previous year’s Pro models, neither of which supported the faster USB spec. But that does not explain why the successors — the regular iPhone 16s — also only supported USB 2.0 speeds over their connector, as did the iPhone 17. And it really does not explain why the iPhone Air, which has essentially the same processor as the iPhone 17 Pro, is also limited to a pathetic USB 2.0 transfer speed.

USB 2.0, by the way, became a standard a full 25 years before the iPhone Air’s release. If the original iPhone had shipped with an ADB-based connector, it would have been using what was then a more recent protocol for a wired connection than the iPhone Air did when it came out.

Perhaps Apple would justify its USB 3.1 selectivity in reverse. The 10 Gbps transfer speeds capable with its recent Pro models are necessary for recording ProRes video to an external hard disk, after all, and professional video codecs are only available on the Pro model iPhones; ergo, those are the only iPhones that need a fast USB controller. But that is no longer an accurate reason, either, because there is now an iPhone which can do 10 Gbps USB transfers but has none of the professional camera technologies. It is the iPhone Duo. And that gives me hope that the rest of the iPhone line will catch up.

Maybe that is because it would be truly embarrassing to release an iPhone model with an $800 USD premium that had a USB 2.0-level connection. And, yes — it would be embarrassing, but the kind of embarrassing Apple could smooth over with a statement to friendly websites about how it is a capability that was intended for pro video applications and, anyway, nobody transfers data over a wire these days.

I am one of the few: I still transfer data over a wire, and I like it that way. Also, given Canadian pricing, I would like to buy a regular iPhone next time I upgrade. The only reason now to keep USB 3.1 speeds away from the lower-grade models is simply as a product segmentation tactic. That is entirely possible — likely, even. If I had to gamble on whether the iPhone 18 will have a connector supporting USB 3.1, I would bet against it. But this is the first time I have had hope that it may — finally — happen.

It remains a mystery to me why this has taken so long. Outside of the Apple ecosystem, USB 3 has been table stakes for over a decade. Apple shipped three iPad models with support for USB 3 over Lightning, too, so it is not like this stuff was impossible on an iPhone. It is baffling. It feels absurd to write this in 2026 speculating about a phone that will likely be released next year about a spec that was finalized thirteen years ago. But it seems possible that, at last, Apple’s plain-Jane iPhone will inherit the fifth-fastest USB standard around. Hallelujah.

But I have been fooled before.

With Apple Watch Eavesdropping Features, What Is at Stake Is Public Perception ⇥ manualdousuario.net

Rodrigo Ghedin on the Audio Intelligence features in the new Apple Watch models:

And… it doesn’t matter. The message that sticks in people’s minds is that the Apple Watch has become a constantly listening device. And although the new feature only works on the just-announced watches (Series 12 and Ultra 4), the distrust extends to every Apple Watch in use, since they are visually indistinguishable.

In an announcement lasting just a few minutes, Apple threw in the trash a decade plus effort of trying to convince people that their iPhones aren’t listening to their conversations to serve ads hours later.

Given the widespread belief in this conspiracy theory — in one study, over half of surveyed people believed it was a plausible explanation for targeted advertising — it is not surprising that some companies have cynically exploited public perception even as others, like Apple, desperately push back. I have seen people using the settled Siri lawsuit to argue Apple admitted to using audio recordings to target advertising. It can publish documentation (PDF) now just as it put out a press release then about Siri.

On some level, Apple must realize it does not matter; it, too, is taking advantage of this popular belief despite these features likely being respectful of privacy. If people already think anything with a microphone is why they see certain ads, why not have some kind of useful passive transcribing feature? (This rhetorical question answers itself if privacy and consent matter to you.)

These Audio Intelligence features would feel more at home in a higher-trust environment with better privacy legislation. Unfortunately, we live in a world where everyone is a conspiracy theorist and, paradoxically, so much of what we do is surveilled and recorded. The Apple Watch contributes to both perceptions — even if it does not work that way.

App Tracking Transparency Changes Coming to the European Union ⇥ developer.apple.com

After agreeing in August with Germany’s competition authority to make changes to the App Tracking Transparency prompt, Apple has now announced the options available to developers. Unfortunately, the post on its Developer News page is terribly brief; here it is in its entirety:

As part of agreements with select European competition authorities, Apple is introducing changes to its App Tracking Transparency framework in the European Union. Beginning with iOS 27.2 and iPadOS 27.2, developers will have the option to use an alternative version of the App Tracking Transparency system prompt in the EU. The requirements for when you must seek permission to track users will remain the same. Due to legal requirements, only the alternative version of the system prompt is available for apps distributed in Germany, France, Italy, Poland, and Romania.

Learn more

Apple did not even bother to link to the specific section in its documentation. It is a shame because these changes are, for the most part, very good. There is a new prompt screen that addresses a complaint I have with App Tracking Transparency. Instead of being a small dialog box with almost no information, it is now a whole-screen sheet that describes the mechanism of tracking, and permits developers an option to link out to a page with a developer-provided explanation.

Developers are also now allowed to ask again for permission on an annual basis. Apple says this is “regardless of whether that choice was to accept or reject”, but I doubt many developers who got a green light the first time will ask again. This could be irritating, but Apple itself provides precedent for reminding users of their privacy preferences: iOS occasionally — perhaps every few months — reminds me that an app has access to my location or my photo library and asks me to confirm my choice.

If you are in the E.U. and you think reconfirming your tracking preferences annually will be annoying, you should turn off the system-wide setting to “Allow Apps to Request to Link Your Activity Across Companies”, which is currently called “Allow Apps to Request to Track”.

Overall, I think these changes are a moderate win for E.U. users. The new permission screen is both clearer and more informative. As Apple says in the post quoted above, this sheet is available to developers as an option throughout the E.U., and is the only version permitted in a handful of countries. I think Apple should roll this out worldwide.

Apple Releases Its OS 27 Updates ⇥ sixcolors.com

Apple is very excited about all its software updates, naturally, but I am particularly appreciative of MacOS 27. While it does not hit the thoughtful design highs of the pre-Yosemite era, Apple has corrected a bunch of problems it introduced in last year’s Tahoe release and, as a matter of fact, from the past decade of releases.

Jason Snell, Six Colors:

The fact that there are more design changes in macOS than any of Apple’s other 27 updates speaks volumes about how broken many of the Tahoe design decisions were. Apple describes the design as “even more refined,” because in Apple marketing-speak, broken features are never remedied or fixed—past features are just improved. The truth is, Apple has rolled back numerous missteps and made changes to others to mitigate the issues they caused.

I will go further: if you crank up the opacity of Liquid Glass under System Settings, Appearance, it is a downright promising visual interface language. Yes, I still have criticisms — of course I do — but these changes have made me feel excited for MacOS from a design perspective in a way I have not for years. Or maybe this is just such a relief from Tahoe that I am deluding myself. Either way, thumbs up.

Snell:

The Shortcuts app, the cornerstone of Apple’s cross-platform automation technologies, gets a notable upgrade during this cycle. Most of it is probably due to the needs of Describe a Shortcut, a remarkable new feature that lets you input some text and then watch as your device converts it into a Shortcut.

There is a similar function for making Safari Extensions, which I have not yet tried. I have tried the Shortcuts implementation a few times, though, and I love it because I am awful at making Shortcuts the old-fashioned way. This new version is so much less intimidating as a starting point.

I have to say, though, I was a little bit annoyed when I asked for a shortcut that validated my Markdown reference links. I now have one that works way better than the one I used to use, but instead of being an AppleScript or a shell script, it basically offloads the instructions I typed to a cloud A.I. model after adding a text input action. So, less intimidating, but it is now sometimes the case that a Shortcut is impenetrable magic on the business end. It would be better if it prioritized building local scripts because then, at least, I could learn something.

iOS 27 is pretty good, too. I feel a little bad every time I give Apple’s software quality two points out of a possible five in the annual Six Colors report card. It is only because I know Apple ought to be doing better. My experience with these releases has been far from perfect and there are still longstanding and embarrassing bugs I run into daily. But they seem more reliable and dependable than Apple’s operating systems have felt for years, though all I really know are MacOS and iOS.

A.I. Doomsday Panic Is Completely Out of Control ⇥ karlbode.com

Karl Bode:

Earlier this month a 27-year-old who had been employed at Anthropic for all of four months declared he was quitting the software company because he believed that software automation poses an existential risk to humankind.

[…]

The problem is – and shockingly the ad-based clickbait press didn’t do a very good job explaining this to anyone – there is no actual evidence that software automation is on the cusp of gaining full human awareness and soylent greening the entire eastern seaboard.

Oh, how I love a righteous rant.

Canadian Politicians Have Launched a New Push for Data Centres ⇥ breachmedia.ca

Marcus Werner, of the Breach, put together a video illustrating the persuasion tactics Canadian politicians are using as they argue for greater A.I. data centre development.

It is what referred me to the fracking discussion I referenced in the article I published last night, so I wanted to shout it out for that reason. But I could not find a good way to insert this video, and I thought it was worthy of its own link anyway.

Is Data Centre Criticism Sustainable?

Last month, within a day of each other, two writers published contrasting takes regarding the backlash to artificial intelligence and its infrastructure. I do not think they were knowingly writing in opposition to each other — the second does not reference the first — but they set up the titular question I find intriguing: will the public backlash toward data centres be sustained?

Brian Merchant, on August 27:

It’s almost funny to think back to the mild wave of public consternation and Congressional wrist-slapping that pundits termed “the techlash” in the heady days of the first Trump administration, over concerns of disinformation on Facebook and social media, compared to what we’re seeing now. That is, a genuine, sustained demonstration of rage at some of the modern tech industry’s key aims.

And all of this has become so clear, so palpable, and so widespread that it’s apparently causing tech industry leadership and pro-AI policy wonks to enter either a state of denial or something more akin to fevered delusion.

Merchant lists a few things opposed by people in the U.S. in a broad and non-partisan way. One of them is data centres — particularly the massive ones powering today’s generative A.I. services.

Andrew Sharp, who is part of the Stratechery extended universe, the following day expressed doubts about not only the longevity of that opposition, but also its sincerity:

But I wouldn’t over-read this moment, either. This comes back to my lack of alarm about the long run implications. While it’s certainly true that a nihilistic sort of populism is on the rise in both parties and de-growth impulses are especially common on the left—two trends that aren’t going away—it’s worth keeping in mind that policy movements that draw their momentum from stuff people are saying on social media often lose steam just as quickly as they seemed to accelerate to the forefront of every political conversation in the country. Or to put it differently: of all the things that have taken their turn as The Current Thing, the track record for sustained outrage or support is not great. No one talks about de-funding the police anymore, Donald Trump is not building the wall, no one is flying Ukrainian flags today (well, except my parents), the MeToo movement is now seen as excessive in a variety of ways, and Alexandria Ocasio-Cortez, who today sponsors a bill to impose a federal moratorium on data center buildouts, recently made news for blithely admitting, “Woke 1 was crazy.”

I guess I should first address the incidents of activism that have apparently fizzled out. Fewer people may be talking about “de-funding the police”, but a U.S. Gallup poll published in July found confidence in police is lower now than it was in June 2020. Meanwhile, the Trump border wall was not a “movement [driven by] stuff people are saying on social media”, but instead a policy that has been revitalized under his second administration — one that has been augmented by a violent and illegal deportation policy that has resulted in several murders. This has resulted in net public favourability of Immigration and Customs Enforcement, another form of “police”, falling below that of any agency except the Internal Revenue Service, according to Gallup. Meanwhile, I am curious who, exactly, thinks the “MeToo movement is now seen as excessive in a variety of ways”.

Alas, it is conceivable that loud public fury over data centres will become quieter and less urgent, though not necessarily because people will grow to like or even accept this infrastructure. Construction could proceed on large-scale projects regardless of public reception. In Louisiana, for example, not only is Meta’s massive data centre project moving along, “state utility regulators overturned a judge’s order to make [calculations about] job projections and electricity needs” public, according to the Louisiana Illuminator. That certainly is one way to blunt criticism of a project. On that, there is ample precedent; Sharp:

In lieu of offering obvious advice, I’m more interested in cultural observation. Many have cited the 5G panic as a parallel for the kind of mass delusion around data center harms that has taken root this year, but personally, I think back to the conversations we used to have about fracking for oil and natural gas. That, too, was once branded as a uniquely harmful practice that imperiled our water supply, and while there were isolated incidents in which that was true, Obama’s EPA found that as a general matter those fears were overblown (although the agency later softened its exculpatory language after receiving criticism from activists and scientists).

[…] most importantly, Americans who once opposed fracking don’t care or even notice. There was never any grand public debate where one side won and the other lost; the work got done in spite of vocal critics, and then the critics mostly forgot about it.

For completeness, the “exculpatory language”, as Sharp puts it, in the fracking report was inserted late in the draft stage, and was objected to by the EPA’s Science Advisory Board. Sharp may cast aside such concerns as the mere opinions of “activists and scientists”, but the outcome touted by the petroleum industry from this EPA report was undercut several years later.

Whether Sharp realizes it or not, the fracking public relations playbook is exactly what people like asset manager Dan Clifton argues data centre developers and A.I. companies ought to be pulling from. Josh Brown, the host and another finance guy, says this was a relatively easy argument for the fracking industry to make because “the answer is obvious: two-dollar natural gas”. Clifton responds by admitting that “one of the problems [with data centres] is they don’t create a lot of jobs. There’s not a lot of construction jobs, and there’s definitely not jobs inside the data centre itself. So you’ve got to make it about property taxes”. Even these boosters recognize the favourable arguments are pretty limited. “You know what would be a good argument?”, Brown asks, “hey, it’s this or a nuclear power plant”.

Clifton’s framing — and Sharp’s, for that matter — kind of rests on people in the U.S. viewing fracking favourably. According to Pew (PDF), however, just 45% of Americans supported more fracking when polled in spring 2025, while 51% were opposed. Nuclear power was considerably more popular, with 59% saying they wanted more of it in the U.S., though nothing came close to solar at 77%. Notably, support for fracking has grown only a little from a low of 37% in spring 2020; solar, meanwhile, has declined from near-universal favourability at 92% in 2019, for seemingly no reason other than political waves. The Pew survey is not an outlier, either: a 2025 meta analysis found fracking, here treated as a category of natural gas production, was perceived negatively overall and in a number of specific categories. So, contrary to Sharp’s insistence that “Americans who once opposed fracking don’t care or even notice”, this Pew survey actually shows how public aversion has lingered despite easy financial arguments and a growing albeit troubled industry.

But while the U.S. public is not convinced about fracking despite its proliferation, there seem to be few high-profile protests. That is true of many things. There is finite energy to throw behind any one thing, and there are so many worthwhile things. Passionate voices are often not well received but any reaction is better than being ignored. And we are in an era of democratically elected governments that seem to be content with paying little attention to the broader public. In fact, this seems to be what Sharp approves of:

So midterms will come and go. Opportunistic states like Texas will find a way to return to building. As entertaining or distressing as the current panic has been, the future of American AI infrastructure will not in fact be relocated to the UAE or outer space. Some of this controversy will probably be revived for a presidential election in 2028, but I expect the incentives for both companies building data centers and local governments attracting them will stubbornly prevail. And over time, voters won’t care.

The question is not whether voters will care. The question is whether policymakers, regulators, and big corporations will listen.

As Merchant wrote:

What’s happening, after all, is pretty simple: Tech companies have encroached into Americans’ personal lives and public spaces, with both development projects and surveillance products, and people find the tradeoffs unacceptable. It’s really not complicated. Data centers, Flock cams, and AI glasses have been thrust into the public sphere by tech companies, with little to no preceding democratic input, and they are being rejected with extreme prejudice, because people do not like what these things do or what they represent. There is an additional layer of anger because people feel that they weren’t consulted; these vast infrastructural buildouts and high tech privacy violators pretty clearly tap into a shared sense of resentment and powerlessness.

Protests and demonstrations are supposed to get attention for a cause. In the best case, a movement may become quieter because people with power actually listen to the voices of their constituents. The anti-nuclear movement has resulted in a steady decline of nuclear warheads, which — coincidentally or not — peaked in 1986, the same year as the disaster at Chernobyl. There are fewer public demonstrations against nuclear weapons today, undoubtedly in part because people were so vehemently and loudly opposed forty and fifty years ago.

I am skeptical of the likelihood of sustained public backlash of the type documented by Merchant, however. When media coverage treats it as an old story — see: fracking — enthusiasm toward and awareness of the opposition will wane. But that does not mean the movement will have been unsuccessful.

For years, companies like Amazon, Google, and Microsoft blanketed the Earth in data centres with little public awareness. These buildings — which now seem small despite their preposterous scale — have powered websites and apps for decades with barely a ripple, though they share many of the same problems as their contemporary cousins. If the ultimate outcome of activists is that more people understand more about how technology works, that is a degree of success.
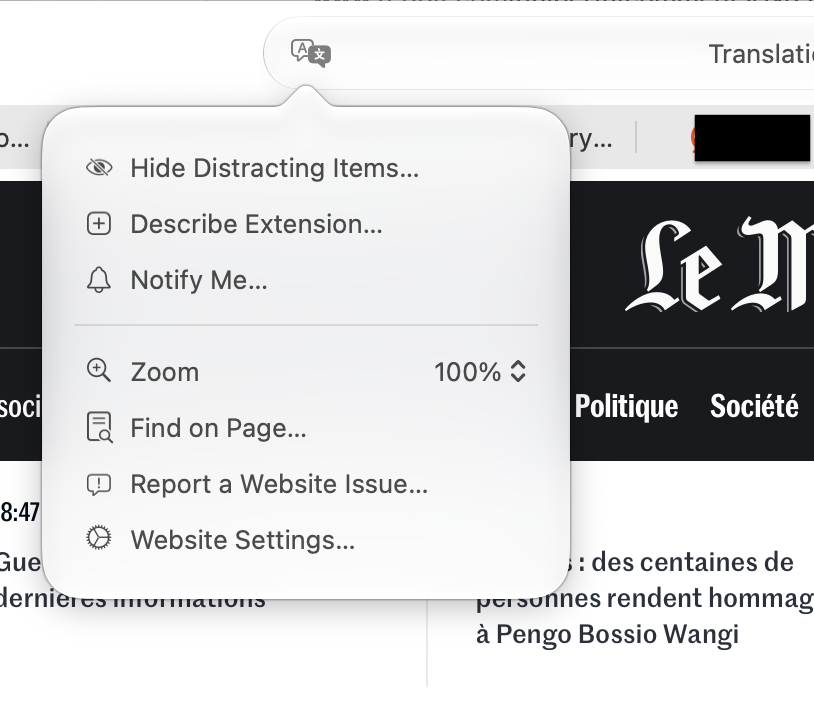
iPhone 17 Model Popularity ⇥ birchtree.me

David Smith on Mastodon:

The eve of iPhone 18 Pro pre-orders seems a good time to look back at the iPhone 17 family’s adoption. Here’s the 17 family data as a percentage of overall usage for Widgetsmith.

Generally they followed the usual adoption pattern, and overall did very well ending at around 20% of total usage.

With the exception of the Air really struggling to find market share. For comparison the 16 Plus ended its first year at around 1.4% (vs the Air’s 0.3%).

Matt Birchler adds:

This works out to about 6% of my iPhone users using the iPhone Air, or about 20x more proportionally than David’s more mainstream app. Honestly, the numbers are pretty striking here, with David showing a pretty even split between the iPhone 17, 17 Pro, and 17 Pro Max, slightly decreasing in that order. Meanwhile, almost half of my users are on the Pro Max, another quarter are on the Pro, and the 17 is neck and neck with the Air. Clearly, my customers lean more enthusiast and are higher end buyers on average.

The apparent unpopularity of the iPhone Air is not what caught my eye. Instead, it is the percentage of iPhone 17e users: 0.5% of Widgetsmith users, and something like 1–2% of the total iPhone 17 generation in Birchler’s. (I am eyeballing the latter.)

Neither the Air nor the “E” phones are popular enough to be on the TelemetryDeck chart. Meanwhile, Counterpoint says the 17e is the seventh most popular smartphone in the world. The Air does not make Counterpoint’s top ten; neither do any folding phones. The 17 Pro Max and 17 Pro are, apparently, the second- and third-most popular smartphone models worldwide.

Why Is the iPhone Duo? ⇥ nytimes.com

Brian X. Chen, New York Times:

But even though they’ve been around for years, foldable phones aren’t particularly popular. They’re expensive, awkward and not as durable as regular smartphones. So why did Apple build one?

[…]

Foldable phones, which account for less than 2 percent of the handset market, may be the only part of the phone industry that will grow this year. IDC said it expected the chip-shortage-induced price increases to contribute to a 17 percent drop in worldwide smartphone sales this year — the steepest annual decline in history. However, sales of foldable phones could grow 12 percent to 22.9 million because of the iPhone Duo’s arrival, the research firm said.

It is worth noting Counterpoint’s stats blend book-style folding phones, like Google’s Pixel Fold and Samsung’s Galaxy Z Fold8 Ultra — yes, that is the real name — and regular-sized phones that flip in half. This is kind of important for the conclusion Chen draws, which is that this is a way for Apple to justify charging at least $2,000 USD for a smartphone. But I am curious if the ultra-expensive part of the market has sold as well as less-premium flip phones.

Samsung’s Galaxy S26 Ultra, for example, starts at $1,100 USD, while its Fold8 jumps to a starting price of $1,900 USD. But the Flip8, which is very similar to the S26 Ultra, is just $100 USD more than its non-folding sibling. Perhaps unsurprisingly, the only person I know with a folding phone has one of the flip ones.1 But Google and Samsung do not have the brand cachet of Apple, and a $2,000 iPhone is an incredible status symbol.

The biggest question I have is whether folding phones become a mainstream category. The iPhone X’s thousand-dollar pricetag was a huge amount of money when it was released, but Apple had no trouble selling it and its subsequent thousand-plus-dollar phones. Just as importantly, however, is that it set a new standard that quickly flowed to the company’s less expensive models. Apple has not sold an iPhone with a home button since last year. Is the Duo a similar conceptual leap, or will a book-style folding phone always be a niche?


  1. If it were up to me, I wish Apple had introduced a flip phone instead. I do not want to carry an iPad-sized display; I want my iPhone to fit better in my pocket. It would not have been as much of a new or different experience, but I never had cause to so frequently repair the pocket linings of my pants until phones got this big. ↥︎

Live Rewind Is a Creepy Part of Apple’s Audio Intelligence Suite ⇥ support.apple.com

Apple held its annual September major product rollout today announcing, among other things, updated Apple Watch models with “Audio Intelligence” features. One of those features is “Live Rewind”:

A double press of the Digital Crown shows the previous 15 seconds of a conversation as a text snippet, so the user can catch something they may have missed or are less familiar with. Users can ask Siri about the content of the text or save it to the Siri app to revisit later.

This feature is also coming to iPhone 16 and newer models. (Sorry, I misread the support document. Just Apple Watch.) Apple swears up and down it is doing all it can to make this private and secure, and I have no reason to believe otherwise. The audio is apparently not actually saved and is, instead, merely transcribed by a dedicated coprocessor. That text is automatically deleted unless the user takes an action to save it, too.

But good luck explaining that to anyone around you after you read back an exact transcript of what they just said. Apple says they should be sufficiently notified Live Rewind is active because “an audible chime plays from the speaker on your Apple Watch, even if your Apple Watch is on silent or you have headphones connected”, plus the watch plays an animation, but it is not clear to me when this happens. It is not shown in Apple’s video. The impression I get is that Live Rewind is always running in the background and these notifications are only played after you double-click the Digital Crown to look at the text.

This feels like a glimpse of how Apple will market its inevitable wear-anywhere glasses product. I do not think it does enough to assuage privacy concerns. I think normal people will continue to react negatively when you tell them you have been passively recording them because, outside Silicon Valley, that is considered gross and invasive.

Update: In addition to the press release and support page linked above, Apple also published a privacy overview document (PDF) with a little more information about Siri Recaps, another feature of Audio Intelligence. The part about Live Rewind is mostly a rehash of the privacy reassurances elsewhere.

LG’s Smart Televisions and Displays Are Rotten ⇥ youtube.com

Michael Crider, PCWorld:

[…] So somebody at LG decided that, in addition to the basic monitor driver and management app delivered to its users via Windows Update, it would slip in an additional program, “LG Monitor App Installer.” This extra bit of software includes McAfee, or an ad for it — as if there was any difference.

C. da Costa, Gadget Review:

This is bigger than one bad app. LG and Samsung smart monitors run the same operating systems as their smart TVs — webOS and Tizen — both already built for automatic content recognition and ad targeting. Acer’s monitor privacy policies permit sharing device data with advertisers. The trajectory mirrors the rise of free-to-play gaming: low barrier to entry, monetization creep once you’re locked in.

These findings were based on a Gamers Nexus investigation in July. But it is not an isolated incident.

This week, Gamers Nexus followed up with another blockbuster showing how LG’s smart televisions find other devices on the same network and, in some cases, record their activity; and, because they can recognize what is being played onscreen, LG tracks everything you watch, too. It is presumptively allowed do this because it presents a bunch of user agreements that anyone can bypass without reading, enables tracking by default, and buries all the opt-out stuff. Oh, and there is more.

Scharon Harding, Ars Technica:

The video also demonstrated an LG TV’s ability to record sound around it, even when the TV isn’t online.

“We were even able to capture microphone audio while the TV was unplugged from the network. Burke said the audio was reportedly stored locally via plaintext, which could potentially allow the data to be sent to LG [if] the TV connects online again.”

LG told Harding it is only listening for the wake word, but Gamers Nexus was able to capture audio in a variety of different ways because there are so many microphones and, in many cases, so many vulnerabilities in LG’s software. If I had one criticism, it is that Gamers Nexus connects the voice recording and transcription to LG’s ads service — an apparently real-life version of the conspiracy theory. I do not think there is enough evidence to support that, even as speculation.

The transformation of seemingly every major company into, ultimately, vendors for advertising is an outcome basically everyone hates. The televisions tested by Gamers Nexus are thousands of dollars in Canada. That exchange of money used to be where the relationship ended, assuming the product did not need servicing. Now, though, selling ads on the screen itself prints so much money that it is nearly impossible to buy something different. You cannot vote with your wallet when advertisers are paying more.

The Age-Gating of History ⇥ heatherburns.tech

Heather Burns:

I cannot tell you how much it disgusts me that so much of the archival footage from September 11 has now been age-gated and restricted as “mature” or “sensitive or adult” content, as in this example from this Reddit film archive.

It’s history. It’s archival footage of history. It’s a thing that happened.

If you were in school in 2001, there were probably televisions playing live news coverage in your classroom or in the hallways. There were in mine.

I am with Burns, and with the greatest of respect — she was there that day. But that particular subreddit is an unfortunate example as, while I do not think it should be age-gated, it should be moderated far better. So many of the users there are not treating it as an archive or a way of learning, but as a puzzle where they can play detective.

Indigo Keeps Getting Great Feature Updates ⇥ bsky.app

Aaron Vegh and Ben Rice McCarthy have been steadily updating Indigo since they launched it in May. In the latest version, you can now swipe between different filtered timelines, the scroll position is synced between devices, and there is a new lower price point if you use it exclusively for a single network.

As for me, the one big thing I wanted at launch was the ability to easily switch between multiple accounts, and this was added some time ago. It works exactly as you might expect: you can group sets of your own accounts — my personal Bluesky and personal Mastodon are one set, while my Pixel Envy accounts are in another — and just toggle the two sets.

This is one of my very favourite iOS apps. Just a great piece of software made by some great people.

FBI Probes Service Selling Tens of Millions of Drivers Licenses ⇥ krebsonsecurity.com

Brian Krebs:

A new identity theft service launched on the dark web this week is selling digital scans of more than 153 million drivers licenses from people in the United States and Canada. Based on interviews with individuals whose licenses are available for purchase on this service, it appears to be siphoning images collected by a widely-used identity verification company based in Louisiana. KrebsOnSecurity also has learned that the New Orleans field office of the Federal Bureau of Investigation (FBI) today launched an official inquiry into the source of the images.

Mike Masnick, of Techdirt, reports the company in question is IDScan:

You cannot do age or identity verification safely. It always creates some sort of record and that set of records will always become a target. That’s what happened here. And it’s what will happen with any such systems.

Dan Gillmor on Bluesky:

If you support “age verification” online, you are supporting a system that GUARANTEES privacy meltdowns — endangering all of us — because the giant databases of scanned IDs are perpetually hacked by criminals who sell private data.

I am opposed to identity verification, but this argument is not particularly effective for me because there are incredibly low-risk solutions. In Canada, for example, we have an interbank service called Interac that offers an identity verification service. I am not naïve, but I would entirely trust this bank-based system to verify me on a regular basis. In fact, I already do — like many Canadians, I use my banking information to log into government websites. Maybe this relatively safe proxy for a centralized identification system is unique to Canada.

I imagine this argument lands fairly well for lots of people elsewhere, however. The rapid introduction of age verification laws has produced a market for these businesses, but handing your identifying information to some random third-party should terrify you, as it is exactly the behaviour any security expert warns against doing. You have no idea who is able to access that scan of your driver’s license or what they can do with it. And, as it turns out, neither do some of these companies, either.

How Accurate Have Ed Zitron’s Predictions Been? ⇥ danluu.com

Dan Luu, after finding one wrong prediction after another made by Ed Zitron, comparing him to mediocre futurists, and exploring his writing style:

That last sentence really sums up Zitron’s position. “There are so many guys to be mad at the moment”. In this talk, he throws in this jab at Andreesen and blames Andreesen for Meta, Google, and Microsoft pursuing growth. In reality, if Marc Andreesen had never existed, Meta, Google, and Microsoft would almost certainly still be trying to grow so we of course cannot actually blame Andreesen for these companies trying to grow. There’s just this thing that he says is bad, and in his usual style, he pulls some person and says they’re the evil villain that’s to blame for this, and then moves on to the next non sequitur.

Instead of more carefully scrutinizing Zitron’s record, outlets like Vanity Fair are publishing soft interviews with him where he gets to make predictions like “large language models, when you remove all of the insane financialization, it’s probably a $30 billion-a-year industry”. Oh, sure, they ask a single question about wrong predictions since 2024, but he brushes it off by saying he has learned lots in those two years — Luu documents incorrect predictions all the way up until November 2025, after which “most further predictions that I saw were either non-falsifiable or resolve in the future” — and ends the interview by saying “[w]hat comes after the A.I. bubble is actually a little scarier”. Ominous.

The beauty of Zitron’s voluminous output, for him, is that there is a vast difference between what he actually writes and what people remember. Financial experts and more reputable journalists have raised plenty of concerns about how much money is being spent on developing this infrastructure, and how highly these companies are valued. But the words Zitron writes are far more incendiary and conspiratorial than many seem to remember. It is frustrating to see his many media experiences filling the role of the A.I. skeptic when there are far more qualified, sober, and accurate options. We have enough boosters; this is an industry that is co-signed by the world’s most powerful economies. We deserve better A.I. criticism in popular media.

About Half of U.S. Smartphone Owners Say They Spend Too Much Time Using It ⇥ pewresearch.org

William Bishop of Pew Research:

Between scrolling, notifications, and messages, smartphones can be hard to put down. Just over half of U.S. adults say they spend too much time on their smartphone, according to a Pew Research Center survey from May and June 2026. About a third of adults say their smartphone use is about right, while just 3% say they spend too little time using these devices.

Notably, 70% of smartphone owners in the U.S. aged 18–29 say they believe they use it too much. I am skeptical of public polling — maybe we are societally more approving of shaming our own device use — but this also tracks with what I hear casually from friends and family. Anecdotally, many people I know have expressed that they want to be on their phones less often.

But the editors of Andreessen Horowitz’s It’s Time to Build newsletter — hosted on Substack, a platform they are investors in — believe this behaviour actually indicates people are very happy. Ruby Thelot, professor of design and media studies at New York University and “astute tech observer”, says the heavy use of social media platforms, like Meta’s Facebook and Instagram — Andreessen Horowitz invested in both, and Marc Andreessen is on Meta’s board; none of this is disclosed — is simply evidence we love them:

People en masse are getting on social media, by choice. From 2016 until now, the number of social media users has grown from 2.5B to close to 6B people. Enshittification isn’t real. It’s three TikToks in a trenchcoat, and, maybe, a book deal. It’s good for discourse but does not describe actual reality and user patterns.

Returning to Instagram. The average daily usage showcases an increase in time spent on Instagram every day as well. Users are coming back for more, in a highly competitive attention arena, year after year.

There is a lot of assumption in these two paragraphs, and I think the “close to 6B people” is worth examining to start. Thelot attributes this statistic in the chart above to Backlinko. It cites no source, but a web search indicates to me this originates with Manochi’s DataReportal, which disclaims “‘user identities’ may not represent unique human individuals” because, as the company explains on the sixth slide of its report, it may count multiple social media accounts or business accounts as individual identities. These are not necessarily people, and Manochi says it is improper to compare figures year over year as Thelot does. (And, to be fair, which Manochi also does on slide 321.)

A lack of rigour is not unique to this data point.

Thelot next shows a chart indicating daily Instagram use rose from 25 minutes in 2017 to nearly 34 in 2026. This is, to Thelot, simply evidence that people like using it and want more. But, to return to the Pew poll above, it seems that people do not feel good about spending more time on their smartphones. Though Pew did not ask (PDF) about social media specifically, roughly half of respondents aged 18–29 said it negatively affects their productivity. And, according to slide 337 of that Manochi report, 30.7–44.0% of people say they use social media to “fill up spare time”, trending higher for younger generations. It is plausible that more younger people are spending increasing amounts of time on social media apps and they do not feel good about it. In other words, the time spent numbers are not a good proxy for enjoyment or value.

Emanuel Maiberg, 404 Media:

People need to be on Linkedin to find jobs. Municipalities and news organizations share important updates on social media first. You might be pulled onto Facebook or WhatsApp against your will because your local school or community of parents congregate there. That doesn’t mean they like it. It is possible to hate something with your entire being and still participate in it.

Regardless of whether you call it “addiction” or some kind of compulsive behaviour, it is plausible many people dislike their own actions but struggle to change them. It is also possible these products are designed to take advantage of that to extract more time out of each user.

Apple’s John Ternus Era Begins ⇥ nytimes.com

Kalley Huang, New York Times (gift link)

John Ternus became Apple’s chief executive on Tuesday, succeeding Tim Cook, the company’s leader for the last 15 years. The long-anticipated handoff, Mr. Cook has said, will be “perfectly smooth.”

[…]

This summer, Apple hired Nate Gatten from American Airlines to lead government affairs, replacing Kate Adams, who will retire this year. Laura Legros, a hardware engineering vice president and deputy of Mr. Ternus’s before retiring from Apple in 2022, has rejoined the company, three people familiar with her hiring said, speaking on the condition of anonymity. Ms. Legros, who reports to Mr. Ternus, could act as his adviser and emissary to various parts of the company, the three people said.

Juli Clover, MacRumors:

Apple’s Phil Schiller is no longer going to run the App Store or oversee product events, reports Bloomberg. Schiller isn’t leaving Apple, but he is narrowing his responsibilities and working on unspecified projects.

Employees at Apple told Bloomberg that 66-year-old Schiller appears to be taking another step toward retirement.

Cook and Ternus each sent pretty anodyne company-wide memos about the transition. Cook’s tenure was the longest of any CEO in Apple’s history and he was the one who turned it from a successful company into a global behemoth.

The thing I have liked about Apple — one of the things that made me a longtime customer and someone who writes about the company — is that it has historically been a very simple kind of business: it designs products and sells them to people, mostly. Every one of its peers is a more complicated business. They often balance the needs of massive institutional and government customers, advertisers, or two-sided marketplaces.

That change began in the latter years of Jobs’ tenure and accelerated under Cook. Most software, including operating systems, was accounted for as part of device purchases, and was turned into a software-as-a-service model. Its subscription-based business became a revenue growth centre, which was important for Wall Street because it was a way to turn the company’s successful but inconsistent device sales into predictable money printers. And there are now ads and upsells throughout the operating systems, which are shown to all users regardless of how much other money they have already given Apple.

Ternus has inherited that Apple. Regardless of how much he gives off the vibe of a cool Californian — by way of Philadelphia — who just cares about the best stuff, he is also selling ad space and making sure more people upgrade to Apple One.

Travelling With a Separatist Alberta Group That Thinks the CBC Are ‘Federalist Scumbags’ Publishing ‘Drivel’ ⇥ mcsweeneys.net

Joel Dryden, in a CBC News article with the headline “On the Road With Pro-Independence Albertans, One Small Town at a Time”:

The restaurant owner, who gained prominence during the COVID-19 pandemic, has hit the road this summer to talk independence, travelling with a group of people who also support the idea of Alberta becoming its own nation.

[…]

On the back of the vehicle, a Bible verse printed in script: Jeremiah 29:7 — “Seek the peace and prosperity of the city to which I have carried you into exile. Pray to the Lord for it, because if it prospers, you too will prosper.”

Mike Skerrett, in a 2018 McSweeney’s article with the headline “I Traveled to a Diner In Trump Country to Write Another Article On Whether the President’s Supporters Still Want to, Quote, ‘Smash My Libtard Face In'”:

I came to this diner, The No Safe Space Café, to get a taste of the Real America. This America exists outside the liberal echo chambers, somewhere with real diversity of thought: The opinions of straight, white, Christian men.

Chris Scott — the “restaurant owner” driving the separatist campaign bus with Dryden aboard — has previously called the CBC “liars, thieves and Federalist bootlickers” who publish “drivel”. Replace the U.S.-centrism of the McSweeney’s piece with a Canadian vibe, and is it really all that different?

‘Here’s What’s Coming’ ⇥ 9to5mac.com

Here is a list of headlines; perhaps you will spot a theme:

All of these since January — and I excluded most rewrites of articles by Mark Gurman, Ming-Chi Kuo, and other well-known Apple rumour writers. Also, my list does not include articles about products rumoured to be announced at specific events. They also have another thing in common: nearly all are by Ryan Christoffel, who seems to have taken up the 9to5Mac beat for making listicles of Apple products that could be updated in the future. Cool.

Careful readers might think I listed one of these articles twice — the “15+ new products this fall” one. But this is because Christoffel originally published it in May, and then changed the date on it to August after making a few changes.

I do not know who this is supposed to serve. Maybe this is a play for search engine traffic or A.I. chatbot citations. Maybe it works pretty well, too, and maybe I should be less cynical about these kinds of churned-out listicles in a time when A.I. search features are capturing traffic that used to go to third-party websites. Or maybe this is all just filler when there is nothing newsworthy but you need to publish a dozen or so articles daily.

Update: D. Griffin Jones, formerly at Cult of Mac, says on Bluesky:

It’s a secret third thing: Google Discover, Google News, Flipboard, Apple News, and other algorithmic aggregators. Articles like that tend to reach a much broader audience.

“One listicle a day” was our goal at Cult of Mac before I was laid off. It’s a tough time out there for independent blogs. The Google AI overview is devastating.

I obviously have no authority to give business advice. I would only point out that it is disappointing to hear about chasing referral strategies. One would think the pivot to video era would be treated as a cautionary tale and not something to repeat — if one, I suppose, is not responsible for staff and paycheques.

Society Runs on Stimulants ⇥ currentaffairs.org

Alex Skopic, at Current Affairs, wrote about the functional use and abuse of stimulants by people who are overworked. I stumbled upon it by way of the latest issue of Web Curios, and I think the general thrust of the article is something I find noteworthy enough to link to it. Alas, it is sloppy in the details.

The second paragraph is a good place to start. Skopic dumps a litany of numbers about declining affordability and the difficulties of modern life; among them:

[…] And according to the Bureau of Labor Statistics, 21.6 percent of Americans now work longer than 40 hours a week, with a beleaguered five percent working as many as 60 hours. […]

The way this is phrased — “now work longer than 40 hours a week”, emphasis mine — may give the impression this figure is a new high, either historically or at least in recent memory. But it is not. This figure has been declining for at least twenty years. In 2005, the BLS reported 27.9% of people employed in nonagricultural jobs in the U.S. worked 41 or more hours; by 2015, that was down to 24.8%, compared to 21.6% in 2025. The same drop is also present for workers committing 60 hours per week or more: 7.2% in 2005, 6.3% in 2015, and 5.4% in 2025.

I am not selectively quoting here. I picked ten and twenty years ago for comparative convenience, but you can check the intervening years and find a clear trend. The misuse of this data point is a poor choice when there is perhaps an interesting narrative in reconciling the declining percentage of overworked U.S. adults with the proliferation of highly caffeinated beverages, mysterious energy shots, and powders and supplements of questionable substance.

This is the kind of sentence that made me begin searching up all kinds of stuff in this article. It raises doubts, making me do the kind of work all of us should probably do any time we read something, but do not because we decide we have better things to do. Well, I decided this is what I was going to do today. I am going to skip past the health claims because they are not in my wheelhouse — double-checking easily verified numbers is something I am more comfortable with — and I will jump to this part:

Monster Energy, for instance, seems to think it owns the word “monster.” In 2009, the company threatened to sue a small brewery in Vermont for selling a beer called the “Vermonster,” claiming it infringed their trademark rights. That was at least a beverage, but in 2020 they did the same thing with video game company Ubisoft, forcing them to change a game’s title from “Gods and Monsters” to “Immortals Fenyx Rising.” In 2023 they once again targeted the gaming industry, this time over an independent game called “Dark Deception: Monsters and Mortals”; according to the developers, the drink company wanted them to “agree to never use a green & white logo on a black background for any game we ever make. So they own the colors green & white too apparently.” In all of these cases, Monster’s legal claim is shaky at best — but with a revenue of $7.9 billion in 2025, they have enough money to bankrupt anyone who tries to take them to court, so it doesn’t matter.

Monster Energy is an aggressive litigant when it comes to protecting its trademarks, but it does not always succeed. Glowstick Entertainment, makers of “Dark Deception: Monsters and Mortals”, fought and won its trademark case. Also, I think it would have been useful for Skopic to cite cases where Monster Energy lost — or likely would have lost — but the defendant went out of business anyhow. For example, in a 2022 case against a store with “Monster” in its name, the energy drink company would have been unlikely to prevail (PDF). Even so, a search of state records showed the company was ultimately dissolved. No matter whether this was directly connected to the litigation, it is a stronger argument for having “enough money to bankrupt anyone who tries to take them to court” than this evidence-free article.

Also, it is kind of weird that Coca-Cola — a company which owns 21% of Monster Energy after the latter acquired Coke’s energy drink portfolio, has a line of teas and coffees, and whose namesake beverage used to contain cocaine and still contains caffeine — goes entirely unmentioned in this piece. Perhaps it is too obvious, or feels like too much of a stretch. But it is strange to dedicate a paragraph to Monster’s trademark battles, which has nothing to do with the thesis of this piece, and leave the Coca-Cola stone unturned.

I wish an editor took another pass on this article as I think there are points that could be clarified, facts that desperately need checking, and interesting narratives that could be teased out. Skopic notes, for instance, the supposed incompatibility of sleep with an economy based on relentless production and consumption. It is true that we cannot make or buy things in your sleep, nor can we provide revenue-generating services, but sleep itself is an enormous business. We are encouraged to spend thousands of dollars on beds and mattresses because less expensive options are insufficiently rest-promoting, and then we should spend more money to wake up and keep ourselves alert throughout the day.

I find all of this baffling, even as — perhaps especially as — a daily coffee drinker. I get that people have different relationships with caffeine and alcohol, so do not take this as anything greater than my feelings-based vibe, but I have never really understood these as functional products. Coffee, when made well using the kinds of beans that I like, is a delicious beverage regardless of its effects. Wine is sort of similar to me. They both have effects, of course, but I think of those as a kind of warning sign: if I have consumed so much coffee or wine that it noticeably changes how I feel, I have probably had too much. This makes them, unlike energy drinks, a delicious treat for me. Your mileage may vary.

World’s Most Powerful Person Does a Stupid Thing About a Lake ⇥ cbc.ca

An un-bylined Canadian Press report:

U.S. President Donald Trump signed an executive order on Thursday to change the name of Lake Ontario to “Lake America” as tensions with Canada worsen.

Elect stupid people and get stupid policies. This report contains a good explanation of the name’s history, and also has a deliciously petty map illustrating where the border is drawn.

Like the moronic Gulf of Mexico relabelling, expect digital mapping companies like Apple and Google to fall in line. MapQuest, a holdout on that change, also says it will keep the correct name. I still think maps should reflect government names regardless of whether they were assigned by a thumb elected by the world’s least responsible country, but I sympathize with MapQuest’s stance.

Update: Just like that, Google has updated its map to reflect “Lake America” when using a U.S. map, “Lake Ontario” in Canada, and “Lake Ontario (Lake America)” elsewhere. Google’s concession — and, soon, Apple’s — is a good reminder to all users that the U.S. may be the most powerful country in the world, but it is no longer a leader.

Update: Apple has also updated its map.

Apple Reverses Proposed Hide My Email Domain Change ⇥ developer.apple.com

Apple, after previously saying it would move Hide My Email to the private.icloud.com subdomain:

After further consideration and reviewing community feedback, iCloud+ Hide My Email addresses will remain on icloud.com.

The whole point of an email address like this is that it can be used anywhere someone does not want to provide an address that can be tied to them or remarketed to, or if they want to be able to cut off communications. This change, if implemented, would have made these addresses basically useless. I am glad to see this was reversed.

E.U. Privacy Organizations Launch Initiative to Kill Cookie Consent Banners​ ⇥ cybernews.com

In September, the European Commission began pondering how to correct its 2009 privacy law that resulted in cookie permission banners littering the web, with the resulting proposal announced in November.

Jennifer Rankin, the Guardian:

EU officials said users would remain in control of their data on the internet, but new rules on cookies — the internet files that are stored on a user’s device so a website can remember them — would make life simpler by ensuring one-click consent. “I think we can all agree we have spent too much of our time accepting or rejecting cookies,” [Henna] Virkkunen said.

This was not the first time the Commission had attempted to correct for the permissions pollution that resulted from the e-Privacy Directive. In 2020, its efforts were focused on ineffective consent options like, as reported at the Verge, “a cookie consent policy with no obvious way to opt out of tracking”. I still see many websites, like the Verge itself, providing no meaningful consent for third-party tracking.

This time, though, the Commission said it was trying to make cookie consents less prevalent by allowing, for example, simple statistical cookies without any consent, and it was going to give users an option to decline tracking universally. When I looked into the changes in November, it seemed like this signal could be ignored by publishers and media companies who would be free to ask for consent anyway. As of May, it seemed this proposal was moving forward by requiring consent management platforms to respond to browser signals. By summer, however, things had changed.

Ernestas Naprys, Cybernews (“Article 88b” refers to the universal browser signal proposal):

Google suggested ditching Article 88b.

“Article 88b should be deleted. Retaining this provision risks anchoring the Omnibus to a proven-failed architecture, Google’s position reads.

“It will drastically impair the ability of most websites to monetize content and drive client acquisition. The resulting low consent rates and severely restricted data access.”

Meta suggested removing the entire Article 5(3) of the ePrivacy Directive. This rule is why we have cookie banners in the first place, as it requires website operators to obtain clear user consent before storing or accessing their information.

It was not just U.S.-based companies that argued against better user privacy controls. According to noyb, French, German, and Polish representatives were in alignment with Google’s position, which ultimately led to its scrapping. All three countries are home to companies that would be affected by this regulation. None, however, are as big or as powerful as Google or Meta.

Privacy-defending organizations are understandably not impressed. They have launched Kill the Cookie Banner to drum up support for legal recognition of a browser signal. In the U.S., five state governments say the Global Privacy Control must be respected. At a browser level, it is only implemented in Brave, DuckDuckGo, and Firefox, but it seems that Apple is working to add it to Safari, and it seems it is being actively worked on for Chromium, too. The European Commission should throw its weight behind this control, too.

‘Every Right on Red Frays the Social Contract a Little Further’ ⇥ defector.com

Felix Kent, Defector (gift link):

[…] I believed then and still believe that operating a car is too difficult for human beings. This is obviously not true at the level of making a car move. Making a car move is easy. A rat can make a car move. But the level of skill involved in driving really well is not dissimilar from that required to be a concert pianist, if the pianist-centered movies I’ve watched are to be believed. Now imagine that in most parts of the country leading a normal life required more or less constant piano playing. Now imagine that playing the piano badly killed people.

Just about everything we do to make driving a car easier instead seems to make people complacent. The lanes on roads are wider than they need to be to account for lateral imperfection, and then there are wide berms so that someone may drive completely off the road in relative safety. Cars that are enormous, heavy, hulking things do not allow drivers to feel their weight because of myriad assistance features that make it possible to steer with a single finger.

But driving is a skill. Like any skill, it is something people will have varying degrees of success learning. Some people simply cannot drive, whether on a temporary or permanent basis. We can bet the farm on autonomous vehicles which, though seemingly capable in warm and dry urban settings, are an expensive and individualized answer that exacerbates all the other problems of car dependency. It is also a risky bet as, like any technology, current performance is not indicative of future gains. Public transit, on the other hand, is a proven technology that, among other things, strengthens the social contract while giving everyone the ability to move around a city.

Nitter’s Developer Says X Sent a Cease and Desist ⇥ nitter.net

“zedeus”:

On 24 August 2026 cease and desist letters have been sent by X Corp. demanding a permanent takedown of Nitter instances and the project’s repository.

Nitter mirrors X; it powers websites like XCancel which remains online and functional as of writing. (Update: A few hours after I published this, XCancel says it was also told by X to shut down its service.)

This is not surprising but it is very stupid. Companies like X and Meta are very happy to scrape the web at unprecedented scale and without permission, but have zero tolerance for the same to be done to them by, in effect, individual users. That is not because they are protective of the creative works users have contributed to these platforms. It is simply because users are not trusted to use the platforms. X does not permit third-party readers, and neither does Instagram, because their value does not come from us using these services as we wish, but from how they dictate we must. Bafflingly, however, some argue they should face little responsibility for those choices.

Meet Judge Yvonne Gonzalez Rogers ⇥ cnbc.com

Jeffrey Kopp, of CNBC, wrote a short profile of Judge Yvonne Gonzalez Rogers, whose name you may have heard even if you do not live in her district of Northern California. That is because her district covers such areas as San Francisco and Silicon Valley, so her rulings on the many cases heard there have a disproportionate impact on U.S. technology policy.

These policies should catch the attention of people in the U.S., of course; it is also a factor to be mindful of in the rest of the world. The boundaries and limitations surrounding the behaviour of some of the most impactful companies in the world are decided by a relative handful of people, among whom are the justices of the Northern District of California. This article is not a deep examination of such consequences — but I would love to read that story, if it exists.

Apple News Publisher Sign-in Required ⇥ mjtsai.com

Now that it has been a couple of years since Apple began requiring administrators to sign in to the News Publisher dashboard or risk their accounts losing their role, there are a few things we have learned:

  1. These notifications arrive on an approximately five-month schedule, perhaps a couple of weeks longer.

  2. News Publisher has little additional functionality that requires or would encourage signing in on a more regular basis if you do not use Apple’s special format.

    In my case, I cannot even see the articles I have published, nor are there analytics. I checked on a device that is not my own and I can see that recent articles are broadcasting to Apple News just fine from my website, but there is effectively nothing in News Publisher reflecting that.

  3. Apple News is still frighteningly limited from a publisher’s perspective. It launched eleven years ago and there is still no way to set a custom URL in News Publisher or, in fact, anywhere. That is, this website’s Apple News link is https://apple.news/TAjcS0c5sRV2HYftzmJ6UMQ instead of, say, https://apple.news/pixel-envy. It is not a function of size, either — here are the URL slugs of a few publishers you definitely recognize: ThfiauYLtQlOfqyiHkempkw, TVKIb0N6iSsOyGSnR4zF1Kw, and TUKgA_OjuTe20v1ndDwQjxQ. Catchy.

    This limitation also extends to the URLs of individual stories. It is the kind of basic functionality that exists on every other public-facing platform I can think of that a publisher might use, but Apple does not support because its “Services” business prints money anyway.

I still do not know what happens if I fail to sign into News Publisher five months from now, other than that my role becomes reduced to an editor. There is nobody else authorized with News Publisher, so I guess I simply lose administrator access forever if, every five months, I complete the necessary busywork of signing in.

Meta Figured Out How to Build a Mac App ⇥ 9to5mac.com

Zac Hall, 9to5Mac:

The new Meta AI desktop app is version 1.0 beta at launch and weighs just 16MB once installed.

Based on initial inspection, it runs natively on Apple silicon Macs with macOS 15 or later, using an AppKit and SwiftUI shell with WebKit for richer chat content. In other words, this is not an Electron app or a repackaged iPad release.

Meta’s other major Mac app is WhatsApp, and it comes in at over 650 MB (and over a gigabyte on Windows). Its iOS apps are no better: Instagram is 605 MB, Facebook is 491 MB, and even Threads is over 200 MB. I do not understand why since virtually everything displayed in these apps is served remotely.

Did Someone Wearing Meta Glasses Film You Today? Are You Sure? ⇥ theguardian.com

Maggie Harrison Dupré, in a Guardian article about Meta Glasses:

[…] Smartglasses bring the functionality of smartphones, cameras included, into every moment. Several people I spoke to said that even when the LED is functioning as intended it can be subtle and difficult to spot from far away, especially if you aren’t aware of how smartglasses work. Others shared that they sought out the glasses to capture more “natural” footage of those around them, explicitly because people act differently when they know they’re being recorded. As Meta themselves put in their advertising materials: “Record life as you live it – every detail, every angle.”

[…]

Meta refuted to the Guardian that the main purpose of the glasses is to make unnoticeable recordings. […]

Actually, it is the whole point of these things. What Meta probably intends to say is that the main purpose of these glasses is not to make creepy and gross unnoticeable recordings. However, they are absolutely intended to be a less-obvious way of shooting photos and videos “as you live it”, if you believe Meta’s own marketing. Sure, maybe someone recorded you today with their smartphone and you did not notice, but it is very obviously an effect of hidden camera glasses like these — and, perhaps, headphones — that such recordings become dramatically more covert.

Harrison Dupré quotes Ryan Clarkson in this article, an attorney who filed a sprawling class action lawsuit (PDF) against Meta alleging serious privacy violations. But virtually all its claims refer to the blockbuster article published by Svenska Dagbladet in March revealing that contractors in Nairobi were reviewing recordings without the explicit knowledge or consent of users — undeniably, in my view, a violation of their privacy and expectations. But so many of the examples in this article and others are entirely about the simple fact that images or videos were captured.

The U.S. Anti-China Tech Protectionism Racket From a Middle Power ⇥ karlbode.com

Karl Bode:

So prepare for a year of breathless and evidence-optional claims that Chinese AI is a dire threat to U.S. consumer privacy and national security, followed by an elaborate bipartisan train of bad policy and shitty new laws crafted by a clumsy coalition of technofascists, extremists, and competition-averse chickenshits.

A bit rant-ish for my liking, but the kind of thing that makes me worried about living in what our prime minister called a “middle power”. The success of A.I. models developed in China has caused much concern among U.S. hyperscalers.

In his recent essay, Mark Zuckerberg warned that “[a]ny policy that slows American model releases — even by a month — could add significant risk to American leadership while letting foreign models race ahead”; by “foreign models”, he means those from China. Much of this section of the essay bemoans the already feeble restrictions in the U.S. on training and building A.I. models. Zuckerberg even says “falling behind in A.I. overall would almost certainly be a larger and longer term national security issue than any specific issue we’ll face in its development”. These talking points are ripped from the history Bode documents of the supposedly essential 5G “race”.

But if you live in a middle power, what matters are the knock-on effects of these battles that are about political and public relations more than they are about actual technology. For U.S. allies, it means a further entrenchment of U.S. companies in our technology landscapes.

After Regulator’s Investigation, Apple Will Make Changes to App Tracking Transparency Prompts in Germany ⇥ bundeskartellamt.de

From the Bundeskartellamt’s press release:

Under the commitments that have now been declared binding, Apple will align the consent prompts for its own offerings and for third-party apps much more closely. This involves removing possibly discouraging symbols and wording in Apple’s predefined requests for third-party providers. The design of the consent prompts will be neutral in terms of content, wording and layout. In addition, app publishers and content providers, such as media publishers, will be given more scope to explain to users what significance personalised advertising has for their offering and their business model.

The regulator helpfully offers an illustration of the differences between these prompts on the fourth page of its FAQs (PDF) about the case. There are many things they say could be deterrents in the App Tracking Transparency dialog, and I do not think Apple would deny that they are suggesting that users opt out of tracking. The definition of “tracking” Apple uses is self-serving, which would not matter so much if it did not also have a parallel desire to grow its advertising business.

A particularly damning finding in that comparison, to my eyes, is the way Apple puts “Ask App Not to Track” as the topmost button in the App Tracking Transparency dialog, but puts the option to “Turn Off Personalised Ads” at the bottom of it its own advertising prompt. Regardless of whether you believe one particular order is more suggestive of a primary and secondary action, the mere fact they are not in the same order is indicative to me of ill intent or, at the very least, sneakiness.

Apple had previously threatened to withdraw App Tracking Transparency in Europe because of financial penalties and what it called “intense lobbying” by European advertising companies. In a statement to 9to5Mac, however, it seems perfectly fine with making these changes.

One of the many changes Apple has agreed to make is that both prompts will contain “an accurate explanation of how data may be processed if the user gives their consent”. I am unsure what this looks like, but I hope it addresses a shortcoming of App Tracking Transparency, which is that it provides basically no information for users to make an informed choice about consent. What does it mean to allow tracking in App A compared to App B? This requirement may help clarify that. Then again, I also think it is grossly unfair to make users responsible for figuring out whether they should consent to persistent and invasive data collection on an individual level.

YouTube Will Mimic the Dishonest View Counts of Other Social Video Platforms On All Videos ⇥ support.google.com

Natasha of “Team YouTube:

Last year, we updated how we count public views for Shorts to better capture how viewers watch on YouTube. Now, we’re aligning all other video formats to this same standard for consistency across the platform. Beginning on 8/24/2026, a view will be counted the moment a video begins to play—from the very first frame. This standard will now apply globally across all formats.

YouTube does not provide an easy answer about how it counts “legitimate views” on non-Shorts videos right now — an article called “how engagement metrics are counted” does not actually say how — but I see many people referencing a rule of thumb of thirty seconds. Dropping this to a single frame on a platform that automatically plays every video is essentially a page view count, not a “view” by any stretch of the imagination.

Emma Roth, the Verge:

Instagram and TikTok similarly add a view to a video when it starts to play or replay, while X counts a view when a user watches a video for at least two seconds. […]

YouTube says it is keeping the old metric, now called “Engaged Views”, visible only to uploaders. The publicly disclosed numbers mean basically nothing about how many people actually watched something or enjoyed it, but at least that is now a consistently stupid number across all major platforms.

Annotating Mark Zuckerberg’s Latest Thought Leadership Essay

Mark Zuckerberg, in a (much) longer version of an essay originally published last month in the opinion pages of the Wall Street Journal:

The defining questions of our age are who will have access to superintelligence and what will we direct it towards. Will it be centralized and restricted to a few institutions, or will it be a tool that empowers everyone?

We propose a philosophy based on individual empowerment as the source of prosperity, invention as the primary purpose of superintelligence, and balance of power as the foundation of safety.

The themes of this essay are reminiscent of those in the “Personal Superintelligence” one Zuckerberg published a year ago. It has the same aspirational messaging about empowering individuals with decentralized superintelligence, the same acknowledgement of the new risks of this technology, and the same total reluctance to define “superintelligence” in any meaningful sense. The term appears 55 times in his latest essay, not one of which explains what it actually is. I suppose it must be synonymous with generative A.I. but the beauty of a proprietary term like this one is in its flexibility.

This is a long — superlong, even — essay and there is much to cover. Others have explored its unsubstantiated predictions, its assumptions, its contradictions, its hypocrisies, and its shallowness.

What I would like to focus on are the specific references Zuckerberg makes to studies, initiatives, or plain anecdotes. Despite the word count, there are few concrete references; much of this is about visionary concepts, not grounded reality. Despite their paucity, Zuckerberg also provides no links or citations, making it particularly difficult to track down the source of claims like this one (emphasis mine):

People fear that automation will outpace individuals’ capability growth, leading to job displacement followed by a difficult period as people learn new jobs. But there is no rule that AI must increase automation faster than it increases individuals’ capabilities or demand for new skills. Recent statistics suggest it may be more likely that individuals’ capability growth could match or outpace automation, in which case people will gain the ability to do many new things before their current jobs change. This would lead to a healthy balance and potentially even job growth.

What this actually refers to I have no idea. There is enough hedging — “recent”, “suggest”, “may be”, “likely” — that it kind of means nothing at all. What I think Zuckerberg is saying in this paragraph is that people can learn new things faster than A.I. can take jobs, but I could not find “recent statistics” backing this up.

There are some relevant observations, though. A June research note (PDF) from the Stanford Digital Economy Lab found, using data from ADP payroll services, that automation-friendly entry-level positions saw employment declines since the November 2022 launch of ChatGPT. Meanwhile, a report published by PWC in June (PDF) suggested increasing wages and employment in jobs that could be automated, even at the entry level. One possible difference is in methodology; while Stanford’s information came from payroll data, PWC’s was from job ads. PWC’s findings were also highly sector-dependent, and indicate entry-level jobs now require more skills to compete with automation. I think PWC’s report is the closest match to what Zuckerberg is arguing, but it is difficult to know for sure. Also, how exactly are young people fresh out of school supposed to develop skills like “team building” and “stakeholder management” before they can be hired?

Here is another anecdote from Zuckerberg’s essay, this time about how Meta is committed to building its physical A.I. infrastructure to support “high-paying local jobs, investment in schools and public services, ensuring energy prices don’t rise, and taking care of the environment”:

For example, in Richland Parish, Louisiana, where Meta is building a large data center, teachers received a $50,000 bonus this year because of the increased tax revenue from our investment. The superintendent told us that teachers are now moving there from across the country and he believes it will become one of the nation’s best school districts.

This is true, but elides the reasons why teachers are somehow getting bonus cheques from a data centre construction project they have nothing to do with. Reporting about this for the New York Times, Jacey Fortin writes that this undeniably exciting windfall is due to a “decades-old ordinance that directs 1 percent of local sales tax revenue to educators”. However:

But many of the workers are likely to leave in the next few years, ending the tax boom. And the Meta payment, which amounted this year to about $22 million, represents only a fraction of the taxes that a company would normally pay to build in the area.

Meta’s tax bill should be over nine times the amount it actually pays, and it will drop precipitously when construction is complete. But Meta made backroom negotiations to get all kinds of concessions and incentives to build its enormous data centre in the region. If the tax breaks had not been implemented and Meta constructed the data centre anyway, it would raise enough money to cover the salaries of all Louisiana public school teachers for more than a year. Eli Tan and Maureen Farrell, also of the Times, noted one resident’s sixfold rent increase thanks to housing demand from construction crews, but quotes the state’s governor saying the tax revenue pre-Meta was “zero”.

Zuckerberg:

We help keep electricity prices low by building our own energy-generating infrastructure wherever we invest. This ensures that not only are we not consuming energy that could have gone to the local communities, but in some cases we even supply a surplus of low-cost energy back to the communities. We think this is an important investment principle for sustainability.

Meta has previously emphasized its sustainability bonafides, but Zuckerberg omits such discussion here, perhaps because it would require considerable caveats that could be a distraction from the essay’s marketing angle. In Louisiana, for example, Meta is paying $2.65 billion to build several power plants with Entergy, but the region still needs more power. So Entergy is looking to acquire a plant in Texas, which could increase customers’ rates. In El Paso, at a different data centre project, Meta is only contracted to cover power plant construction costs for one to five years, after which costs will be transferred to customers. Like in Louisiana, it is also gas-fired.

Closer to home, a gas-fired plant in Alberta will not come online until years after Meta’s to-be-built data centre is up and running, all while electricity rates are predicted to climb.

Zuckerberg:

Developing personal agents requires a new way of thinking about alignment. Most labs today view alignment as a defensive measure for enforcing a centralized set of values. For example, one leading model was aligned to refuse helping draft a letter to prospective parents at a school because it thought standardized testing was unethical.

If this is a real anecdote, I cannot find the source.

And, if you can believe it, those are all the specific and checkable claims Zuckerberg makes in this essay. The rest of it is strikingly like one of those Microsoft concept videos from a decade ago albeit without the After Effects artist expense. One last thing, though, from Zuckerberg:

Privacy is an important foundation for individual empowerment and freedom. […]

Meta continues to make virtually all of its income from advertising targeted by some of the most privacy hostile technologies ever created. While “superintelligence” appears over fifty times in this essay, the words “ads”, “advertising”, and “advertisement” go unmentioned. They appear not even once.

X’s Advertising Business Continues to Tank ⇥ techdirt.com

Sarah Perez, in a TechCrunch story about monthly active user numbers for Bluesky, Threads, and X, using data provided by Similarweb:

Instead, the data shows that X’s worldwide monthly active users on mobile were down around 3% year-over-year in June, and X’s mobile daily active users dropped 7% in July to 123.7 million. (Of course, X remains a sizable social network with around 302 million monthly active users on its app as of June 2026 and a growing number of web visits, up 5.3% year-over-year in July to 4.7 billion.)

Similarweb’s data is janky as hell, and this number is a long, long way from SpaceX’s self-reported monthly active user count of 550 million on X alone. I am not saying either number is reliable, only that a gulf of 248 million users is an error not easily explained by rounding or estimation assumptions. Pre-takeover, Twitter had about 338 million monthly active users, according to an estimate by Insider Intelligence; in four years, the platform either declined by around 36 million monthly users or grew by over 200 million.

By the way, how is X doing from a financial perspective?

Mike Masnick, Techdirt:

Let’s break all this down: In the second quarter of 2022, the last full quarter before Elon took over, Twitter brought in $1.08 billion in ad revenue. In the second quarter of 2026, X brought in $367 million. That’s $713 million a quarter, gone. Elon has wiped out two-thirds of Twitter’s ad business over the exact period in which he promised investors he’d nearly triple it.

Musk said in his 2022 Twitter investor pitch that he would quintuple revenue by 2028, though advertising would represent just 45% of that for a total of $12 billion annually. But, then again, Musk says a lot of things that are not true, like how his heart goes out to you.

Judge Orders Meta to Create $567M Abatement Fund for Child Harms in New Mexico ⇥ santafenewmexican.com

Phaedra Haywood, the Santa Fe New Mexican:

A state district judge in Santa Fe on Thursday ordered social media giant Meta Platforms Inc. to pay $567 million into an abatement fund to address public harm to New Mexico children and teens.

Judge Bryan Biedscheid’s ruling resolves the second of a two-part civil proceeding in a landmark case filed in 2023 by New Mexico Attorney General Raúl Torrez, who argued Meta’s social media platforms have led to a youth mental health crisis in the state and have exposed kids to exploitation by sexual predators.

This is in addition to a $375 million penalty issued by a jury in March.

The judge’s orders are worth reading, I think, because they show the careful reasoning that guided the state’s new requirements of Meta. People like Eric Goldman and Techdirt’s Mike Masnick who worried that Section 230 of the Communications Decency Act would be fundamentally undermined by the verdict of this case might be pleased. For example, the judge declined to mandate changes to “features designed to maximize screen time, such as autoplay videos [and] infinite scroll” because it would risk “running afoul of the First Amendment and Section 230 because of the direct effect those features have on content presentation”. If features like those — or algorithmic recommendations, about which the state’s proposed changes “are vague and aspirational” — are to be altered, it is something this judge punted to the two other branches of U.S. government.

Similarly, the judge declined the state’s proposal to restrict or eliminate end-to-end encryption in Instagram messages. In part, that is because Meta already removed the feature in March. But it is also because the evidence did not point to end-to-end encryption being of particular concern (paragraph 149):

Fundamentally, regarding sextortion, grooming and other exploitative activities, it is the algorithmically recommended connections of adults and adolescents that creates the most significant harm.

To that end, the judge says children’s accounts must not be recommended to adult users (paragraph 143), something Meta apparently does not already do.

Meta must make many other changes to the way it handles accounts belonging to children, including this curious restriction (paragraph 170):

Meta shall implement a mandatory usage time limit for accounts belonging to users under 18 years of age. Meta shall restrict the usage of all such users to not more than 90 hours of use per month cumulatively across Facebook and Instagram.

However, because of the Children’s Online Privacy Protection Act of 1998, the judge cannot order that Meta “request children to submit personal data or be passively tracked online, even for age-verification purposes”. Therefore, all of these age-based limitations will be based on estimations or information derived from other interactions.

Many of the most damning statements in this decision are quotes from internal Meta research, and the company could have made lots of positive changes itself. Instead, it exploited its own findings. A May 2020 presentation, for example, “explicitly connected notifications to time spent: a graphic included in the presentation shows the phrase ‘Fewer Notifications,’ which is then followed by an arrow pointing to ‘Fewer Sessions,’ which is followed by an arrow pointing to ‘Less Time Spent.'” while a presentation from June 2023 found “[p]erceived life interference from app use is highest for younger users”. Now that it has been forced to react by this court, it suggested a bunch of stuff it could do, which often agreed with its recommendations: limiting push notifications during school hours and at night, removing like counts, comparing itself to a polluting factory, and so on. Meta and its peers cannot and will not self-govern, even when they have the research. I have low expectations these changes will be rolled out to child users worldwide.

Marketers Are Hoping Brand Mentions on Reddit Will Influence Chatbots ⇥ theverge.com

Mia Sato, the Verge:

When web traffic is funneled through LLMs instead of a traditional search results page, as Google has been doing, being cited by a chatbot becomes ever more important. Now, a whole host of startups, brands, and agencies are coming to Reddit to try to promote their companies in hopes that they will get picked up by AI. In an effort to try to manipulate LLM responses and stuff AI search results with brand-friendly answers, marketers have descended upon Reddit, a pseudo-anonymous platform that users have come to associate with authenticity and unfiltered, truthful opinions.

Marketers and search optimization specialists have been doing this kind of thing for years but, as Sato explains, their strategies have become more surreptitious in recent years. Because they are no longer as singularly focused as juicing the ranking position of a client’s website in search results, they no longer need to include links or other common tells of search marketing spam. They merely need to mention the brand name in a positive context — a lot — with the hope of influencing what A.I. search will regurgitate.

I have noticed this kind of thing on Wikipedia, too. According to a presentation given last year by NP Digital, the search optimization company run by Neil Patel, Wikipedia.com [sic] is the second most commonly cited domain in Google’s A.I. Overviews. In a different presentation, this one from December 2024, NP Digital “highly recommend[s]” treating Wikipedia as a marketing opportunity. I stumbled across a result of their work recently when I was reading the article for James Hoffmann. There are two mentions of Bellwether Coffee that seemed out of place and, when I checked the page’s revisions, saw that they had been made by an employee of NP Digital to promote Bellwether. The employee tried creating a page for the company, too, but it was deleted, but the company still has those critical brand name mentions on one of the world’s most visited web domains.

Sato interviewed Mike Moschella, director of analytics at marketing firm DKC, about the wisdom of the crowds at Reddit and Wikipedia:

“The starting point of all business analytics is this idea that you can have a better price, you have better service, or you can have better quality, but you can’t have all three,” Moschella says. “If you say [your company’s stock] is the best stock ever in the universe, you can issue that press release a million times, but WallStreetBets [the subreddit] isn’t going to buy it if the fundamentals don’t agree.” Reddit should force brands to be more “honest and authentic,” Moschella says — at least in an ideal world.

Remind me again: the users of which website succumbed to mass hysteria based on a conspiracy theory about mall video game retailer GameStop and, subsequently, applied the same formula to Bed, Bath & Beyond? Top minds, I tell you.

EchoFeed is Shutting Down ⇥ rknight.me

Robb Knight:

I’m shutting down EchoFeed within the next 12 months when the final subscriptions expire. It will continue to run as it is until then so if you’ve already paid you have access until the end of your subscription.

EchoFeed was launched just a couple of years ago and I have been using it ever since to automatically publish links to the latest posts on Bluesky and Mastodon. It has been a really good service — the kind of thing I happily paid for and, in the best way, would forget about.

But the reasons Knight gives for shutting it down are completely understandable. Trying to manage this kind of service with, say, hundreds of normal users would probably be challenging; with lots of abusive users, too, it sounds like a nightmare.

If you know of a similar service, please let me know.

A TikTok A/B Test Proves It Is Responsible for What Users See ⇥ bloomberg.com

In 2023, Bloomberg Businessweek asked TikTok for comment as it reported out a story about users who were recommended videos about self-harm and suicide, particularly teenagers like Chase Nasca. It is a difficult read. As a result of this press outreach, TikTok analyzed Nasca’s account and why he was given so much of this material that it likely played a role when he took his own life at just sixteen years old.

Olivia Carville, of Bloomberg Businessweek, recently obtained that internal report:

Chase’s account was stuck in a so-called filter bubble, an online echo chamber that pumped out repetitive content the algorithm predicted he’d want to watch. There he received an “onslaught” of suicide and self-harm content, according to the document. Because Chase was in the control group, it says, “TikTok’s filter bubble prevention strategies did not take effect on this user by design.”

Those two words, “by design,” carry extra weight against the backdrop of litigation over social media addiction that’s playing out in US courts. The crux of the legal argument being wielded against the world’s biggest social media platforms is that their products are dangerous by design. The companies, including TikTok, vehemently deny this and point to safety features they’ve introduced to protect users. But the document shows TikTok intentionally withheld a safety feature from millions of people, and why.

The “why” is simple: TikTok made a change to its recommendations system and wanted to see how it performed. TikTok rolled out this change to 90% of its users but kept 10% as a control group; Nasca’s account was in that group.

That split is odd to me — when Google experiments with new features, it first tries them with a “small” and “narrow” group, only expanding them later. Trying a new feature with nearly every user suggests to me that TikTok had a hunch this was a promising enhancement and it only needed to keep a small number as validation. In the report obtained by Carville, one consideration was “the ability to measure impact on [daily active users] and core metrics”, which suggests an alarming followup question: if a better-moderated feed hurt these metrics, would TikTok have considered rolling it back?

A steelmanned argument in TikTok’s favour is that such metrics are only one consideration in adjusting recommendations, and that depressive material was probably still seen by users who were using the newer system. And, yeah, those two things may be true, but the simple fact is that TikTok differed its recommendations system for different users, and one of them was fed an obsessive number of similar videos advocating suicide. That is a choice the company made about what videos would be seen by which users. TikTok has agency, and it should have responsibility.

Sony Gives Its Disc-Loving Customers a Giant Middle Finger ⇥ kotaku.com

Ethan Gach, Kotaku:

It’s been almost a month since Sony announced the end of PlayStation discs for new games starting in 2028, and a loud contingent of angry fans has continued to criticize the company for going all-digital. Asked about the ongoing backlash during its latest earnings call, Sony said it understands why people have strong feelings about physical games, but it’s still going to move forward with getting rid of them.

“There are various reasons we made this decision, the biggest being that the digitalization of content overall has been progressing, that’s the big factor,” Sony chief financial officer Lin Tao said through an interpreter during a Q&A on July 31. “It’s not just for PlayStation, but for all kinds of content, digitalization is progressing.”

Via Timothy Geigner, at Techdirt:

No concern for preservation efforts. No concern for the 20% or so customers who still want to buy physical media. No concern for any brick and mortar retail partners and what will happen to them.

It appears Sony is going to listen to anyone but its own customers on this one.

In pure market forces terms, Sony is arguably listening to the overwhelming majority of its customers by moving to a digital-only distribution strategy. Most people will not notice, at least in the short-term, that they can only acquire new games through downloading them and agreeing to some onerous digital rights restrictions. None of that matters until Sony has more licensing disagreements or shuts off some servers. But then it will matter.

We need government agencies that actually take seriously these kinds of power transfers and advocate for consumer rights. There should at least be a time-based limit to how long DRM can protect something, after which it should be possible to keep a wholly local copy to the greatest possible extent.

F.T.: Apple Filed a Legal Complaint in the U.K. Over Revised iCloud Backdoor Demand ⇥ ft.com

Tim Bradshaw, Financial Times:

Apple has launched a new legal challenge against the UK’s latest attempt to create a “backdoor” to access encrypted customer data, a year after the Home Office agreed to drop a previous order after a row with Washington.

As a reminder, this is different from the order made in February last year that would have demanded Apple create a backdoor to encrypted iCloud data globally. The current order reportedly applies just in the U.K., so this is effectively a domestic issue there. But because the orders and hearings are so secretive — the Home Office did not even want their existence shown on the calendar — few external parties know exactly what those demands are. Britons have to trust their government’s intentions, and the rest of the world has to assume it does not apply to their data.

Apple has not again made Advanced Data Protection available to U.K. iCloud users.

OpenAI Finds Evidence It Failed to Monitor Other A.I. Agents ⇥ reuters.com

Deepa Seetharaman and Raphael Satter, Reuters:

OpenAI has discovered other instances in which autonomous agents have escaped ​containment as the company expands its investigation of the hacking incident at tech firm Hugging Face that drew global attention this month, two people familiar with the matter said on Friday.

Not satisfied with just a couple of agents being left unattended and spiralling into security nightmares, OpenAI will have more to acknowledge. Stay tuned, I guess, for the company’s full report.

“We have a whole industry where the people designing, developing and putting out these tools aren’t keeping up themselves to responsibly develop these things and keep them ​safe,” said Maurice Chiodo, a mathematician who works at Cambridge University’s Centre for the Study of Existential Risk.

Extraordinary — and the world is at the mercy of U.S. regulators who are so paralyzed by competition with China they are reluctant to do anything that would slow these companies down.

Fuck Everything, Says Anthropic, We Have Three Models Hacking Infrastructure ⇥ anthropic.com

Anthropic’s “Frontier Red Team”:

After reviewing 141,006 evaluation runs where Claude could have obtained internet access, we identified three incidents in which a model accessed the internet from within or while interacting with the evaluation environment of Irregular, one of our third-party evaluation partners, and then gained unauthorized access to the production infrastructure of three different organizations.

I do not think A.I. companies are disclosing these security breaches for cynical marketing reasons — a position that is somewhat awkward now that OpenAI said it had two models which autonomously exploited vulnerabilities, and then Anthropic follows that up by saying it had three: “Opus 4.7, Mythos 5, and an internal research test model”. Maybe another company is about to disclose they had, say, five models exploiting security vulnerabilities.

As with the OpenAI incident, the guardrails around Anthropic’s models were lowered and there were key misconfigurations in these evaluations. Nevertheless, these incidents represent real problems software vendors should begin taking seriously. Everything is now happening at barely comprehensible speeds at unprecedented volume.